Large Language Model

Auto Added by WPeMatico

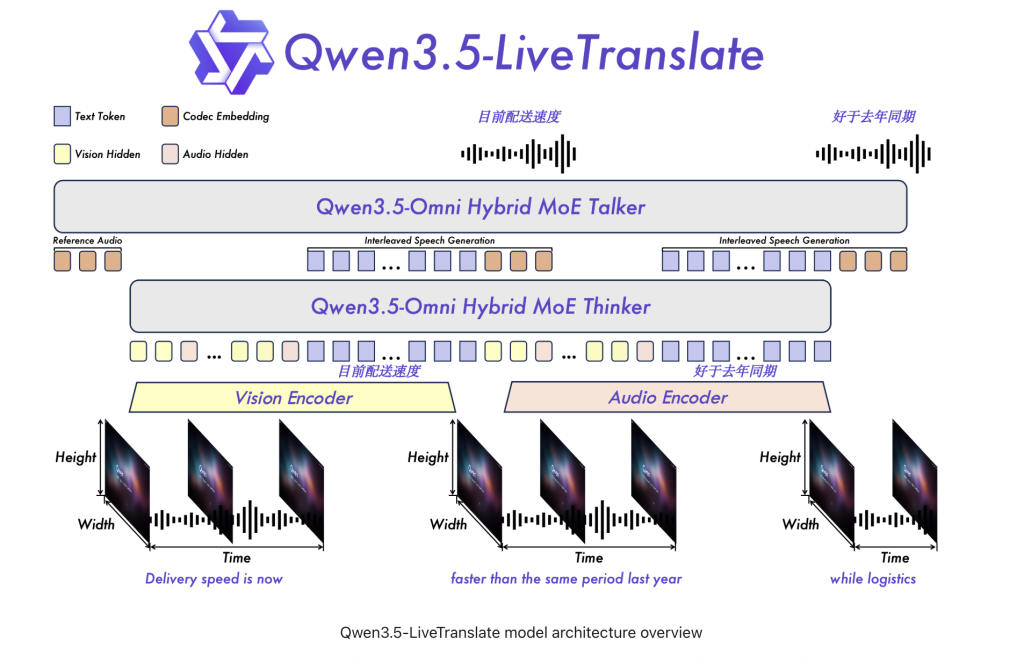
Alibaba Qwen Team Introduces Qwen3.5-LiveTranslate-Flash: Real-Time Multimodal Interpretation Across 60 Languages at 2.8-Second Latency

Simultaneous interpretation is one of the harder problems in applied AI. You’re asking a model to translate speech before the speaker has finished a sentence. Every extra second of delay breaks the illusion of real-time communication. Alibaba’s Qwen team has been chipping away at this with each release. Their latest model, Qwen3.5-LiveTranslate-Flash, brings that latency […]
Alibaba Qwen Team Introduces Qwen3.5-LiveTranslate-Flash: Real-Time Multimodal Interpretation Across 60 Languages at 2.8-Second Latency Read More »

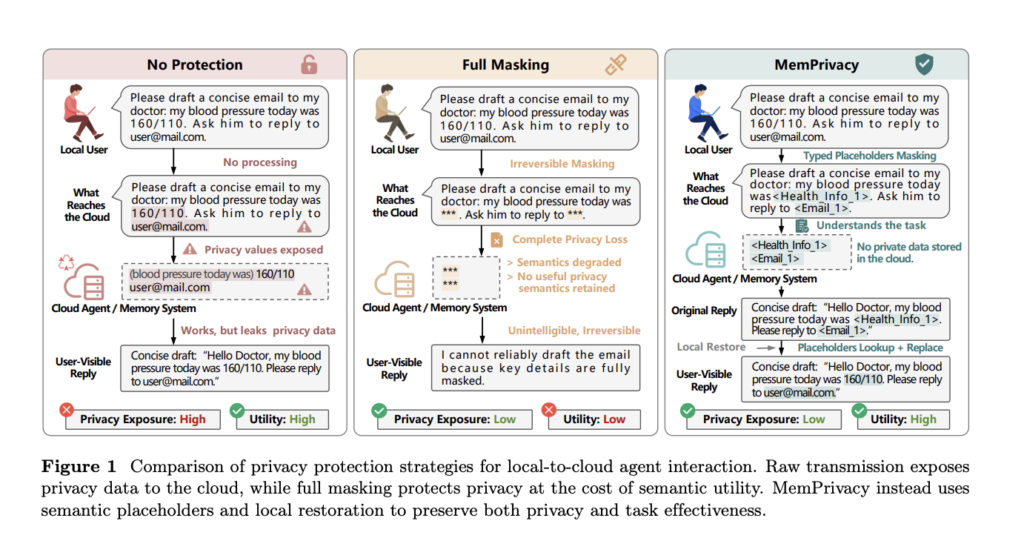
Meet MemPrivacy: An Edge-Cloud Framework that Uses Local Reversible Pseudonymization to Protect User Data Without Breaking Memory Utility

As LLM-powered agents move from research to production, one design tension is becoming harder to ignore: the more useful cloud-hosted memory becomes, the more private user data it exposes. Researchers from MemTensor (Shanghai), HONOR Device and Tongji University have introduced MemPrivacy, a framework that attempts to resolve this tension without sacrificing the utility that makes

Meet MemPrivacy: An Edge-Cloud Framework that Uses Local Reversible Pseudonymization to Protect User Data Without Breaking Memory Utility Read More »

Stochastic Gradient Descent (SGD’s) Frequency Bias and How Adam Fixes It 

Modern language models are trained on data with extremely uneven token distributions. A small number of words appear in almost every sentence, while many rare but meaningful tokens occur only occasionally. This creates a hidden optimization challenge: parameters associated with common tokens receive constant gradient updates, while parameters tied to rare tokens may go hundreds

Stochastic Gradient Descent (SGD’s) Frequency Bias and How Adam Fixes It  Read More »

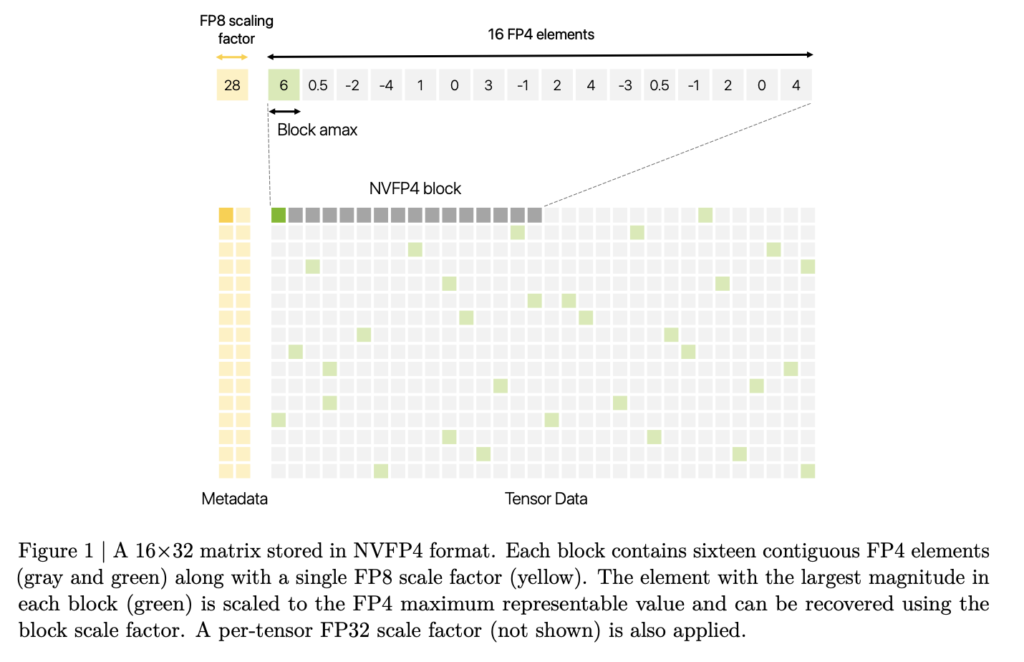
NVIDIA Introduces a 4-Bit Pretraining Methodology Using NVFP4, Validated on a 12B Hybrid Mamba-Transformer at 10T Token Horizon

Pretraining frontier-scale LLMs in FP8 is now standard practice, but moving to 4-bit floating point has remained an open research problem because narrower formats compress dynamic range and amplify quantization error at long token horizons. A new research from NVIDIA describes a pretraining methodology built around NVFP4, a 4-bit microscaling format supported natively by Blackwell

NVIDIA Introduces a 4-Bit Pretraining Methodology Using NVFP4, Validated on a 12B Hybrid Mamba-Transformer at 10T Token Horizon Read More »

A Coding Implementation to Compress and Benchmark Instruction-Tuned LLMs with FP8, GPTQ, and SmoothQuant Quantization using llmcompressor

In this tutorial, we explore how to apply post-training quantization to an instruction-tuned language model using llmcompressor. We start with an FP16 baseline and then compare multiple compression strategies, including FP8 dynamic quantization, GPTQ W4A16, and SmoothQuant with GPTQ W8A8. Along the way, we benchmark each model variant for disk size, generation latency, throughput, perplexity,

A Coding Implementation to Compress and Benchmark Instruction-Tuned LLMs with FP8, GPTQ, and SmoothQuant Quantization using llmcompressor Read More »

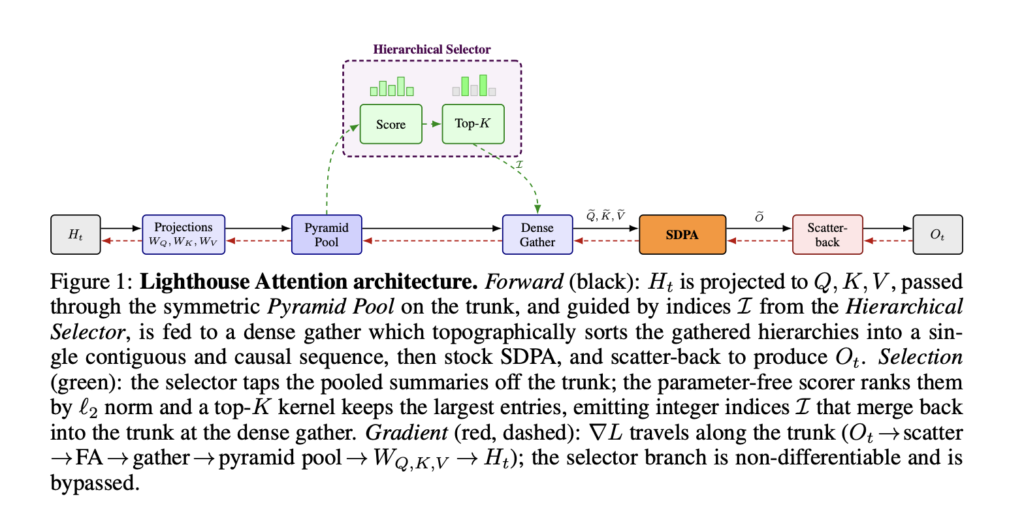
Nous Research Proposes Lighthouse Attention: A Training-Only Selection-Based Hierarchical Attention That Delivers 1.4–1.7× Pretraining Speedup at Long Context

Training large language models on long sequences has a well-known problem: attention is expensive. The scaled dot-product attention (SDPA) at the core of every transformer scales quadratically Θ(N²) in both compute and memory with sequence length N. FlashAttention addressed this through IO-aware tiling that avoids materializing the full N×N attention matrix in high-bandwidth memory, reducing

Nous Research Proposes Lighthouse Attention: A Training-Only Selection-Based Hierarchical Attention That Delivers 1.4–1.7× Pretraining Speedup at Long Context Read More »

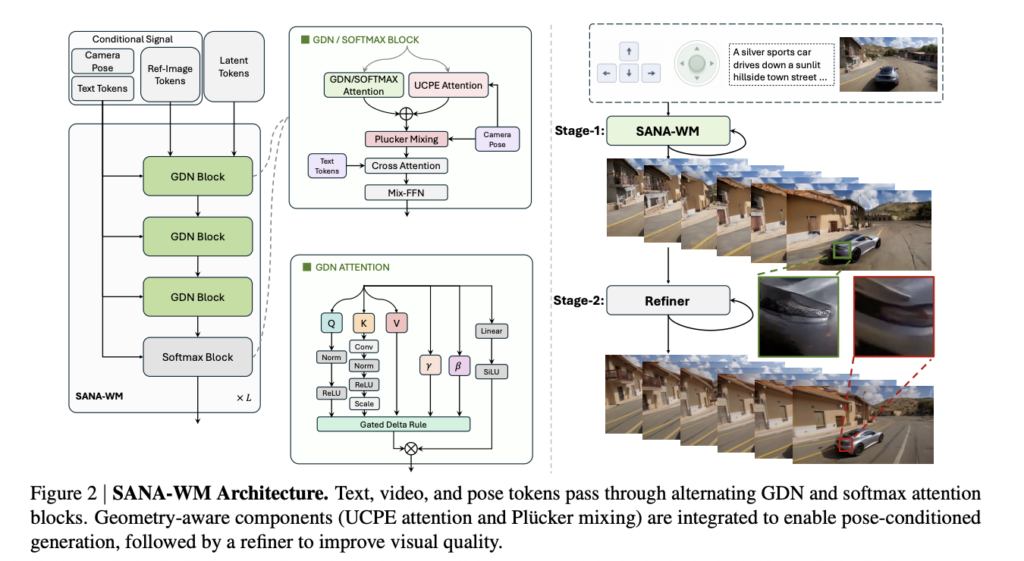
NVIDIA Introduces SANA-WM: A 2.6B-Parameter Open-Source World Model That Generates Minute-Scale 720p Video on a Single GPU

World models (systems that synthesize realistic video sequences from an initial image and a set of actions) are becoming central to embodied AI, simulation, and robotics research. The core challenge is scaling these systems to generate minute-long, high-resolution video without requiring prohibitively large clusters for both training and inference. Most competitive open-source baselines either require

NVIDIA Introduces SANA-WM: A 2.6B-Parameter Open-Source World Model That Generates Minute-Scale 720p Video on a Single GPU Read More »

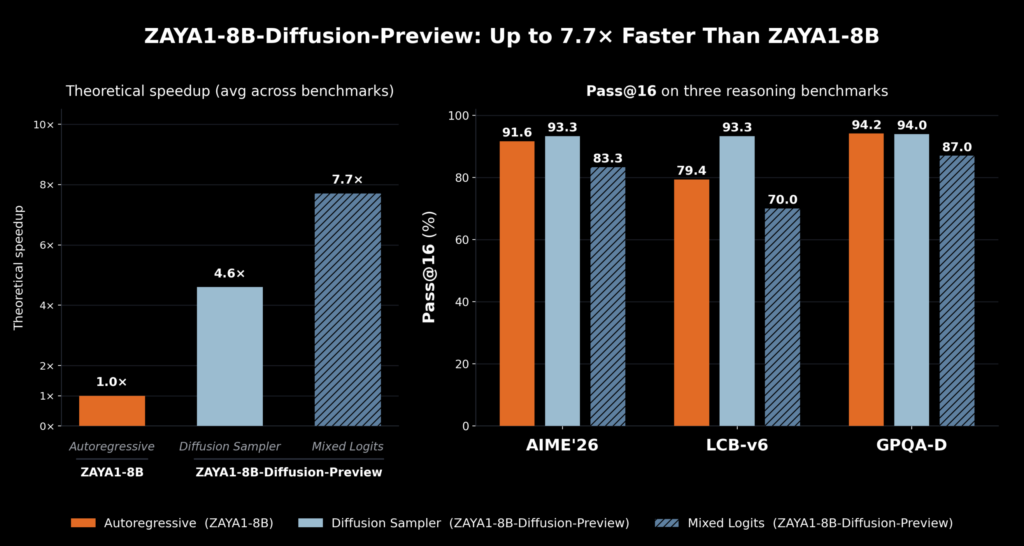
Zyphra Releases ZAYA1-8B-Diffusion-Preview: The First MoE Diffusion Model Converted From an Autoregressive LLM With Up to 7.7x Speedup

Zyphra, the San Francisco-based AI lab behind the ZAYA1 model family, released ZAYA1-8B-Diffusion-Preview — a preview of its early work in diffusion-language models. The release demonstrates that an existing autoregressive language model can be converted into a discrete diffusion model with no systematic loss of evaluation performance, while delivering substantial inference speedups on AMD hardware.

Zyphra Releases ZAYA1-8B-Diffusion-Preview: The First MoE Diffusion Model Converted From an Autoregressive LLM With Up to 7.7x Speedup Read More »

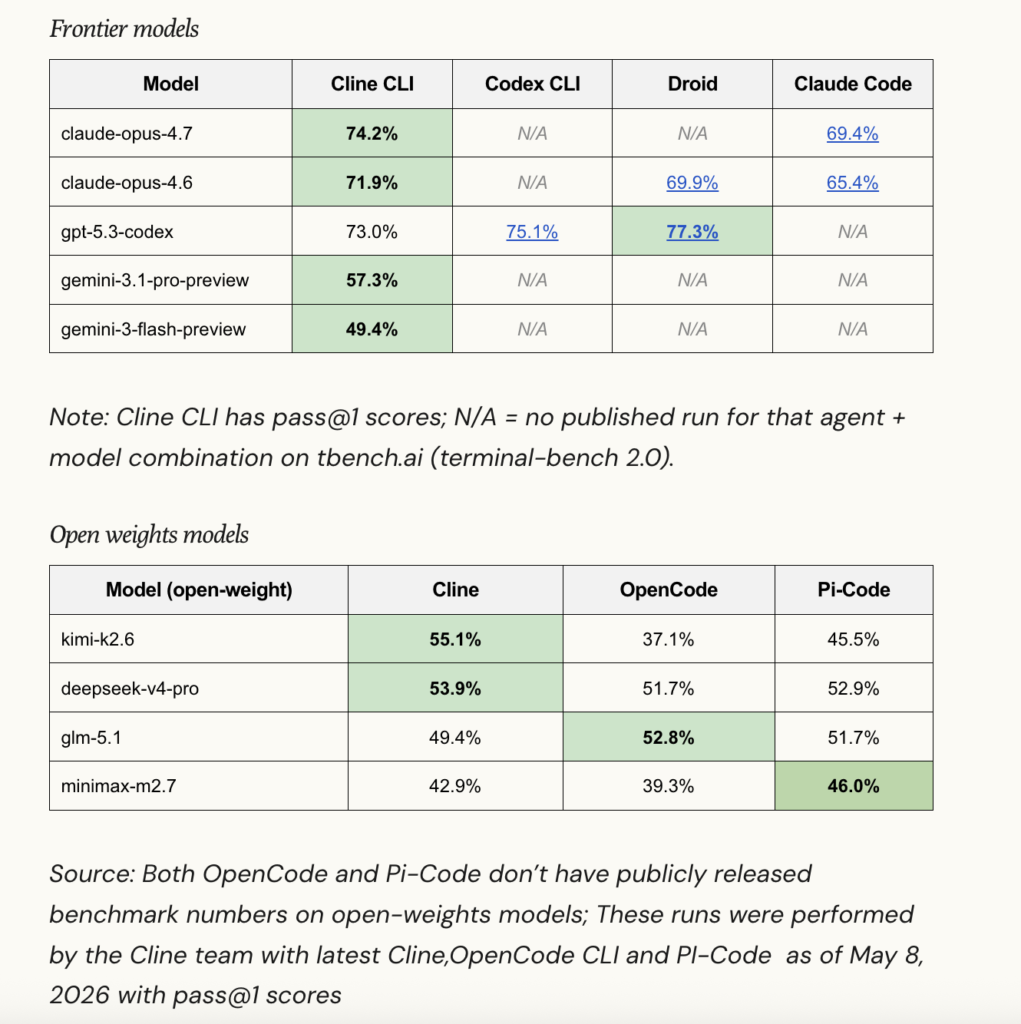
Cline Releases Cline SDK: An Open-Source Agent Runtime Now Powering Its CLI and Kanban, With IDE Extensions Being Migrated

Cline became ‘agentic’ before it was cool, but building on the bleeding edge usually leads to some structural debt. Over time, the agent loop and the VS Code extension became a package deal—making it a headache to maintain or move to new environments. Its tough to just keep layering features on a rigid core. Cline,

Cline Releases Cline SDK: An Open-Source Agent Runtime Now Powering Its CLI and Kanban, With IDE Extensions Being Migrated Read More »

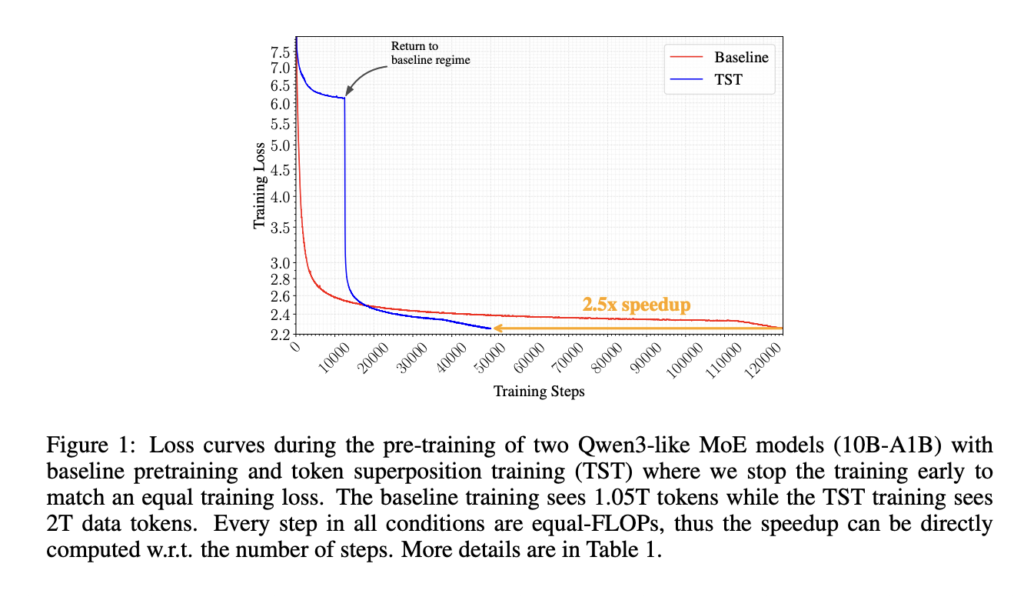
Nous Research Releases Token Superposition Training to Speed Up LLM Pre-Training by Up to 2.5x Across 270M to 10B Parameter Models

Pre-training large language models is expensive enough that even modest efficiency improvements can translate into meaningful cost and time savings. Nous Research is releasing Token Superposition Training (TST), a method that substantially reduces pre-training wall-clock time at fixed compute without touching the model architecture, optimizer, tokenizer, parallelism strategy, or training data. At the 10B-A1B mixture-of-experts

Nous Research Releases Token Superposition Training to Speed Up LLM Pre-Training by Up to 2.5x Across 270M to 10B Parameter Models Read More »