
LLMs

Auto Added by WPeMatico

Recursive Self-Improvement: The Last AI Built by Humans 

RSI or Recursive Self-improvement has been the talk of the town lately. The term came into surface when it was emphasized as the next step in the LLM evolution cycle by pioneers of the field like Sam Altman, Dario Amodei, and Elon musk. But also, via a research paper outlining the method titled: The Last AI Built by Humans. These two alone should help you realize […]

Recursive Self-Improvement: The Last AI Built by Humans  Read More »
Bodhan AI Releases Four Indic Models for OCR, Translation and Speech 

A Hindi lesson can mix English terms (loan words), scanned tables and handwritten equations. Making that content searchable, translating it and reading it aloud requires several kinds of AI. Bodhan AI and AI4Bharat’s four new models target those jobs across Indian languages.  Released in September 2026, the models cover document parsing, translation, speech recognition and speech generation, with support for mixed languages and scripts. In this

Bodhan AI Releases Four Indic Models for OCR, Translation and Speech  Read More »

GPT-6 Astra: What’s Actually New in OpenAI’s New Frontier Model

OpenAI has released GPT-6 Astra, its newest frontier model, less than a week after Anthropic’s Claude Fable 5.1. OpenAI calls Astra the world’s most intelligent and aligned model yet. What actually makes Astra different? The simplest way to put it is this: Astra is built to do more, not just answer more. It can use

GPT-6 Astra: What’s Actually New in OpenAI’s New Frontier Model Read More »

OpenCode Explained: The Open-Source AI Coding Agent

OpenCode is open source and works with any model, but those are no longer its most interesting features. Model choice is table stakes. What sets OpenCode apart is its architecture, and the trade-offs that come with it, especially if you are coming from Claude Code.  In this article, we look at what OpenCode is, what makes its architecture different, what

OpenCode Explained: The Open-Source AI Coding Agent Read More »

A Complete Guide to Decoding LLM Model Names

If you have ever tried downloading a local LLM, you have probably seen model names that look like this:  Qwen3.8-27B-A3B-It-2507-gguf-q2ks-mixed-AutoRound At first, it looks like meaningless technical shorthand.  It isn’t!  Every part of that name tells you something about the model: how large it is, how it is built, how much of it is used at a time, how

A Complete Guide to Decoding LLM Model Names Read More »

5 Best Local LLMs You Can Run on a Mac mini in 2026

Proprietary models are amazing! But sometimes what is of importance is configurability rather than raw power. This has led to the emergence of locally hosted models.  The Mac mini has emerged as a surprisingly capable machine for running AI locally. With Apple Silicon, enough unified memory, and tools like Ollama and LM Studio, users can now run capable models entirely on-device.  But

5 Best Local LLMs You Can Run on a Mac mini in 2026 Read More »

How to Use Kimi K3: Moonshot AI’s 2.8T Open-Weight Model

Moonshot AI’s Kimi K3 is a 2.8-trillion-parameter open-weight model built with a Mixture-of-Experts architecture. It activates only a small fraction of its parameters per token, helping reduce inference costs while delivering strong coding and agentic performance. K3 combines near-frontier capabilities, open weights, and lower API pricing, making it an interesting alternative to proprietary models. In

How to Use Kimi K3: Moonshot AI’s 2.8T Open-Weight Model Read More »

LLM services

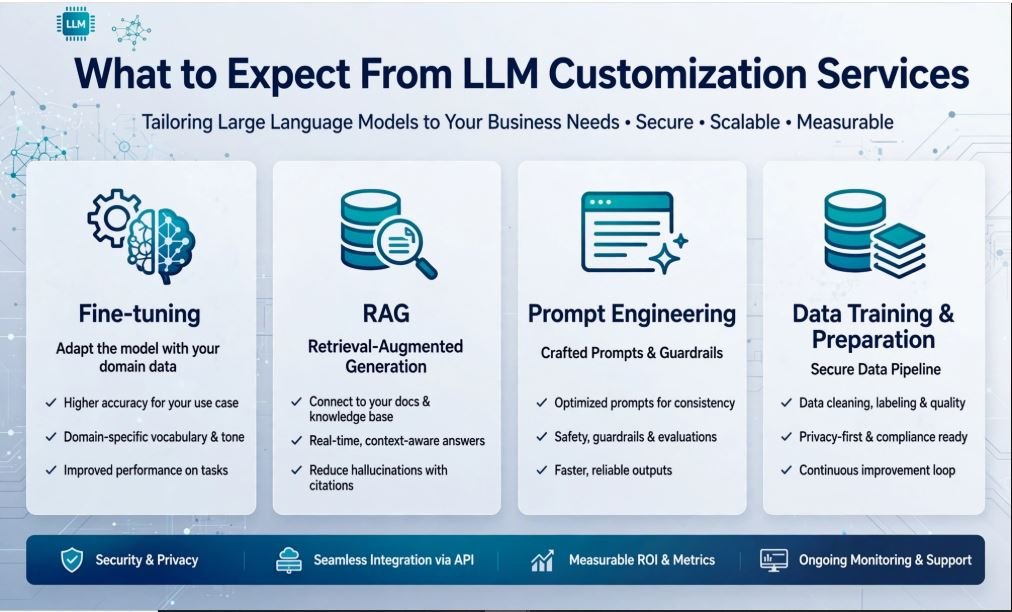
What to Expect From LLM Customization Services

LLM Customization services help organizations adapt language-model applications to specific business tasks, knowledge sources, terminology, workflows, and security requirements. The work can include prompt design, retrieval-augmented generation, tool integration, fine-tuning, evaluation, deployment, and continuous optimization. Customization should not begin with the assumption that a new model must be trained. In many cases, clearer instructions and

What to Expect From LLM Customization Services Read More »

PagedAttention vs. RadixAttention: Optimizing LLM KV Cache Management

Modern LLMs rely on quantization, pruning, distillation, and faster attention kernels, but production performance often depends most on KV cache management. As context windows grow, the cache consumes significant GPU memory, limiting concurrency, throughput, and latency. Two breakthroughs transformed this challenge: PagedAttention improves memory allocation, while RadixAttention enables efficient prefix reuse. Together, these techniques make

PagedAttention vs. RadixAttention: Optimizing LLM KV Cache Management Read More »