Embedding Model

Auto Added by WPeMatico

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page

Last week, Reducto announced r-1. It is the first model in a new parsing family built on a rewritten architecture, and it replaces the company’s multi stage agentic OCR with one full page pass. Reducto says r-1 is more accurate than its most powerful legacy agentic models, faster, and up to 6x cheaper. Is it […]

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page Read More »

Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot Manipulation Tasks and 50,129 Trajectories

Robot manipulation datasets have grown far slower than the models trained on them, mostly because collection stays closed and centralized. Expert operators gather demonstrations on lab hardware, process them offline, and ship a fixed benchmark that never grows again. A research team from Axis Robotics, UC Berkeley, Georgia Tech, NTU… is proposing a different shape

Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot Manipulation Tasks and 50,129 Trajectories Read More »

Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown

Cohere has released Parse (parse-v5.0), a document parsing model aimed at high-volume enterprise ingestion. It is a 2.3B-parameter vision language model with an 8,192-token context window and a ~4.6GB footprint, built on Cohere Labs’ North-Micro-Vision-Instruct architecture. Parse takes a PDF, PPT or JPEG page as a base64-encoded data URI and returns Markdown containing text in

Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown Read More »

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks for Long-Horizon Legal Agent Work

Harvey has released Harvey Tenet, its first post-trained model, as a research preview as of today. Tenet is a Kimi K3 base post-trained with Fireworks through asynchronous reinforcement learning on long-horizon legal work. The training corpus combined synthetic data, publicly available legal data, and human expert data. Harvey states no customer data was used. Against

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks for Long-Horizon Legal Agent Work Read More »

▶

Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million Hours of Human Video

Dyna Robotics has released Dyna-2, a world-action model for robot manipulation. It was pre-trained on more than one million hours of egocentric human video. That is roughly 170 years of continuous waking experience. Robot learning has been bottlenecked by action-labelled data, which teleoperation must deliberately produce. Dyna-2 tests whether ordinary human video can substitute. The

Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million Hours of Human Video Read More »

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with 3B Active Parameters, and NeMo Switchyard Model Router

NVIDIA introduced open technologies for building always-on AI agents from systems of specialized models. Two artifacts shipped together. Nemotron 3.5 Lightning is a lightweight, customizable open model built for high-volume agentic tasks, and NeMo Switchyard is an open source routing library that directs each step of an agent workflow to the most capable and efficient

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with 3B Active Parameters, and NeMo Switchyard Model Router Read More »

NVIDIA Releases Alpamayo 2 Super: A 34B Open Vision-Language-Action Model for Robotaxis and Autonomous Driving Under OpenMDW-1.1

NVIDIA has released Alpamayo 2 Super, a 34B-parameter vision-language-action (VLA) model for autonomous driving, under an open commercial license. The stated design target is the long-tail events: rare, multi-agent situations that conventional detection-and-prediction stacks handle poorly. The model pairs a 32B VLM backbone, built on NVIDIA Cosmos 3 Super Reasoner and post-trained with reinforcement learning,

NVIDIA Releases Alpamayo 2 Super: A 34B Open Vision-Language-Action Model for Robotaxis and Autonomous Driving Under OpenMDW-1.1 Read More »

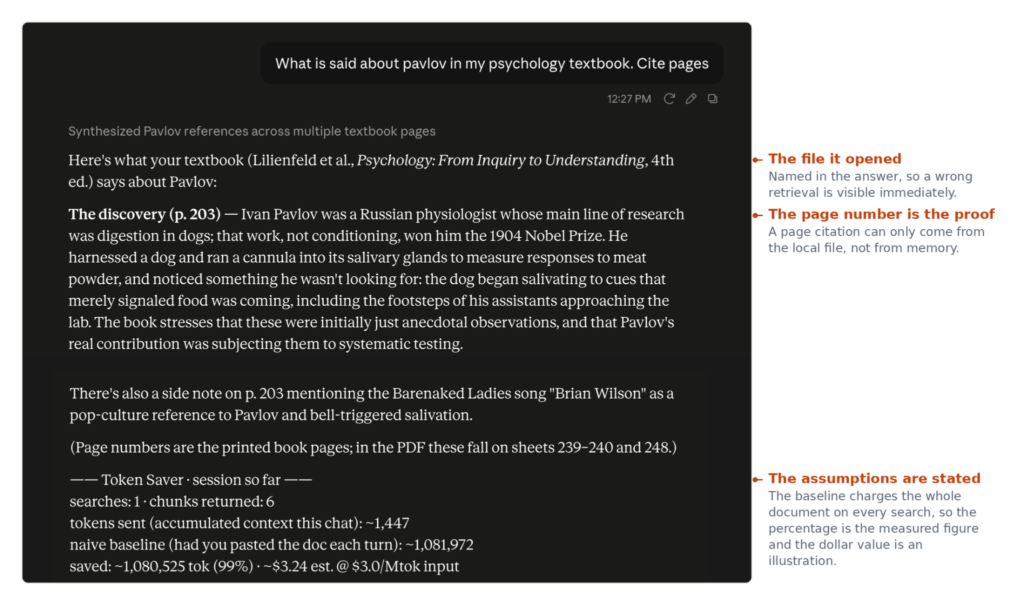
Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG to Cut Claude PDF Token Costs 90-99%

AI developers, researchers, and professionals frequently hit a frustrating wall when analyzing large documents with LLMs: the hidden, compounding cost of context windows. Pasting a 200-page PDF into a chat isn’t a one-time charge. Because the conversation history is re-sent to the model on every single turn, that massive document is paid for again with

Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG to Cut Claude PDF Token Costs 90-99% Read More »

Meet Open Dreamer: A JAX/Flax Reproduction of the Dreamer 4 World Model Pipeline, With the Full Training Recipe Published

A small group of AI researchers (Reactor) have released Open Dreamer, an open implementation of the Dreamer 4 world-model pipeline written in JAX and Flax NNX. What actually shipped Two repositories were released. next-state/open-dreamer holds the training pipeline: a causal video tokenizer, an action-conditioned latent dynamics model, rollout generation, and FVD scoring. reactor-team/open-dreamer holds a

Meet Open Dreamer: A JAX/Flax Reproduction of the Dreamer 4 World Model Pipeline, With the Full Training Recipe Published Read More »

Best Local LLMs You Can Run on a Single 24GB GPU in 2026: Qwen, Gemma, Mistral, DeepSeek Compared

A single 24GB card is the practical floor for serious local inference. It is enough for genuinely capable models, and small enough to sit on one GPU. An RTX 3090 or RTX 4090 both land in this tier. The card you own matters less than the models you pick for it. The old hobbyist move

Best Local LLMs You Can Run on a Single 24GB GPU in 2026: Qwen, Gemma, Mistral, DeepSeek Compared Read More »