Data Labeling

Auto Added by WPeMatico

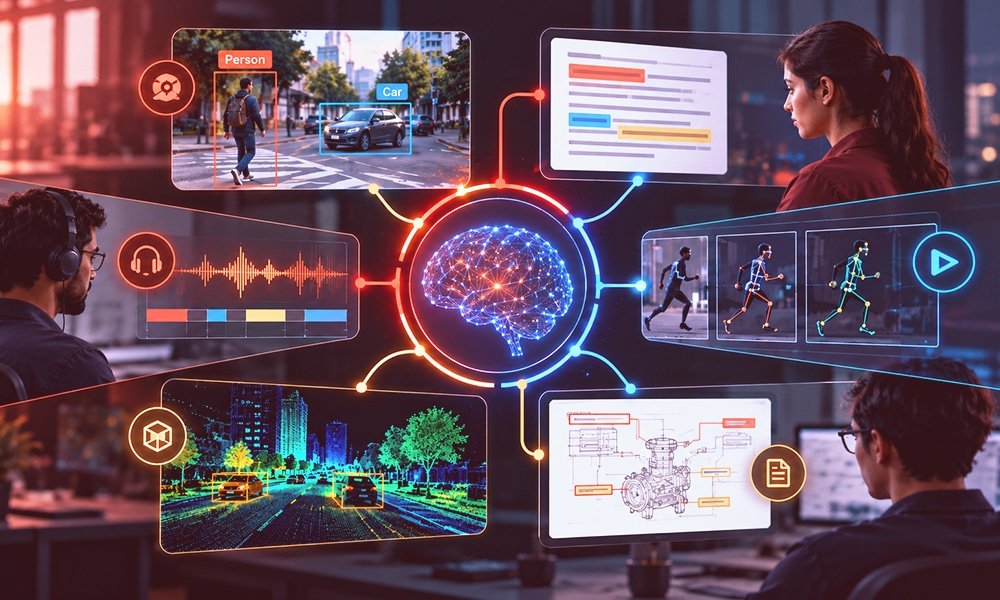
Multimodal Annotation

Multimodal Annotation: Why Each Modality Demands a Different Strategy

Here is a finding that should change how you scope video projects. In a widely used multimodal video dataset, clips labelled as containing hateful content averaged 2.56 minutes in length — but the actually hateful segments averaged only 1.71 minutes. Roughly a third of the content inside those positively labelled videos did not match the

Multimodal Annotation: Why Each Modality Demands a Different Strategy Read More »
Best Mechanical Turk Alternatives in 2026 for Data Labeling, Collection and LLM Evaluation

For 21 years, the default answer to “we need humans to label this” was a crowd marketplace. That default ends on September 30, 2026, when Amazon Mechanical Turk closes for good. If your labeling queues, survey panels, or model-evaluation loops still run through it, you now need one of the Mechanical Turk alternatives below, and

Best Mechanical Turk Alternatives in 2026 for Data Labeling, Collection and LLM Evaluation Read More »

Data Annotation Outsourcing

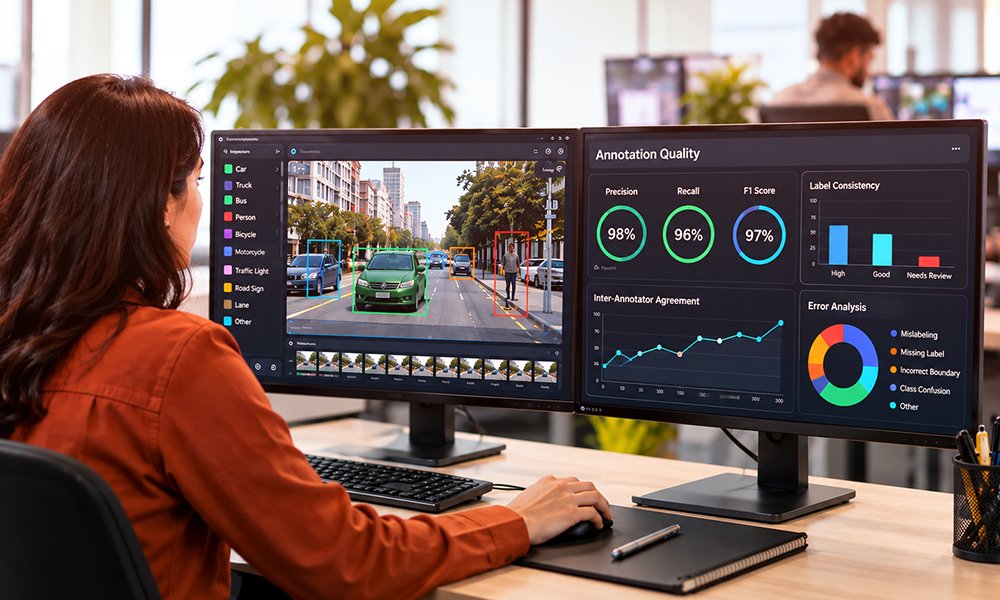
Data Annotation Outsourcing in 2026: How to Measure Annotation Quality Before You Commit

Most teams don’t start looking into data annotation outsourcing because they want to. They start because an in-house pilot worked — forty thousand images, three interns, a spreadsheet of guidelines — and then someone asked for two million images by Q3, in four languages, with an audit trail. That’s the moment the question changes. It

Data Annotation Outsourcing in 2026: How to Measure Annotation Quality Before You Commit Read More »

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the Database Before Writing a Query

Most text-to-SQL systems treat the task as translation. Feyn AI (YC-backed startup) reframes it around inspection. The Feyn team has released SQRL, a family of models that turn natural language questions into SQL. Instead of generating a query immediately, SQRL can inspect the database first. This lets it resolve ambiguity and write only queries the

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the Database Before Writing a Query Read More »

How to Build an Advanced, Interactive Exploratory Data Analysis Workflow Using PyGWalker and Feature-Engineered Data

In this tutorial, we demonstrate how to move beyond static, code-heavy charts and build a genuinely interactive exploratory data analysis workflow directly using PyGWalker. We start by preparing the Titanic dataset for large-scale interactive querying. These analysis-ready engineered features reveal the underlying structure of the data while enabling both detailed row-level exploration and high-level aggregated

How to Build an Advanced, Interactive Exploratory Data Analysis Workflow Using PyGWalker and Feature-Engineered Data Read More »

In-House vs Crowdsourced vs Outsourced Data Labeling: Pros, Cons, & the “Right Fit” Framework

Choosing a data labeling model looks simple on paper: hire a team, use a crowd, or outsource to a provider. In practice, it’s one of the most leverage-heavy decisions you’ll make—because labeling affects model accuracy, iteration speed, and the amount of engineering time you burn on rework. Organizations often notice labeling problems after model performance

In-House vs Crowdsourced vs Outsourced Data Labeling: Pros, Cons, & the “Right Fit” Framework Read More »

The A To Z Of Data Annotation

What is Data Annotation [2026 Updated] – Best Practices, Tools, Benefits, Challenges, Types & more Need to know the Data Annotation basics? Read this complete Data Annotation guide for beginners to get started. Table of Contents Download eBook Get My Copy Curious how self-driving cars, medical imaging models, LLM copilots or voice assistants get so

The A To Z Of Data Annotation Read More »

What is Multimodal Data Labeling? Complete Guide 2025

The rapid advancement of AI models like OpenAI’s GPT-4o and Google’s Gemini has revolutionized how we think about artificial intelligence. These sophisticated systems don’t just process text—they seamlessly integrate images, audio, video, and sensor data to create more intelligent and contextual responses. At the heart of this revolution lies a critical process: multimodal data labeling.

What is Multimodal Data Labeling? Complete Guide 2025 Read More »

In-House vs Crowdsourced vs Outsourced Data Labeling: Pros, Cons, & the “Right Fit” Framework

Choosing a data labeling model looks simple on paper: hire a team, use a crowd, or outsource to a provider. In practice, it’s one of the most leverage-heavy decisions you’ll make—because labeling affects model accuracy, iteration speed, and the amount of engineering time you burn on rework. Organizations often notice labeling problems after model performance

In-House vs Crowdsourced vs Outsourced Data Labeling: Pros, Cons, & the “Right Fit” Framework Read More »

What is Multimodal Data Labeling? Complete Guide 2025

The rapid advancement of AI models like OpenAI’s GPT-4o and Google’s Gemini has revolutionized how we think about artificial intelligence. These sophisticated systems don’t just process text—they seamlessly integrate images, audio, video, and sensor data to create more intelligent and contextual responses. At the heart of this revolution lies a critical process: multimodal data labeling.

What is Multimodal Data Labeling? Complete Guide 2025 Read More »