Big Data

Auto Added by WPeMatico

The datacentre next door: on the frontline of tech’s latest David v Goliath battle

The AI boom is pitting local residents against corporate giants seeking to power their energy-hungry networks – but one Welsh city is fighting backDale Johnston opens the gate to his neat suburban garden on the western fringes of Newport in South Wales. There’s a trampoline and a slide on the lawn for his grandchildren, and

The datacentre next door: on the frontline of tech’s latest David v Goliath battle Read More »
How to Make Zero-Training Tabular Predictions with NVIDIA Structured Data Models

In this tutorial, we implement Structured Data Models, NVIDIA’s new library that puts several pretrained foundation models for tables behind one PyTorch interface, and use it to make predictions without training. The library wraps TabICLv2 and KumoTabular for single tables and KumoRelational for whole relational databases, and each of them answers by in-context learning: we

How to Make Zero-Training Tabular Predictions with NVIDIA Structured Data Models Read More »

Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For Multivariate Time Series Forecasting

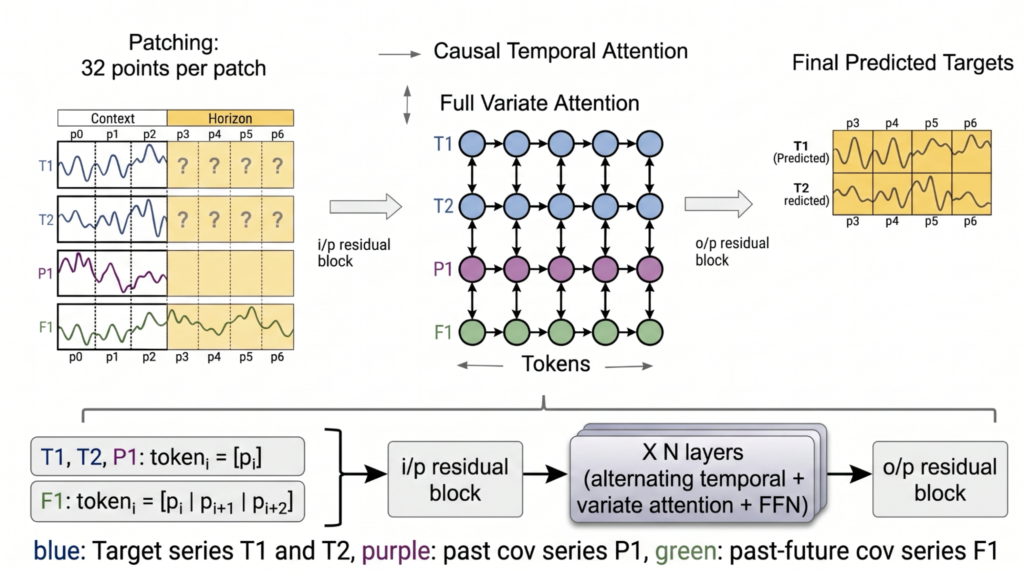
Google Research has released TimesFM-3, a 330 million parameter time series foundation model that forecasts multiple related series in a single forward pass. Every TimesFM checkpoint through 2.5 was univariate: one series, its own history, nothing else. TimesFM-3 is pretrained natively for multivariate forecasting on more than 1 trillion time points, and accepts multiple targets,

Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For Multivariate Time Series Forecasting Read More »

Scientific Data Analysis with LabPlot in Python: Signal Processing, Spectral Peak Fitting, Visualization, and Batch Automation

In this tutorial, we explore a LabPlot-inspired scientific data analysis workflow in Python while preserving the structure and terminology of LabPlot’s aspect tree, analysis kernels, plotting system, and project model. We build reusable components to import tabular data, compute descriptive statistics, smooth and differentiate signals, perform Fourier analysis and filtering, detect peaks, integrate curves, reduce

Scientific Data Analysis with LabPlot in Python: Signal Processing, Spectral Peak Fitting, Visualization, and Batch Automation Read More »

✅

Building and Validating a Quantitative Trading Strategy with OctoBot, Walk-Forward Backtesting, Parameter Optimization, and Interactive Analysis

In this tutorial, we build a complete quantitative backtesting workflow with OctoBot and OctoBot-Script while keeping the environment isolated from Colab’s preinstalled dependencies. We configure a rule-based trading strategy that combines RSI-based oversold signals, EMA trend confirmation, and ATR-driven adaptive stop-loss and take-profit levels, and we execute it through OctoBot’s native market-order and backtesting APIs.

Building and Validating a Quantitative Trading Strategy with OctoBot, Walk-Forward Backtesting, Parameter Optimization, and Interactive Analysis Read More »

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the Database Before Writing a Query

Most text-to-SQL systems treat the task as translation. Feyn AI (YC-backed startup) reframes it around inspection. The Feyn team has released SQRL, a family of models that turn natural language questions into SQL. Instead of generating a query immediately, SQRL can inspect the database first. This lets it resolve ambiguity and write only queries the

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the Database Before Writing a Query Read More »

✅

A Coding Implementation on Spatial Graph Neural Networks for Urban Function Inference Using city2graph, OSMnx, and PyTorch Geometric

In this tutorial, we build an end-to-end spatial graph learning pipeline using city2graph. We start by collecting real urban POI data and street network information from OpenStreetMap, with a synthetic fallback to ensure the workflow remains reliable. We then engineer spatial features, construct multiple proximity graph families, and compare how different graph-building strategies represent the

A Coding Implementation on Spatial Graph Neural Networks for Urban Function Inference Using city2graph, OSMnx, and PyTorch Geometric Read More »

✅

Building a Code Dataset Pipeline from NVIDIA Nemotron-Pretraining-Code-v3 Metadata with Streaming, Pandas, and tiktoken

In this tutorial, we work with NVIDIA’s Nemotron-Pretraining-Code-v3 dataset as a large-scale metadata index for code pretraining research. Instead of downloading the full multi-gigabyte dataset, we stream it, inspect its schema, and build a manageable sample for analysis. We then explore the dataset by studying languages, file extensions, repository frequency, and directory depth, which helps

Building a Code Dataset Pipeline from NVIDIA Nemotron-Pretraining-Code-v3 Metadata with Streaming, Pandas, and tiktoken Read More »

✅

A Coding Guide to Implement a pgvector-Powered Semantic, Hybrid, Sparse, and Quantized Vector Search System

In this tutorial, we build a complete pgvector playground inside Google Colab and explore how PostgreSQL can work as a powerful vector database for modern AI applications. We start by installing PostgreSQL, compiling the pgvector extension, connecting through Psycopg, and registering vector types for smooth Python integration. Then, we create embeddings with SentenceTransformers, store them

A Coding Guide to Implement a pgvector-Powered Semantic, Hybrid, Sparse, and Quantized Vector Search System Read More »

PySpark Optimization: 12 Proven Techniques to Speed Up Your Spark Jobs

Modern data pipelines handle massive volumes of structured and unstructured data every day. As datasets grow, poorly optimized Spark jobs become slower, more expensive, and harder to scale. Common issues include long execution times, excessive shuffling, memory bottlenecks, and inefficient joins. Effective PySpark optimization can significantly improve performance, reduce infrastructure costs, and enhance cluster efficiency.

PySpark Optimization: 12 Proven Techniques to Speed Up Your Spark Jobs Read More »