Healthcare benchmarks are only as good as their assumptions
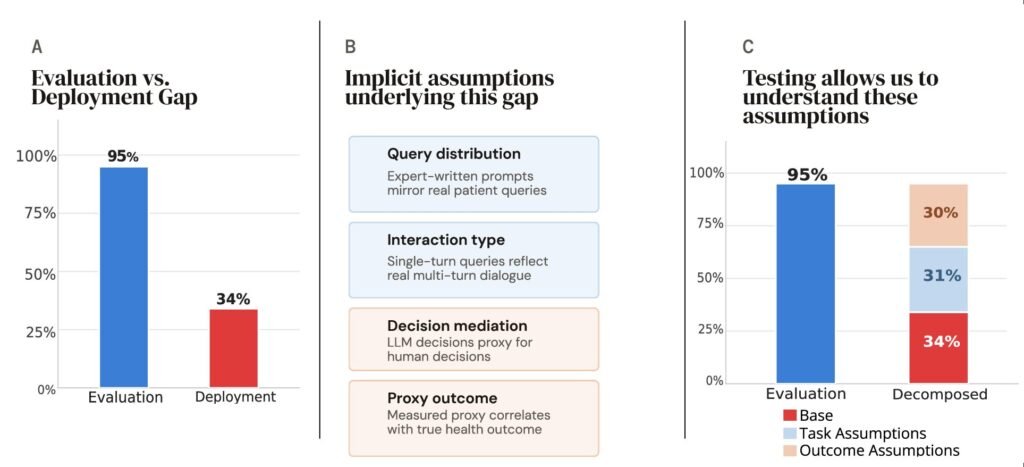
In healthcare settings where patients use LLMs as a medical assistant, LLM performance differs between evaluation and deployment. (a) Bean et al. (2025) find a 61 percentage point difference between evaluation and deployment. (b) We argue this gap arises not from poorly designed benchmarks, but from implicit assumptions embedded in evaluation protocols that fail to
Healthcare benchmarks are only as good as their assumptions Read More »