TTS

Auto Added by WPeMatico

▶

Edge0 Releases Audio8-TTS-Realistic, a 0.6B Voice Cloning TTS Model

Edge0 has released Audio8-TTS-Realistic, an open-weight text-to-speech model for zero-shot voice cloning. Audio8-TTS-Realistic is a 0.6B-parameter model that clones a voice from 1 reference clip and transcript. It supports 23 languages, 12 more than its predecessor. The weights and code ship under Apache 2.0. For developers, the catch is competitive multilingual accuracy at a size

Edge0 Releases Audio8-TTS-Realistic, a 0.6B Voice Cloning TTS Model Read More »

▶

Gradium Open-Sources Phonon, a 31M-Parameter On-Device TTS Model Under Apache 2.0

Gradium has open-sourced Phonon, a family of small text-to-speech models built to run on the device. The Gradium Phonon on-device TTS model comes in 31M and 40M sizes. The English Phonon 31m ships under Apache 2.0 and fits in a 64.5 MB file. Developers get natural speech with no cloud call, no GPU and no

Gradium Open-Sources Phonon, a 31M-Parameter On-Device TTS Model Under Apache 2.0 Read More »

▶

Meet Grok Voice 3.0: SpaceXAI Voice Agent Model Ranks #1 on Artificial Analysis

SpaceXAI just released Grok Voice 3.0. Grok Voice 3.0 is a SpaceXAI speech-to-speech model that listens, reasons, calls tools and speaks. It now ranks first on the Artificial Analysis Speech-to-Speech Index with a score of 86.9. For developers, the endpoint, events and $0.08 per minute price are unchanged from Grok Voice 2.0. TL;DR Runs on:

Meet Grok Voice 3.0: SpaceXAI Voice Agent Model Ranks #1 on Artificial Analysis Read More »

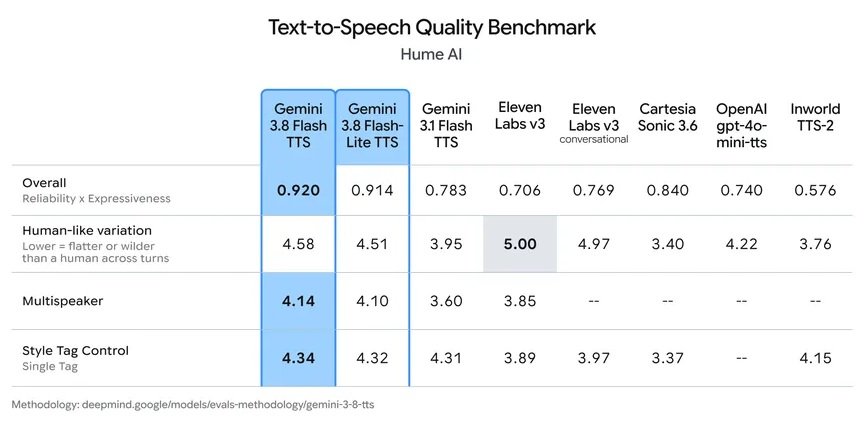
Text-to-Speech Quality benchmark of Gemini 3.8 Flash TTS against rival AI models.

Google launches Gemini 3.8 Flash TTS voice models

Google has launched two Gemini 3.8 Flash TTS voice models, introducing dedicated speech generation systems engineered for direct performance scripting and high-volume audio production. The dual release splits vocal synthesis tasks between creative direction and cost-managed infrastructure. Gemini 3.8 Flash TTS targets interactive entertainment, game development, and long-form narrations where studio teams demand prompt-based vocal

Google launches Gemini 3.8 Flash TTS voice models Read More »

Meet S1-mini: Superwhisper’s 462 MB Open-Weights Text Normalizer That Turns Raw ASR Transcripts Into Clean Written Text

Superwhisper has released the S1 family of models: S1-Voice, S1-Language, and S1-mini. S1-Voice is a cloud speech-to-text model, and S1-Language is a cloud instruction-following model for cleanup and formatting. The one that is quite interesting outside the app is S1-mini, released with open weights on Hugging Face. S1-mini is a 0.6B text normalizer, not a

Meet S1-mini: Superwhisper’s 462 MB Open-Weights Text Normalizer That Turns Raw ASR Transcripts Into Clean Written Text Read More »

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas

Cartesia has released Sonic-3.6, the newest version of its real-time text-to-speech model. It arrives roughly three months after Sonic-3.5. The new change is naturalness, and this one is independently checkable. Sonic 3.6 now holds #1 on both Artificial Analysis speech leaderboards — 1,283 Elo on the Provider Voice board and 1,123 on the Controlled Voice

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas Read More »

PolyAI Releases Dialog-RSN-1: An Audio-Native Dialog Model That Fuses Turn-Taking, Speech Recognition, Function Calling, And Response

PolyAI has introduced Dialog-RSN-1, a dialog model that perceives the caller’s audio directly instead of reading a transcript. It fuses turn-taking, speech recognition, function calling and response generation into one audio-native model, and is already handling live production calls. Key Takeaways Dialog-RSN-1 is audio-aware on the input side only; TTS stays separate, so the output

PolyAI Releases Dialog-RSN-1: An Audio-Native Dialog Model That Fuses Turn-Taking, Speech Recognition, Function Calling, And Response Read More »

Alibaba’s Tongyi Lab Releases Qwen-Audio-3.0-TTS, a Hosted Text-to-Speech Model in Flash and Plus Tiers Across 16 Languages

Alibaba’s Tongyi Lab has released Qwen-Audio-3.0-TTS, a production-oriented text-to-speech (TTS) system. The model ships in two variants from the same lineage. Flash targets real-time interaction. Plus targets high-quality generation. Both are delivered as hosted models through Alibaba Cloud Model Studio, not as downloadable weights. The release focuses on four things developers hit in production: broader

Alibaba’s Tongyi Lab Releases Qwen-Audio-3.0-TTS, a Hosted Text-to-Speech Model in Flash and Plus Tiers Across 16 Languages Read More »

▶

Kyutai Releases MuScriptor: An Open-Weight Decoder-Only Transformer for Multi-Instrument Music Transcription to MIDI

Automatic Music Transcription (AMT) converts an audio recording into symbolic notes, usually MIDI. Single-instrument transcription already works reasonably well. However, transcribing a full multi-instrument mix stays difficult. Kyutai and Mirelo team now release MuScriptor to close that gap. It is an open-weight model trained on real, multi-instrument recordings across many genres. This article explains how

Kyutai Releases MuScriptor: An Open-Weight Decoder-Only Transformer for Multi-Instrument Music Transcription to MIDI Read More »

OpenAI Releases GPT-Realtime-2.1 and GPT-Realtime-2.1-mini for Low-Latency Voice Agents in the API

OpenAI has released two new Realtime models in its API. They are named gpt-realtime-2.1 and gpt-realtime-2.1-mini. Both target low-latency voice and multimodal experiences. The mini model is the notable part of this release. It is a mini reasoning model for realtime voice. It ships at the same cost as the earlier gpt-realtime-mini. OpenAI also reduced

OpenAI Releases GPT-Realtime-2.1 and GPT-Realtime-2.1-mini for Low-Latency Voice Agents in the API Read More »