
Python

Auto Added by WPeMatico

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

Linkup research team releases SPARSEUP, an open-source learned sparse embedding model. The model runs on a 149M-parameter ModernBERT backbone and ships under Apache 2.0. Linkup team reports 56.4 average nDCG@10 on BEIR-13. It calls this the strongest public vocabulary-based sparse encoder it knows of under 150M parameters. Is it deployable? Yes. The weights are on […]

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model Read More »
Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs

Jina AI, part of Elastic, has released jina-ocr-v1, an end-to-end visual document parser. It takes PDFs, scans, tables, charts or invoices and returns clean Markdown in 1 pass. The model has 3.4B total parameters, with about 570M decoder parameters active per token. A speculative decoding head ships inside the checkpoint. Jina AI built it to

Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs Read More »

Microsoft Open-Sources TauGrid: A Kubernetes-Native Stack for GPU AI Workloads

Platform teams running AI on Kubernetes rarely run one thing. They run a queueing system, a distributed runtime, GPU node health checks, dashboards, and a layer of submission scripts holding all of it together. The Azure Kubernetes Service engineering team open-sourced TauGrid, which collapses that assembly job into a single Helm install. Is it deployable?

Microsoft Open-Sources TauGrid: A Kubernetes-Native Stack for GPU AI Workloads Read More »

Knowledgator Releases GLiFormer: A 575M-Parameter Encoder That Hits 91.10 F1 on Nested JSON Extraction Without Generating Tokens

Knowledgator Engineering has released GLiFormer, a schema-conditioned encoder framework for information extraction. One model handles named-entity recognition (NER), text classification, relation extraction, nested JSON structuring, and text embeddings. You pass labels and extraction schemas at inference time. Two checkpoints are on Hugging Face. GLiFormer Base v1 has 264.2M parameters, and GLiFormer Large v1 has 575.6M.

Knowledgator Releases GLiFormer: A 575M-Parameter Encoder That Hits 91.10 F1 on Nested JSON Extraction Without Generating Tokens Read More »

Fly Language Model (FLM) Wires the Full Fruit Fly Connectome Into a Frozen 1.2B LLM, and Its Own Controls Show the Wiring Does Not Help

The Fly Language Model (FLM) is a public chatbot that couples the complete retained MaleCNS v1.0 fruit fly connectome to a frozen LiquidAI LFM2.5-1.2B-Instruct backbone. The developer who created the FLM calls it the world’s first Fly Language Model, built on an architecture called GPF (Generative Pre-trained Fly). It does not use the GPF label,

Fly Language Model (FLM) Wires the Full Fruit Fly Connectome Into a Frozen 1.2B LLM, and Its Own Controls Show the Wiring Does Not Help Read More »

Sakana AI Launches Fugu Max and Fugu Ultra v2 for Cheaper, Stronger Multi-Agent Orchestration

Sakana AI has released Fugu Max and Fugu Ultra v2, 2 new models in its Sakana Fugu family. Fugu is not a single foundation model. It is a learned orchestrator that routes work across a pool of other models behind 1 API. The new release tunes that architecture for 2 missions. Fugu Max targets the

Sakana AI Launches Fugu Max and Fugu Ultra v2 for Cheaper, Stronger Multi-Agent Orchestration Read More »

NVIDIA Details BioNeMo Inference Runtime (BioIR): 2.90x Higher Boltz-2 Folding Throughput and 58.5K Residues per GPU-Hour on 8xH100

Biomolecular structure prediction has shifted from single-target runs to proteome-scale worklists. The bottleneck is no longer whether a model can fold a protein. It is how fast an entire queue of independent targets moves through parsing, featurization, GPU inference, and output writing. NVIDIA’s new technical deep dive walks through BioNeMo Inference Runtime (BioIR), a Python

NVIDIA Details BioNeMo Inference Runtime (BioIR): 2.90x Higher Boltz-2 Folding Throughput and 58.5K Residues per GPU-Hour on 8xH100 Read More »

LandingAI Releases Agentic Document Extraction Gen2 with DPT-3 Pro and DPT-3 Verity

LandingAI has shipped Agentic Document Extraction (ADE) Gen2, a rebuild of its document intelligence stack around a new model family called DPT-3. Gen1 treated a document as a flat list of chunks. Gen2 treats it as a tree, prices it by the characters it returns rather than by the page, and grounds every answer back

LandingAI Releases Agentic Document Extraction Gen2 with DPT-3 Pro and DPT-3 Verity Read More »

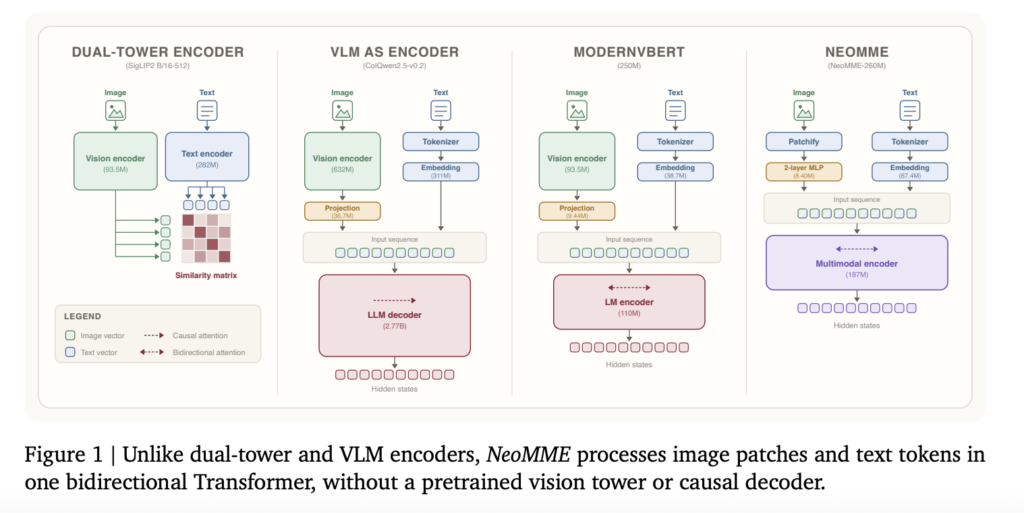
H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder

Most visual document retrievers in production today are hand-me-downs. ColPali and the models that followed it take a generative vision-language model and repurpose it as an encoder. The result still carries a separately pretrained vision tower and a causal decoder that never generates a token. That is parameter and compute overhead for a task that

H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder Read More »

GitHub Introduces Project HydraFusion: Runtime Multi-Model Orchestration That Builds a Workflow Per Coding Task in Copilot CLI

GitHub has released Project HydraFusion, a research preview that stops treating model choice as a one-time setting. Instead of routing your prompt to a single model, HydraFusion builds an execution plan per request. It can draft with one model, have a second model critique the draft, or escalate to a stronger model when a quality

GitHub Introduces Project HydraFusion: Runtime Multi-Model Orchestration That Builds a Workflow Per Coding Task in Copilot CLI Read More »