Data Science

Auto Added by WPeMatico

Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For Multivariate Time Series Forecasting

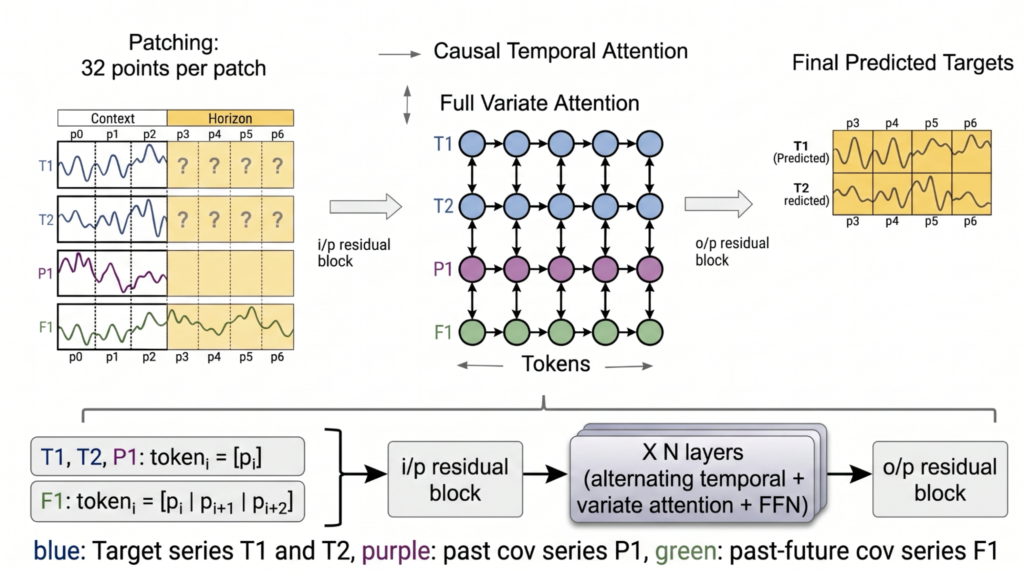
Google Research has released TimesFM-3, a 330 million parameter time series foundation model that forecasts multiple related series in a single forward pass. Every TimesFM checkpoint through 2.5 was univariate: one series, its own history, nothing else. TimesFM-3 is pretrained natively for multivariate forecasting on more than 1 trillion time points, and accepts multiple targets, […]

Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For Multivariate Time Series Forecasting Read More »

Scientific Data Analysis with LabPlot in Python: Signal Processing, Spectral Peak Fitting, Visualization, and Batch Automation

In this tutorial, we explore a LabPlot-inspired scientific data analysis workflow in Python while preserving the structure and terminology of LabPlot’s aspect tree, analysis kernels, plotting system, and project model. We build reusable components to import tabular data, compute descriptive statistics, smooth and differentiate signals, perform Fourier analysis and filtering, detect peaks, integrate curves, reduce

Scientific Data Analysis with LabPlot in Python: Signal Processing, Spectral Peak Fitting, Visualization, and Batch Automation Read More »

✅

Building and Validating a Quantitative Trading Strategy with OctoBot, Walk-Forward Backtesting, Parameter Optimization, and Interactive Analysis

In this tutorial, we build a complete quantitative backtesting workflow with OctoBot and OctoBot-Script while keeping the environment isolated from Colab’s preinstalled dependencies. We configure a rule-based trading strategy that combines RSI-based oversold signals, EMA trend confirmation, and ATR-driven adaptive stop-loss and take-profit levels, and we execute it through OctoBot’s native market-order and backtesting APIs.

Building and Validating a Quantitative Trading Strategy with OctoBot, Walk-Forward Backtesting, Parameter Optimization, and Interactive Analysis Read More »

Cracking the Data Science Case Study Interview

Data science case study interviews are not just about writing code. They test how you think through a problem, analyze data, make decisions, and explain your approach in a way that solves a real business challenge. In this guide, you’ll learn a simple framework called SCOPE that you can use to approach almost any data

Cracking the Data Science Case Study Interview Read More »

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the Database Before Writing a Query

Most text-to-SQL systems treat the task as translation. Feyn AI (YC-backed startup) reframes it around inspection. The Feyn team has released SQRL, a family of models that turn natural language questions into SQL. Instead of generating a query immediately, SQRL can inspect the database first. This lets it resolve ambiguity and write only queries the

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the Database Before Writing a Query Read More »

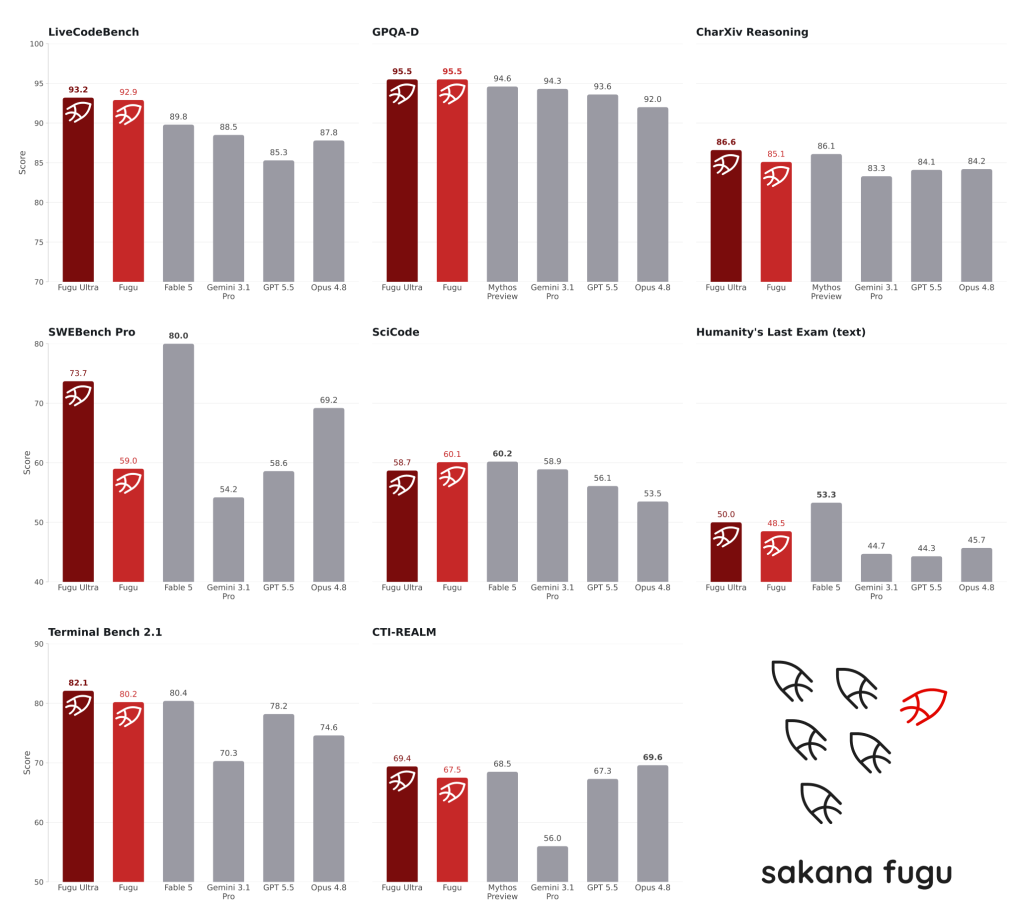
Benchmarks of Sakana AI Fugu standard and Ultra compared to rival frontier models.

Mitigating vendor lock-in with Sakana AI Fugu multi-agent models

Sakana AI launched Fugu to orchestrate multi-agent operations and mitigate single-vendor dependency risks in enterprise deployments. Enterprises face operational vulnerabilities when relying entirely on monolithic AI APIs. Japanese AI firm Sakana AI designed Fugu as a response to these concentration risks by creating an orchestration language model that calls upon a pool of varied models

Mitigating vendor lock-in with Sakana AI Fugu multi-agent models Read More »

How to Design Python-First Interactive Dashboards with Prefab Reactive UI Components and Static HTML Export

In this tutorial, we build a Prefab application that demonstrates how to create interactive dashboards entirely in Python. We use Prefab’s component-based Python interface to design a polished operations dashboard with reactive state, charts, tables, filters, forms, tabs, alerts, metrics, and client-side actions. We generate realistic pipeline monitoring data, connect it to live UI controls,

How to Design Python-First Interactive Dashboards with Prefab Reactive UI Components and Static HTML Export Read More »

✅

How to Build a Forecasting Pipeline with TimeCopilot Using Foundation Models and Automated Anomaly Detection

In this tutorial, we build an end-to-end forecasting workflow with TimeCopilot. We prepare a panel dataset containing real airline passenger data and a synthetic seasonal series with injected anomalies, then evaluate a diverse collection of statistical, foundation, and optional GPU-based forecasting models. We use rolling cross-validation and multiple error metrics to identify the strongest model,

How to Build a Forecasting Pipeline with TimeCopilot Using Foundation Models and Automated Anomaly Detection Read More »

A Coding Hands-On on FineWeb for Streaming, Filtering, Deduplication, Tokenization, and Large-Scale Web Corpus Analytics

In this tutorial, we explore the FineWeb dataset through an advanced hands-on workflow. We stream a manageable sample of the dataset without downloading the full multi-terabyte corpus, inspect its schema and metadata, and analyze key fields such as URL, language, language score, and token count. We also reproduce simplified versions of FineWeb’s quality-filtering pipeline, apply

A Coding Hands-On on FineWeb for Streaming, Filtering, Deduplication, Tokenization, and Large-Scale Web Corpus Analytics Read More »

✅

Building a Code Dataset Pipeline from NVIDIA Nemotron-Pretraining-Code-v3 Metadata with Streaming, Pandas, and tiktoken

In this tutorial, we work with NVIDIA’s Nemotron-Pretraining-Code-v3 dataset as a large-scale metadata index for code pretraining research. Instead of downloading the full multi-gigabyte dataset, we stream it, inspect its schema, and build a manageable sample for analysis. We then explore the dataset by studying languages, file extensions, repository frequency, and directory depth, which helps

Building a Code Dataset Pipeline from NVIDIA Nemotron-Pretraining-Code-v3 Metadata with Streaming, Pandas, and tiktoken Read More »