Large Language Model

Auto Added by WPeMatico

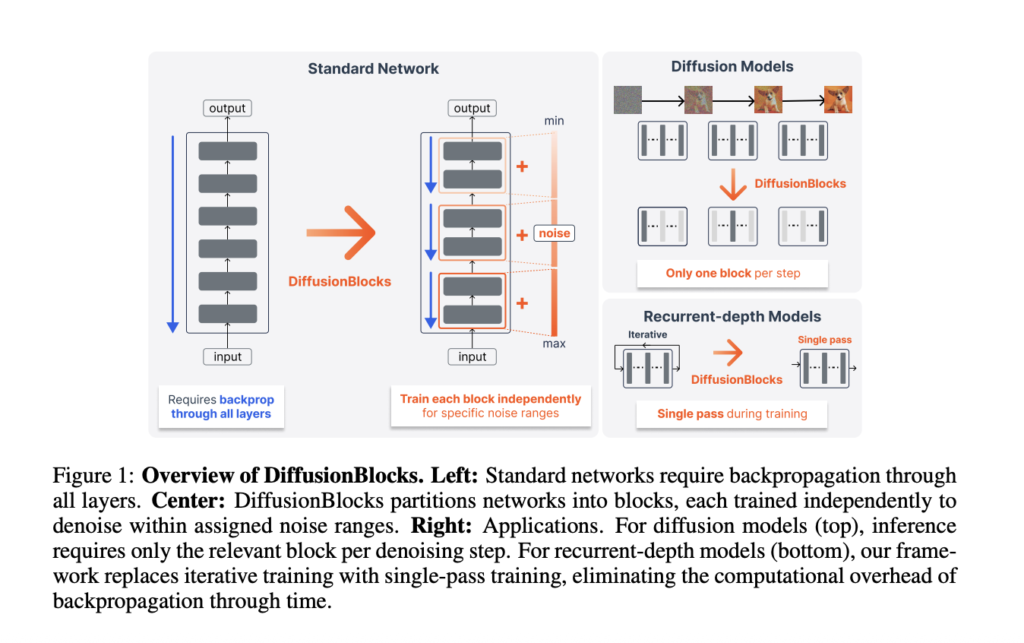
Sakana AI Proposes DiffusionBlocks: a Block-wise Training Framework That Converts Residual Networks into Independently Trainable Denoising Modules

Researchers from Sakana AI and the University of Tokyo propose DiffusionBlocks. It trains transformer-based networks one block at a time. Training memory is reduced by a factor of B, where B is the number of blocks. Performance is maintained across diverse architectures. The Memory Problem in Neural Network Training End-to-end backpropagation requires storing intermediate activations […]
Sakana AI Proposes DiffusionBlocks: a Block-wise Training Framework That Converts Residual Networks into Independently Trainable Denoising Modules Read More »

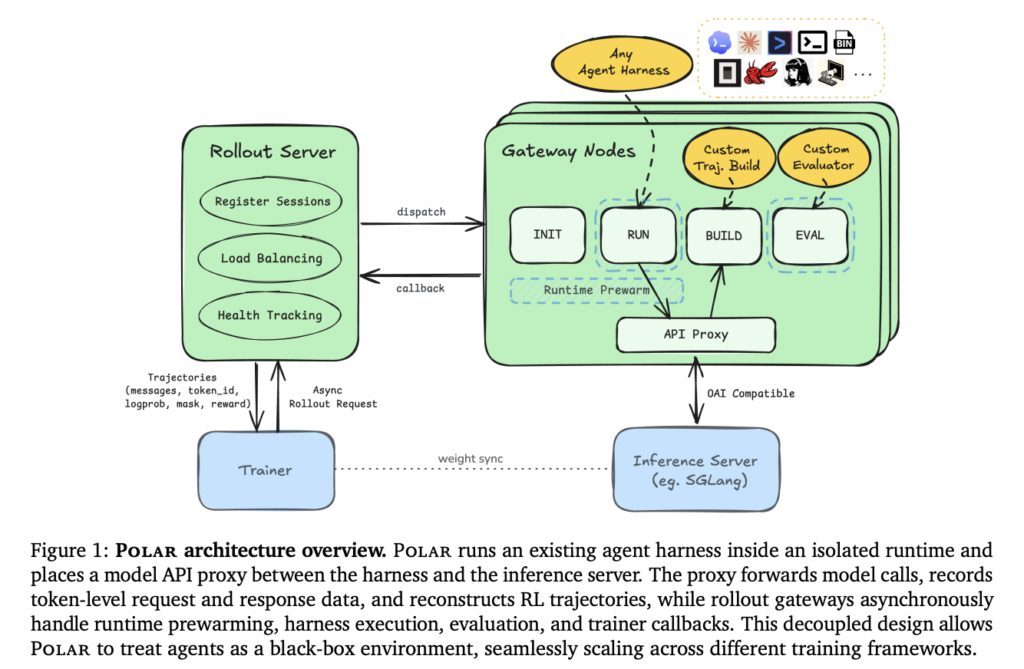
NVIDIA Releases Polar, a Token-Faithful Rollout Framework for GRPO Training Across Codex, Claude Code, and Qwen Code

Reinforcement learning for language agents is growing more complex. Agents now manage multi-turn tool use, long-running contexts, and multi-agent orchestration. The main engineering challenge is connecting existing agent software to training pipelines without breaking how those tools work. NVIDIA’s research team introduced Polar, a rollout framework that lets researchers run reinforcement learning over any agent

NVIDIA Releases Polar, a Token-Faithful Rollout Framework for GRPO Training Across Codex, Claude Code, and Qwen Code Read More »

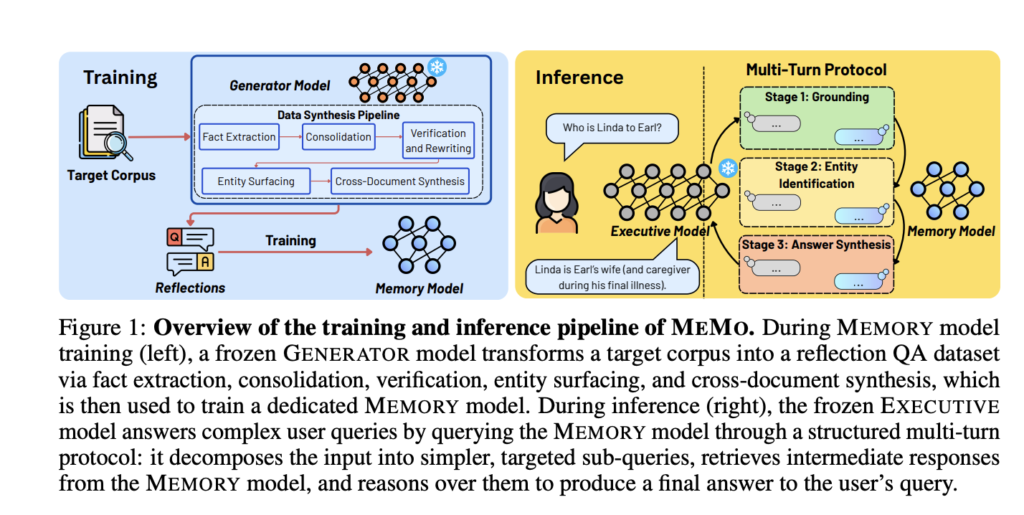
MEMO: A Modular Framework for Training a Dedicated Memory Model on New Knowledge Without Modifying LLM Parameters

Large language models become static after pretraining. Their knowledge does not update as the world changes. Retraining a full LLM is too expensive at modern scales. Fine-tuning risks degrading previously learned knowledge. Retrieval-augmented generation (RAG) struggles when answers require reasoning across many documents. A team of researchers from the National University of Singapore, MIT CSAIL,

MEMO: A Modular Framework for Training a Dedicated Memory Model on New Knowledge Without Modifying LLM Parameters Read More »

✅

Build a Complete Langfuse Observability and Evaluation Pipeline for Tracing, Prompt Management, Scoring, and Experiments

In this tutorial, we implement the Langfuse (an open-source LLM engineering platform) pipeline for tracing, prompt management, scoring, datasets, and experiments. We build a complete workflow that works with either a real OpenAI key or a deterministic mock LLM, so we can understand every major Langfuse feature without depending on paid model access. We start

Build a Complete Langfuse Observability and Evaluation Pipeline for Tracing, Prompt Management, Scoring, and Experiments Read More »

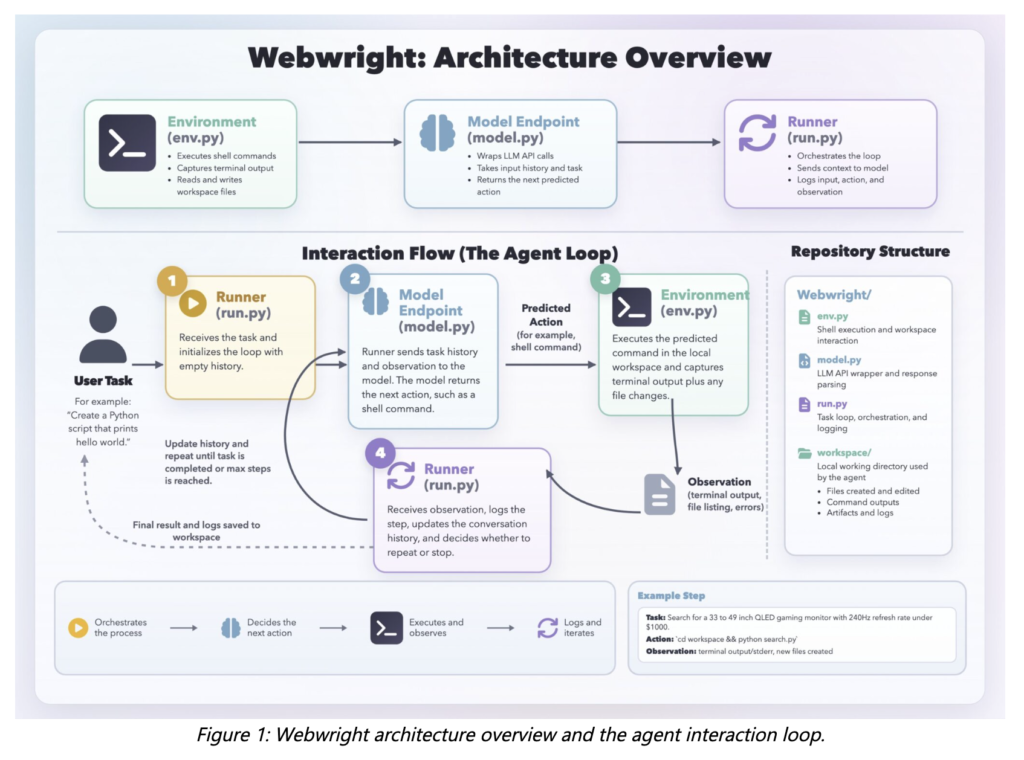
Microsoft Research Releases Webwright: A Terminal-Native Web Agent Framework That Scores 60.1% on Odysseys, Up from Base GPT-5.4’s 33.5%

Most web agents today drive a browser one action at a time. The model receives the current page state — as a screenshot or DOM text — and predicts the next click, keypress, or scroll. This action-at-a-time design made sense when language models had limited reasoning ability. As models have become more capable at writing

Microsoft Research Releases Webwright: A Terminal-Native Web Agent Framework That Scores 60.1% on Odysseys, Up from Base GPT-5.4’s 33.5% Read More »

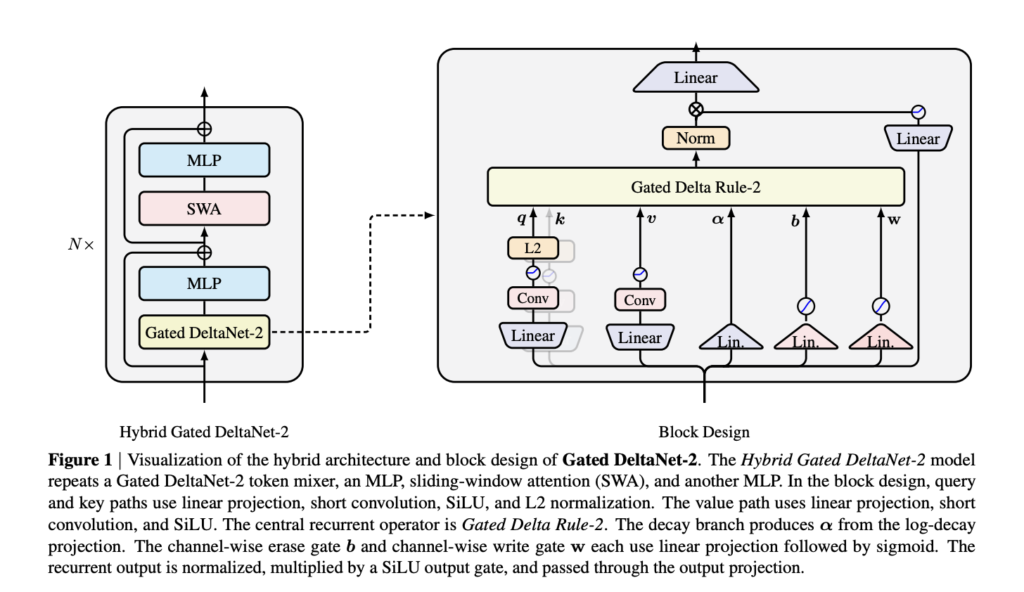
NVIDIA AI Releases Gated DeltaNet-2: A Linear Attention Layer That Decouples Erase and Write in the Delta Rule

Linear attention replaces the unbounded KV cache of softmax attention with a fixed-size recurrent state. This cuts sequence mixing to linear time and decoding to constant memory. The hard part is not what to forget. It is how to edit a compressed memory without scrambling existing associations. NVIDIA has released Gated DeltaNet-2, a linear attention

NVIDIA AI Releases Gated DeltaNet-2: A Linear Attention Layer That Decouples Erase and Write in the Delta Rule Read More »

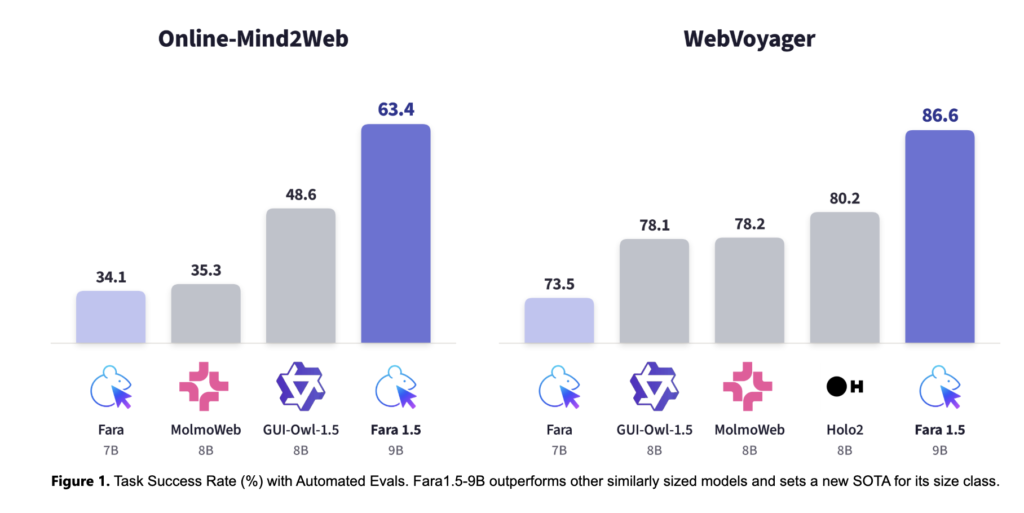
Microsoft Releases Fara1.5: A Family of Browser Computer-Use Agents (4B/9B/27B) That Outperform OpenAI Operator and Gemini 2.5 Computer Use on Online-Mind2Web

Microsoft Research’s AI Frontiers lab released Fara1.5. It is a family of computer-use agent (CUA) models for the browser. The release ships three sizes: Fara1.5-4B, Fara1.5-9B, and Fara1.5-27B. The models are integrated with MagenticLite, Microsoft’s sandboxed browser interface for these agents. Computer-use agents are pixel-to-action models that drive a real browser. They read screenshots and

Microsoft Releases Fara1.5: A Family of Browser Computer-Use Agents (4B/9B/27B) That Outperform OpenAI Operator and Gemini 2.5 Computer Use on Online-Mind2Web Read More »

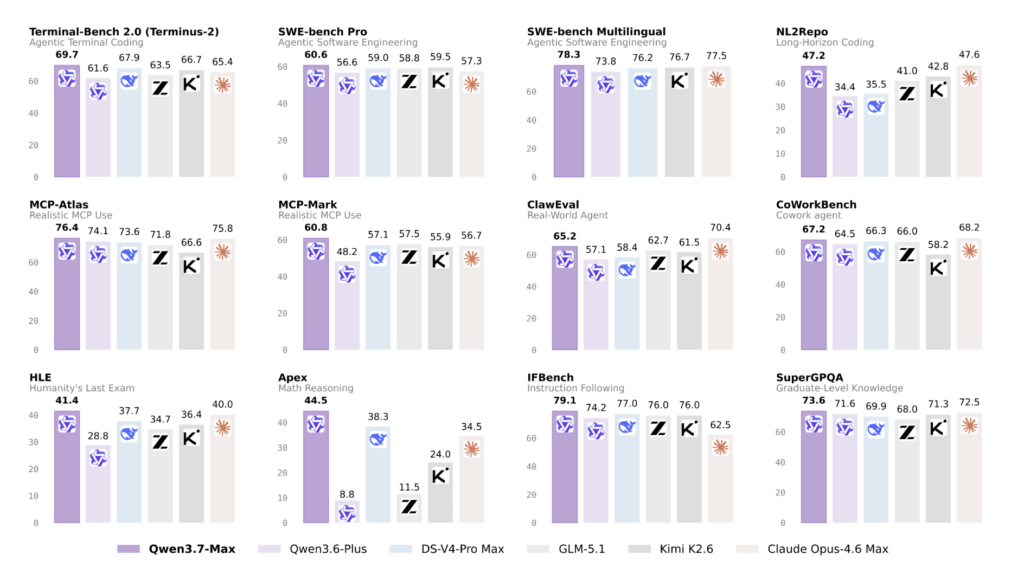
Qwen Introduces Qwen3.7-Max: A Reasoning Agent Model With a 1M-Token Context Window

Most AI models today are not designed for sustained, multi-step autonomous execution. Tasks like running hundreds of iterative code modifications, or chaining tool calls across hours without human intervention, require a different kind of model architecture and training focus. Alibaba’s Qwen team formally announced Qwen3.7-Max at the 2026 Alibaba Cloud Summit on May 20. Although,

Qwen Introduces Qwen3.7-Max: A Reasoning Agent Model With a 1M-Token Context Window Read More »

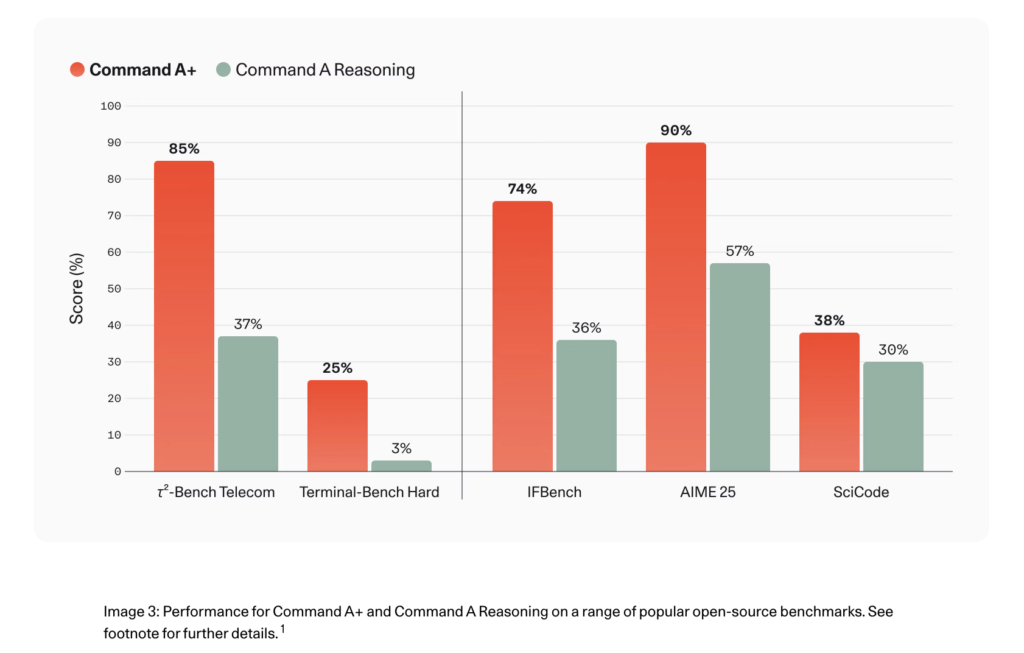
Cohere Releases Command A+: A 218B Sparse MoE Model for Agentic Workflows That Runs on as Few as Two H100 GPUs

Cohere just released Command A+, as an open-source model targeting enterprise agentic workflows. Available under an Apache 2.0 license, Command A+ is a mixture-of-experts (MoE) model built for high-performance agentic tasks with minimal compute overhead. The model is optimized for reasoning, agentic workflows, RAG, multilingual, and multimodal document processing. It unifies capabilities from four prior

Cohere Releases Command A+: A 218B Sparse MoE Model for Agentic Workflows That Runs on as Few as Two H100 GPUs Read More »

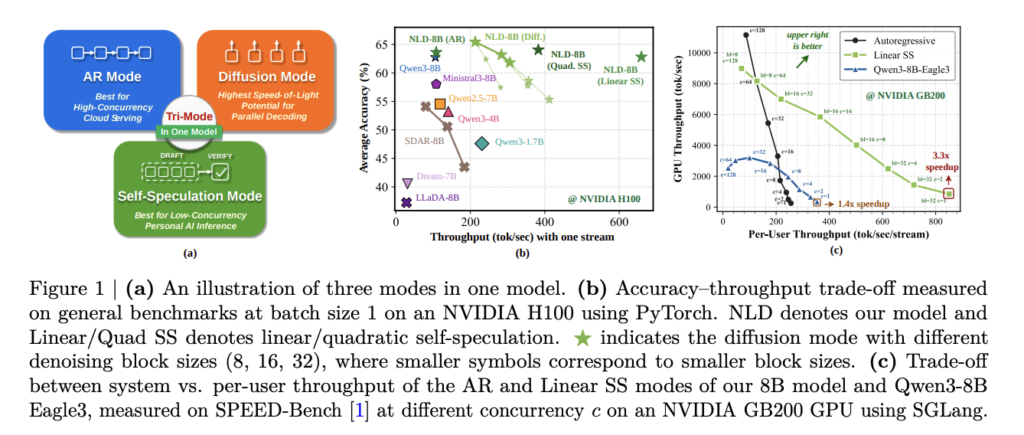
NVIDIA AI Releases Nemotron-Labs-Diffusion: A Tri-Mode Language Model with 6× Tokens Per Forward Over Qwen3-8B

NVIDIA researchers have released Nemotron-Labs-Diffusion, a language model family that unifies three decoding modes in one architecture. The model supports autoregressive (AR) decoding, diffusion-based parallel decoding, and self-speculation decoding. It is available in 3B, 8B, and 14B parameter sizes. The family includes base, instruct, and vision-language variants. Sequential Decoding Limits Throughput Standard autoregressive (AR) language

NVIDIA AI Releases Nemotron-Labs-Diffusion: A Tri-Mode Language Model with 6× Tokens Per Forward Over Qwen3-8B Read More »