Large Language Model

Auto Added by WPeMatico

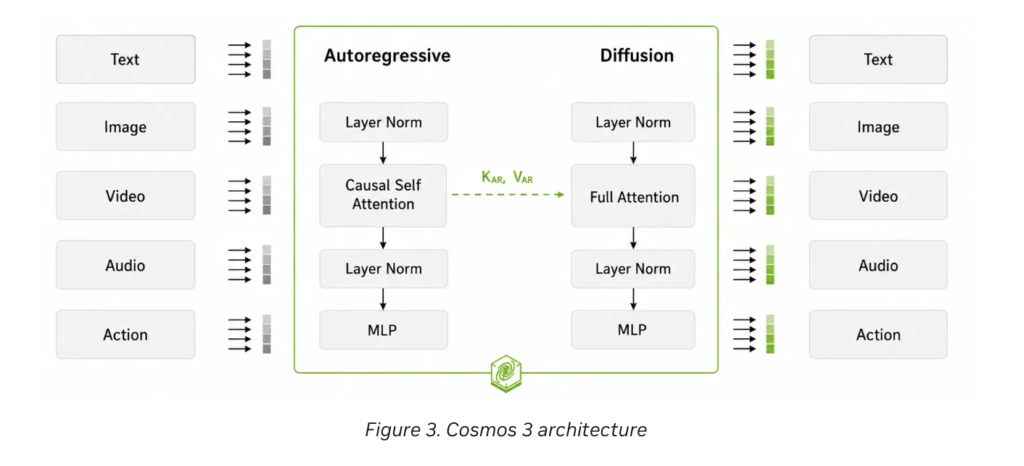
NVIDIA Releases Cosmos 3: A Two-Tower Mixture-of-Transformers Foundation Model Unifying Physical Reasoning, World Generation, and Action Generation

NVIDIA AI team have released Cosmos 3. It is a family of omnimodal world models for physical AI. The models combine physical reasoning, world generation, and action generation. All three capabilities live inside one open model. NVIDIA open sourced the checkpoints, training scripts, deployment tools, and datasets. The Cosmos 3 release targets robotics, autonomous vehicles, […]
NVIDIA Releases Cosmos 3: A Two-Tower Mixture-of-Transformers Foundation Model Unifying Physical Reasoning, World Generation, and Action Generation Read More »

How to Fine-Tune LFM2 Using QLoRA and DPO: A Complete Step-by-Step Coding Tutorial on Google Colab

In this tutorial, we fine-tune Liquid AI’s LFM2 model through a complete open-source workflow. We start by loading the base LFM2 checkpoint with QLoRA, preparing a chat-style supervised fine-tuning dataset, training a lightweight LoRA adapter using TRL and PEFT, and then merging the adapter back into the model. We also extend the workflow with DPO

How to Fine-Tune LFM2 Using QLoRA and DPO: A Complete Step-by-Step Coding Tutorial on Google Colab Read More »

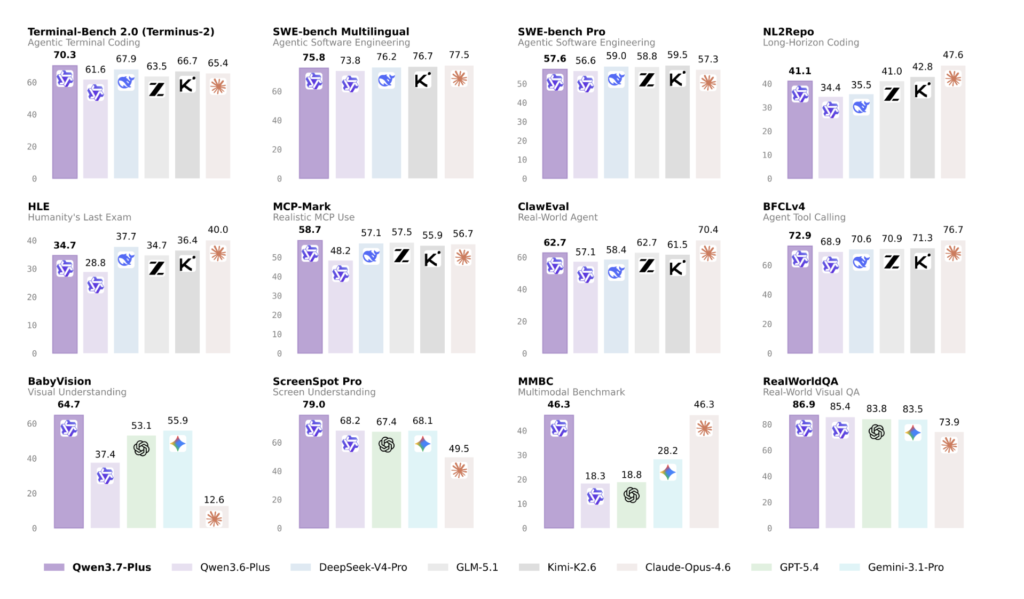
Alibaba’s Qwen Team Launches Qwen3.7-Plus, Adding Vision, Deep Reasoning, Tool Invocation, and Autonomous Iteration on the Bailian Platform

Alibaba’s Qwen team has released Qwen3.7-Plus. The model is now available through Alibaba Cloud’s Bailian platform. Bailian is the console international users access as Model Studio. It offers API services to external developers. The release follows Alibaba’s May unveiling of the Qwen3.7 generation. Qwen3.7-Plus Qwen3.7-Plus is a multimodal large language model. The model understands images

Alibaba’s Qwen Team Launches Qwen3.7-Plus, Adding Vision, Deep Reasoning, Tool Invocation, and Autonomous Iteration on the Bailian Platform Read More »

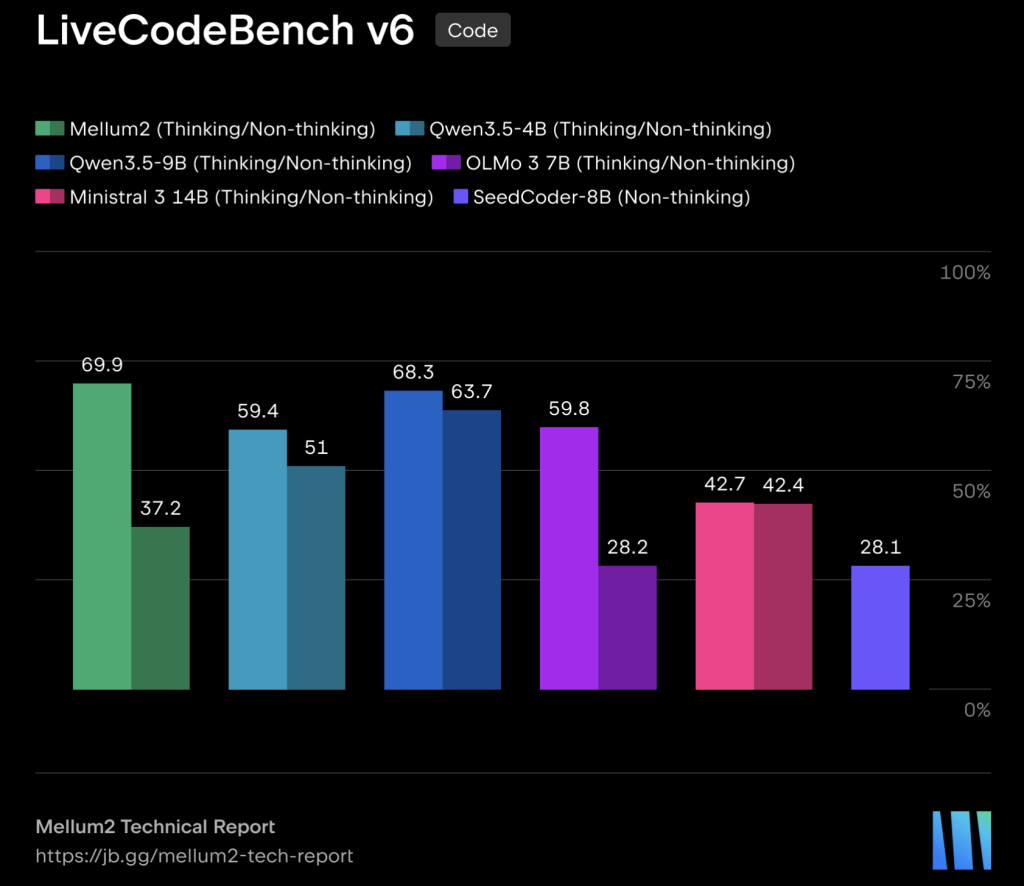
JetBrains Releases Mellum2: A 12B MoE Model for Fast, Specialized Tasks in Multi-Model AI Pipelines

JetBrains released Mellum2, open-sourcing the weights under the Apache 2.0 license. The first version of Mellum was a completion-focused 4B dense model. Mellum2 is its successor: a general-purpose model specialized in software engineering. It covers code generation and editing, debugging, multi-step reasoning, tool use and function calling, agentic coding, and conversational programming assistance. JetBrains team

JetBrains Releases Mellum2: A 12B MoE Model for Fast, Specialized Tasks in Multi-Model AI Pipelines Read More »

MiniMax Releases MiniMax M3 with MSA Architecture Supporting 1M-Token Context, Native Multimodality, and Agentic Coding

MiniMax officially released MiniMax M3 on June 1, 2026. The model introduces MSA (MiniMax Sparse Attention), a new sparse attention architecture that gives M3 a 1M-token context window. M3 also supports image and video input and desktop computer operation natively. The API is live now. MiniMax M3 is available today via MiniMax Code, the MiniMax

MiniMax Releases MiniMax M3 with MSA Architecture Supporting 1M-Token Context, Native Multimodality, and Agentic Coding Read More »

Trajectory Releases a Concurrent Multi-LoRA Training Stack for Continual Learning, Reporting a 2.81× Experiment-Throughput Gain

Trajectory’s concurrent multi-LoRA stack reports a 2.81× experiment-throughput gain over single-tenant RL, with all code in the NovaSky-AI/SkyRL GitHub repository. Most language models improve in discontinuous jumps. A team collects data, trains, and ships a new version. This takes months and produces remarkable or catastrophic behavior for users. Trajectory wants to replace that cycle with

Trajectory Releases a Concurrent Multi-LoRA Training Stack for Continual Learning, Reporting a 2.81× Experiment-Throughput Gain Read More »

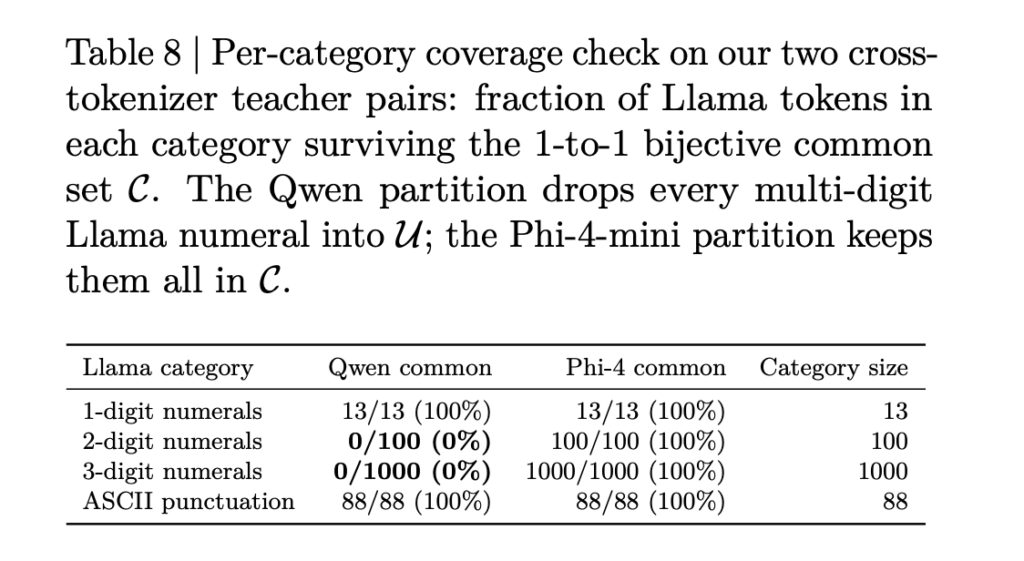
NVIDIA Introduces X-Token: Projection-Guided Cross-Tokenizer KD That Outperforms GOLD by +3.82 Average Points on Llama-3.2-1B

Knowledge distillation (KD) transfers “dark knowledge” from a large teacher model to a smaller student. The student learns from the teacher’s full output probability distribution over tokens, not just correct answers. This is done via per-position Kullback–Leibler (KL) divergence over next-token probability distributions. This formulation requires a shared tokenizer. A practitioner committed to Llama-3.2-1B cannot

NVIDIA Introduces X-Token: Projection-Guided Cross-Tokenizer KD That Outperforms GOLD by +3.82 Average Points on Llama-3.2-1B Read More »

StepFun Releases Step 3.7 Flash: A 198B MoE Vision-Language Model for Coding Agents and Search Workflows

StepFun today released Step 3.7 Flash, a multimodal Mixture-of-Experts model targeting agentic use cases. It adds native vision input and improved tool-use reliability over Step 3.5 Flash. What is Step 3.7 Flash? Step 3.7 Flash is a 198B-parameter sparse Mixture-of-Experts (MoE) vision-language model. It pairs a 196B-parameter language backbone with a 1.8B-parameter vision encoder (ViT)

StepFun Releases Step 3.7 Flash: A 198B MoE Vision-Language Model for Coding Agents and Search Workflows Read More »

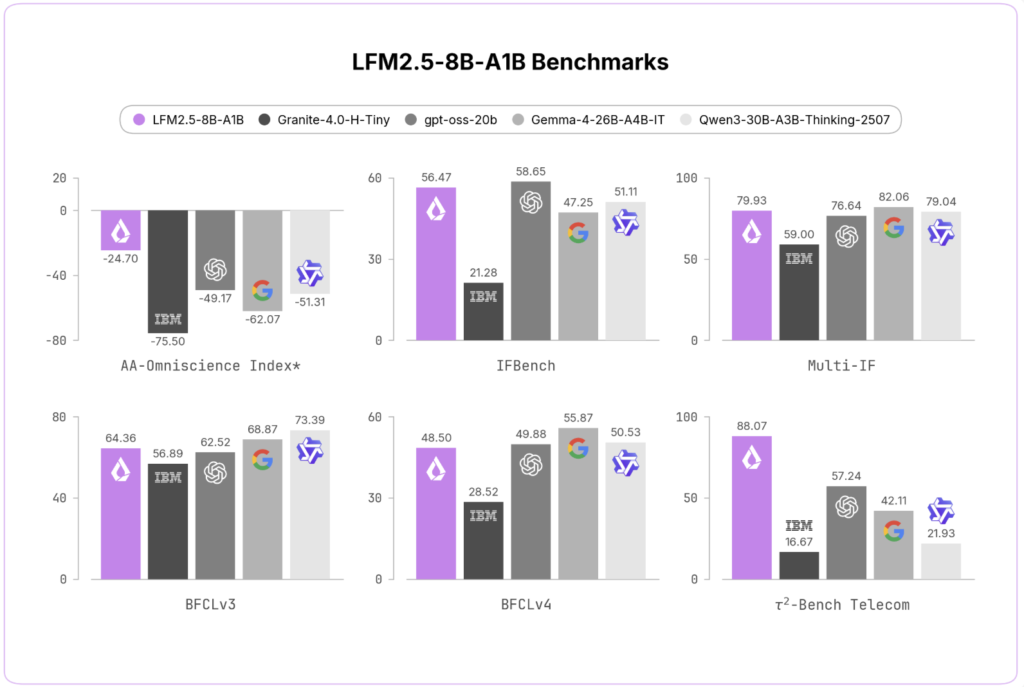
Liquid AI Releases LFM2.5-8B-A1B: An On-Device MoE Model With 8.3B Total and 1.5B Active Parameters

Liquid AI just shipped LFM2.5-8B-A1B. It is an on-device Mixture-of-Experts (MoE) model built for tool calling. The model holds 8.3B total parameters but activates only 1.5B per token. That sparsity is what lets it run on consumer hardware. The release follows LFM2-8B-A1B, which Liquid AI team published earlier. LFM2.5 is a new family of hybrid

Liquid AI Releases LFM2.5-8B-A1B: An On-Device MoE Model With 8.3B Total and 1.5B Active Parameters Read More »

Anthropic Ships Claude Opus 4.8 Alongside Dynamic Workflows and Cheaper Fast Mode, With Workflows Capped at 1,000 Subagents

Anthropic just launched Claude Opus 4.8. Also, there two Claude Code updates shipped with it. Dynamic workflows run many subagents in parallel. Fast mode now supports Opus 4.8 at a lower price. Both are research previews. What Dynamic Workflows Actually Are A dynamic workflow is a JavaScript script that orchestrates subagents at scale. Claude writes

Anthropic Ships Claude Opus 4.8 Alongside Dynamic Workflows and Cheaper Fast Mode, With Workflows Capped at 1,000 Subagents Read More »