Large Language Model

Auto Added by WPeMatico

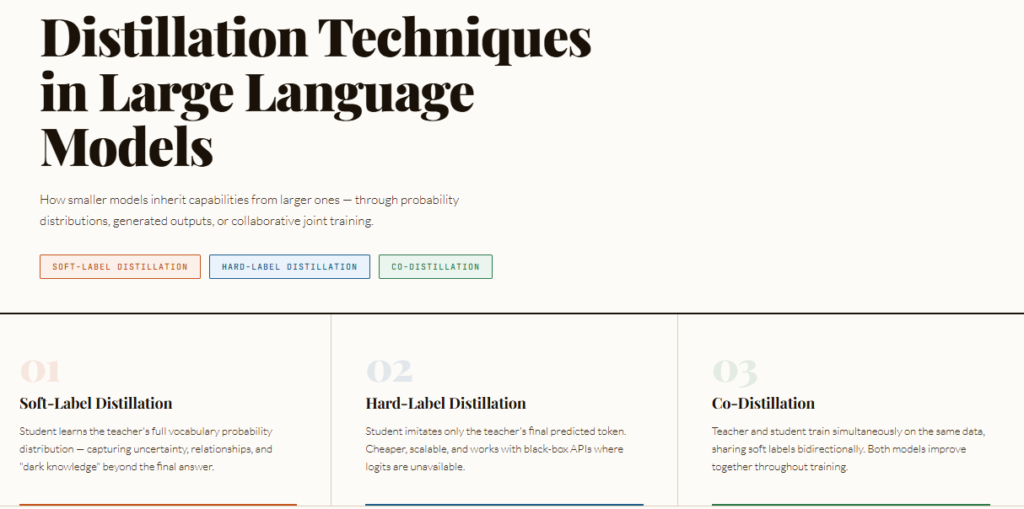
Understanding LLM Distillation Techniques 

Modern large language models are no longer trained only on raw internet text. Increasingly, companies are using powerful “teacher” models to help train smaller or more efficient “student” models. This process, broadly known as LLM distillation or model-to-model training, has become a key technique for building high-performing models at lower computational cost. Meta used its […]
Understanding LLM Distillation Techniques  Read More »

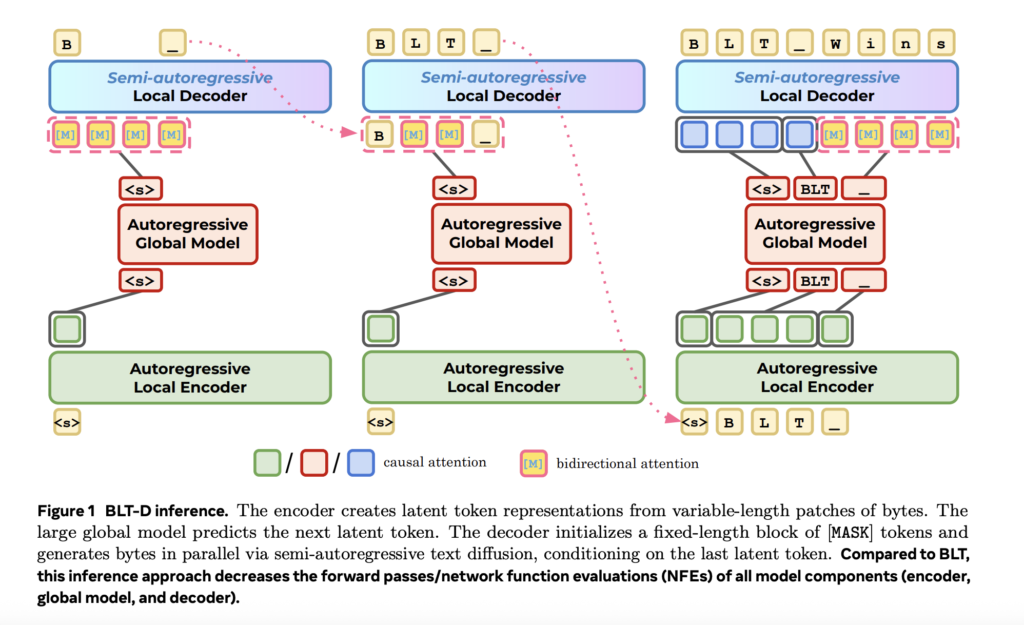
Meta and Stanford Researchers Propose Fast Byte Latent Transformer That Reduces Inference Memory Bandwidth by Over 50% Without Tokenization

A team of researchers from Meta, Stanford University, and the University of Washington have introduced three new methods that substantially accelerate generation in the Byte Latent Transformer (BLT) — a language model architecture that operates directly on raw bytes instead of tokens. Byte-Level Models Are Slow at Inference To understand what this new research solves,

Meta and Stanford Researchers Propose Fast Byte Latent Transformer That Reduces Inference Memory Bandwidth by Over 50% Without Tokenization Read More »

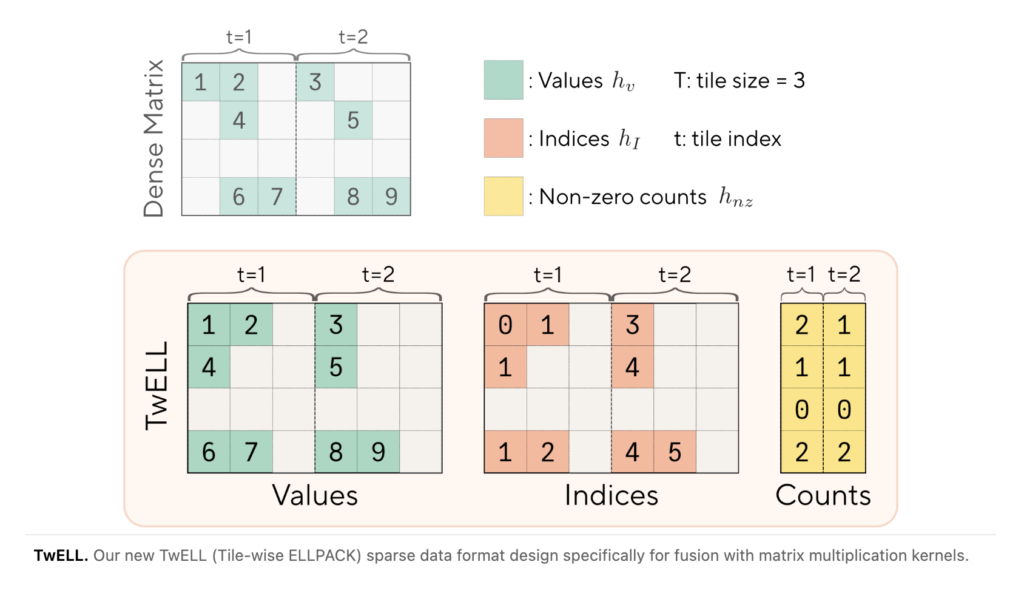
Sakana AI and NVIDIA Introduce TwELL with CUDA Kernels for 20.5% Inference and 21.9% Training Speedup in LLMs

Scaling large language models (LLMs) is expensive. Every token processed during inference and every gradient computed during training flows through feedforward layers that account for over two-thirds of model parameters and more than 80% of total FLOPs in larger models. A team researchers from Sakana AI and NVIDIA have worked on a new research that

Sakana AI and NVIDIA Introduce TwELL with CUDA Kernels for 20.5% Inference and 21.9% Training Speedup in LLMs Read More »

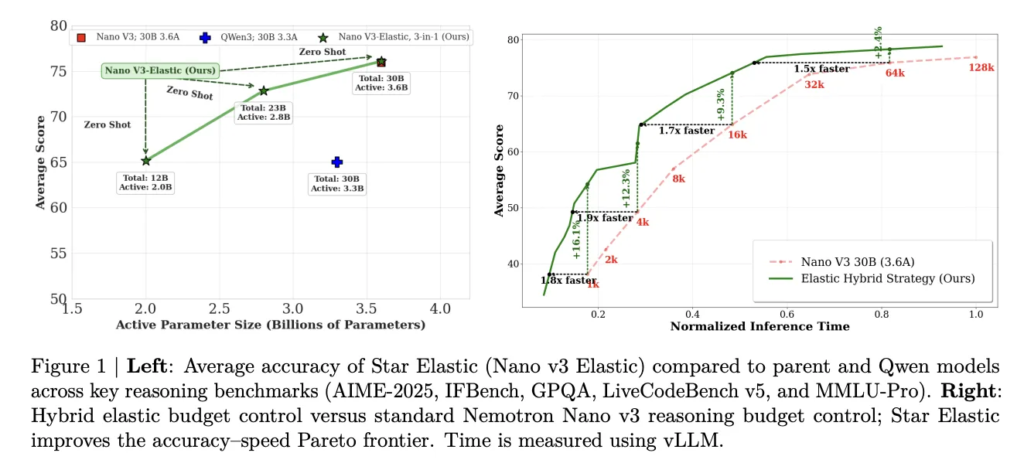
NVIDIA AI Releases Star Elastic: One Checkpoint that Contains 30B, 23B, and 12B Reasoning Models with Zero-Shot Slicing

Training a family of large language models (LLMs) has always come with a painful multiplier: every model variant in the family—whether 8B, 30B, or 70B—typically requires its own full training run, its own storage, and its own deployment stack. For a dev team running inference at scale, this means multiplying compute costs by the number

NVIDIA AI Releases Star Elastic: One Checkpoint that Contains 30B, 23B, and 12B Reasoning Models with Zero-Shot Slicing Read More »

How to Build Traceable and Evaluated LLM Workflows Using Promptflow, Prompty, and OpenAI

In this tutorial, we build a complete, production-style LLM workflow using Promptflow within a Colab environment. We begin by setting up a reliable keyring backend to avoid OS dependency issues and securely configure our OpenAI connection. From there, we establish a clean workspace and define a structured Prompty file that acts as the core LLM

How to Build Traceable and Evaluated LLM Workflows Using Promptflow, Prompty, and OpenAI Read More »

Introducing Translator Copilot: Bridging Customers and Translators with AI  

Translator Copilot is Unbabel’s new AI assistant built directly into our CAT tool. It leverages large language models (LLMs) and Unbabel’s proprietary Quality Estimation (QE) technology to act as a smart second pair of eyes for every translation. From checking whether customer instructions are followed to flagging potential errors in real time, Translator Copilot strengthens

Introducing Translator Copilot: Bridging Customers and Translators with AI   Read More »

TowerLLM, Unbabel’s GenAI for translation, ushers in the next era of machine translation  

Machine translation (MT) has come a long way. From the early rule-based systems to the advent of neural networks, the field has seen remarkable advancements. For more than a decade, Unbabel has been at the forefront of this evolution, leveraging state-of-the-art technologies like quality estimation (QE) to enhance translation accuracy and fluency.  However, despite all

TowerLLM, Unbabel’s GenAI for translation, ushers in the next era of machine translation   Read More »

Announcing Tower: An Open Multilingual LLM for Translation-Related Tasks

Updated February 9, 2024 to include the newest iteration of Tower models. We are thrilled to announce the release of Tower, a suite of multilingual large language models (LLM) optimized for translation-related tasks. Tower is built on top of LLaMA2 [1], comes in two sizes — 7B and 13B parameters —, and currently supports 10

Announcing Tower: An Open Multilingual LLM for Translation-Related Tasks Read More »

Meet Talkie-1930: A 13B Open-Weight LLM Trained on Pre-1931 English Text for Historical Reasoning and Generalization Research

What if a language model had never heard of the internet, smartphones, or even World War II? That’s not a hypothetical — it’s exactly what a team of researchers led by Nick Levine, David Duvenaud, and Alec Radford has built. They call it talkie, and it may be the most historically disciplined large language model

Meet Talkie-1930: A 13B Open-Weight LLM Trained on Pre-1931 English Text for Historical Reasoning and Generalization Research Read More »