Large Language Model

Auto Added by WPeMatico

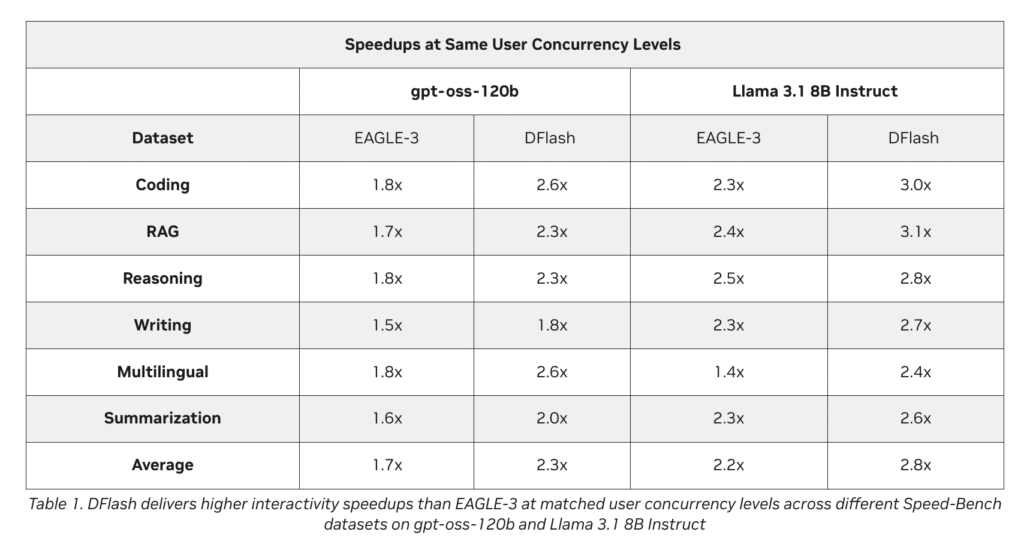
DFlash Speculative Decoding Drafts Whole Token Blocks in Parallel for Up to 15x Higher Throughput on NVIDIA Blackwell

Autoregressive large language models generate text one token at a time. Each token waits for the one before it. This serial loop leaves modern GPUs underused and keeps inference slow. The cost grows worse with long Chain-of-Thought reasoning models. Their lengthy outputs make latency the dominant part of generation. Speculative decoding is the standard fix. […]
DFlash Speculative Decoding Drafts Whole Token Blocks in Parallel for Up to 15x Higher Throughput on NVIDIA Blackwell Read More »

Mistral OCR 4 Brings Citation-Ready Structured Output to RAG, Agentic, and Enterprise Search Pipelines

Today, Mistral AI released OCR 4, its latest document-understanding model. This new release adds bounding boxes, block classification, and inline confidence scores alongside extracted text. It supports 170 languages across 10 language groups and runs in a single container for fully self-hosted deployments. OCR 4 also serves as an ingestion component for enterprise search, RAG,

Mistral OCR 4 Brings Citation-Ready Structured Output to RAG, Agentic, and Enterprise Search Pipelines Read More »

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured JSON From PDFs Using Schemas

Datalab has released lift, a 9B open-weights vision model for structured extraction. You pass it a JSON schema, and it returns a JSON object that matches. The model reads PDFs and images directly, then decodes against your schema. This is Datalab’s first model built purely for extraction. The team already ships open-source OCR tools: chandra,

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured JSON From PDFs Using Schemas Read More »

GLM-5.2 OpenAI-Compatible API: A Hands-On Guide to Reasoning Effort, Function Calling, and Long-Context Retrieval

In this tutorial, we work with GLM-5.2 and use its hosted, OpenAI-compatible API instead of running the full model locally. We begin by setting up multiple provider options, securely loading the API key, and creating a reusable chat wrapper that supports normal chat, thinking mode, streaming, tool calling, and token tracking. Then we move beyond

GLM-5.2 OpenAI-Compatible API: A Hands-On Guide to Reasoning Effort, Function Calling, and Long-Context Retrieval Read More »

Sakana AI Launches Sakana Fugu: An Orchestration Model That Routes Tasks Across a Swappable Pool of Frontier LLMs

Today, Sakana AI launched Sakana Fugu. It is a multi-agent orchestration system that behaves like one model. You send a request to a single endpoint. Fugu decides how to handle it internally. It solves a task directly when that is enough. It also assembles and coordinates a team of expert models when needed. The complexity

Sakana AI Launches Sakana Fugu: An Orchestration Model That Routes Tasks Across a Swappable Pool of Frontier LLMs Read More »

NVIDIA AI Introduce SpatialClaw: A Training-Free Agent That Treats Code as the Action Interface for Spatial Reasoning

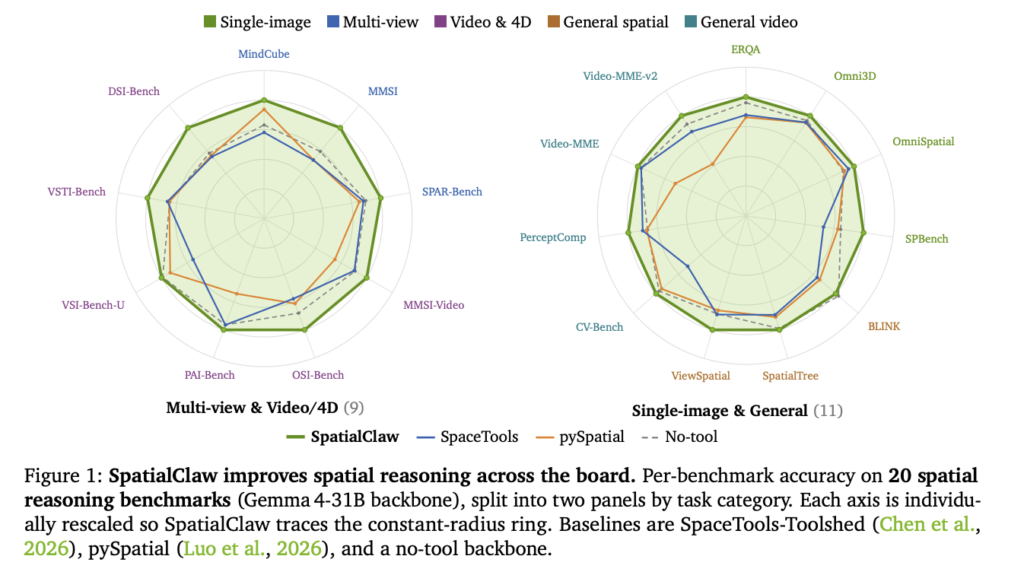
NVIDIA Research has released SpatialClaw, a training-free framework for spatial reasoning. It targets a persistent weakness in vision-language models (VLMs). These models still struggle to judge where objects are, how they relate, and how they move in 3D. SpatialClaw does not retrain the model. Instead, it changes the action interface the agent uses to call

NVIDIA AI Introduce SpatialClaw: A Training-Free Agent That Treats Code as the Action Interface for Spatial Reasoning Read More »

VibeThinker-3B: A 3B Dense Reasoning Model Built on Qwen2.5-Coder-3B With the Spectrum-to-Signal Post-Training Pipeline

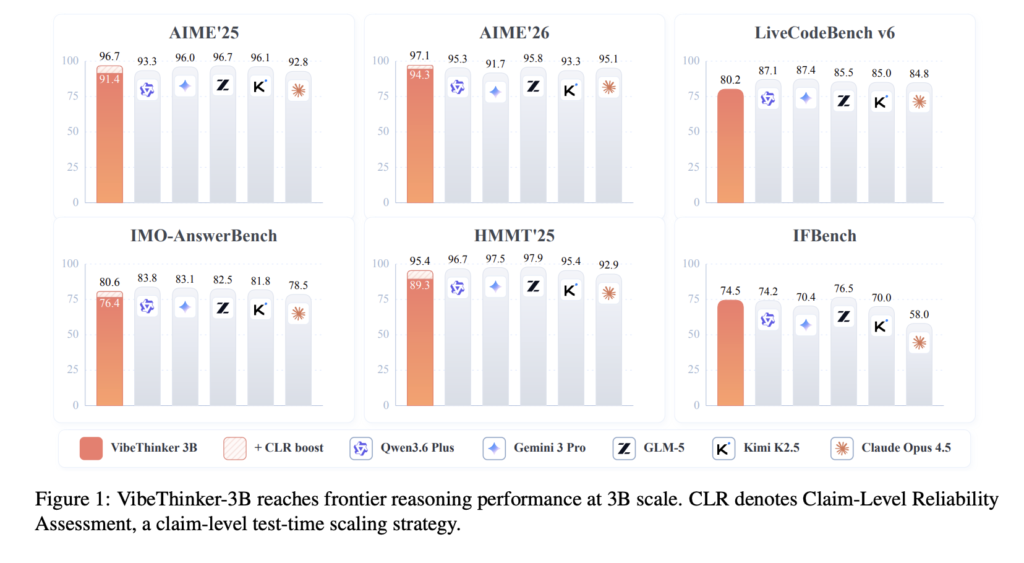
While recent breakthroughs in AI reasoning have largely been driven by massive scale, pouring in billions of parameters to cross complex cognitive thresholds—VibeThinker-3B is charting a completely different path. Created by researchers from Sina Weibo Inc (China), this 3-billion-parameter model proves that efficiency can punch far above its weight class. Released under an open-source MIT

VibeThinker-3B: A 3B Dense Reasoning Model Built on Qwen2.5-Coder-3B With the Spectrum-to-Signal Post-Training Pipeline Read More »

Liquid AI Introduces LFM2.5-Embedding-350M and LFM2.5-ColBERT-350M: Dense Bi-Encoder and Late-Interaction Models for Fast Multilingual Search Across 11 Languages

This week, Liquid AI released two new retrieval models. They are LFM2.5-ColBERT-350M and LFM2.5-Embedding-350M. Both hold 350M parameters. Both are the first bidirectional members of the LFM family. They build on LFM2.5-350M-Base, released in March. The pair targets fast multilingual and cross-lingual search across 11 languages. Their footprint is small enough to run almost anywhere.

Liquid AI Introduces LFM2.5-Embedding-350M and LFM2.5-ColBERT-350M: Dense Bi-Encoder and Late-Interaction Models for Fast Multilingual Search Across 11 Languages Read More »

Salesforce CodeGen Tutorial: Generate, Validate, and Rerank Python Functions With Unit Tests and Safety Checks

In this tutorial, we implement an end-to-end workflow for Salesforce CodeGen. We load a CodeGen model from Hugging Face, prepare it for code generation, and use it to generate Python functions from natural-language prompts. We then move beyond basic inference by adding function extraction, syntax checking, static safety checks, unit-test-based validation, best-of-N candidate reranking, multi-step

Salesforce CodeGen Tutorial: Generate, Validate, and Rerank Python Functions With Unit Tests and Safety Checks Read More »

OpenAI Releases LifeSciBench, a 750-Task Benchmark Grading AI Models on Real Life-Science Research With Expert-Written Rubric

Most biology benchmarks ask narrow, fact-based questions with clean answers. Scientists weigh imperfect evidence and make decisions. OpenAI released LifeSciBench and it targets that gap directly. Even the strongest model passes roughly one task in three. The benchmark is far from saturated. What is LifeSciBench LifeSciBench contains 750 expert-authored tasks. They span seven workflows and

OpenAI Releases LifeSciBench, a 750-Task Benchmark Grading AI Models on Real Life-Science Research With Expert-Written Rubric Read More »