Large Language Model

Auto Added by WPeMatico

NVIDIA Releases Nemotron-Labs-TwoTower: an Open-Weight Diffusion Language Model Built on a Frozen Autoregressive Nemotron-3-Nano-30B-A3B Backbone

NVIDIA has released Nemotron-Labs-TwoTower, a diffusion language model built on a pretrained autoregressive backbone. It ships as open weights under the NVIDIA Nemotron Open Model License. The release targets a throughput bottleneck in text generation. Autoregressive (AR) models decode one token at a time. That serial process caps generation throughput. Discrete diffusion language models take […]
NVIDIA Releases Nemotron-Labs-TwoTower: an Open-Weight Diffusion Language Model Built on a Frozen Autoregressive Nemotron-3-Nano-30B-A3B Backbone Read More »

Anthropic Claude Sonnet 5 vs Sonnet 4.6 vs Opus 4.8: Agentic Coding Benchmarks, API Pricing, and Cost-Performance Tradeoffs Compared

Anthropic just shipped Claude Sonnet 5. They call it its most agentic Sonnet model yet. It plans, drives browsers and terminals, and runs autonomously across long tasks. Sonnet 5 is the default model for Free and Pro plans today. Max, Team, and Enterprise users can select it. It is also live in Claude Code and

Anthropic Claude Sonnet 5 vs Sonnet 4.6 vs Opus 4.8: Agentic Coding Benchmarks, API Pricing, and Cost-Performance Tradeoffs Compared Read More »

NVIDIA BioNeMo Agent Toolkit Turns Biomolecular Models Into Callable Skills for AI Agents in Drug Discovery

AI scientists are becoming a new interface for scientific computing. These agents read papers, write code, generate hypotheses, call APIs, and inspect files. But science is not software engineering. No test suite turns green when a hypothesis is correct. Discovery stays iterative, uncertain, and grounded in the physical world. That gap is what NVIDIA is

NVIDIA BioNeMo Agent Toolkit Turns Biomolecular Models Into Callable Skills for AI Agents in Drug Discovery Read More »

✅

OCRmyPDF Tutorial: Convert Scanned Documents into Searchable PDF/A Files with Sidecar Text Extraction and Batch Processing

In this tutorial, we build an advanced, self-contained OCRmyPDF workflow. We start by installing the required system and Python dependencies, then create a synthetic image-only PDF for scanning so we can test OCR without relying on external files. From there, we use OCRmyPDF’s real public API to convert scanned documents into searchable PDFs, generate PDF/A

OCRmyPDF Tutorial: Convert Scanned Documents into Searchable PDF/A Files with Sidecar Text Extraction and Batch Processing Read More »

Liquid AI Ships LFM2.5-230M with llama.cpp, MLX, vLLM, SGLang, and ONNX Support for On-Device Inference

Liquid AI shipped LFM2.5-230M, it’s the company’s smallest model to date. The release targets a specific job: running agentic tasks on phones, robots, and automation devices. Both the base and instruction-tuned checkpoints are open-weight on Hugging Face. The pitch is narrow on purpose. This is not a general reasoning model. It is built for data

Liquid AI Ships LFM2.5-230M with llama.cpp, MLX, vLLM, SGLang, and ONNX Support for On-Device Inference Read More »

DeepSeek Releases DSpark, a Speculative Decoding Framework That Accelerates DeepSeek-V4 Per-User Generation 60–85% Over MTP-1

DeepSeek released DSpark, a speculative decoding framework, with open-source checkpoints and training code. It is a serving optimization, not a new model. The checkpoints DeepSeek-V4-Pro-DSpark and DeepSeek-V4-Flash-DSpark reuse the existing V4 weights, with a draft module attached. The DeepSeek research team also open-sourced DeepSpec, an MIT-licensed codebase for training and evaluating speculative decoding drafters. The

DeepSeek Releases DSpark, a Speculative Decoding Framework That Accelerates DeepSeek-V4 Per-User Generation 60–85% Over MTP-1 Read More »

OpenAI Previews GPT-5.6 With Sol, Terra, and Luna: Tiered Models, New Reasoning Modes, Limited Access

OpenAI has begun a limited preview of GPT-5.6, its next-generation model series. The lineup splits into three named tiers: Sol, Terra, and Luna. Sol is the flagship. Terra targets everyday production work. Luna is the fast, low-cost option. OpenAI is starting with a small group of trusted partners through the API and Codex. According to

OpenAI Previews GPT-5.6 With Sol, Terra, and Luna: Tiered Models, New Reasoning Modes, Limited Access Read More »

Meet container: Apple’s Open-Source Swift Tool for Running Linux Containers as Lightweight VMs on Apple Silicon

Apple research team recently released the container project. It is an open-source command-line tool written in Swift. It creates and runs Linux containers as lightweight virtual machines on a Mac. The project ships under the Apache 2.0 license and targets Apple silicon. Containers are how you ship reproducible environments from a laptop to a datacenter.

Meet container: Apple’s Open-Source Swift Tool for Running Linux Containers as Lightweight VMs on Apple Silicon Read More »

▶

DeepReinforce Releases Ornith-1.0: An Open-Source Coding Model Family That Learns Its Own RL Scaffolds

DeepReinforce has released Ornith-1.0, an open-source model family built for agentic coding. The lineup spans four sizes, from a 9B dense model to a 397B mixture-of-experts flagship. Every checkpoint ships under the MIT license on Hugging Face. The models are post-trained on top of pretrained Gemma 4 and Qwen 3.5. Most coding agents pair a

DeepReinforce Releases Ornith-1.0: An Open-Source Coding Model Family That Learns Its Own RL Scaffolds Read More »

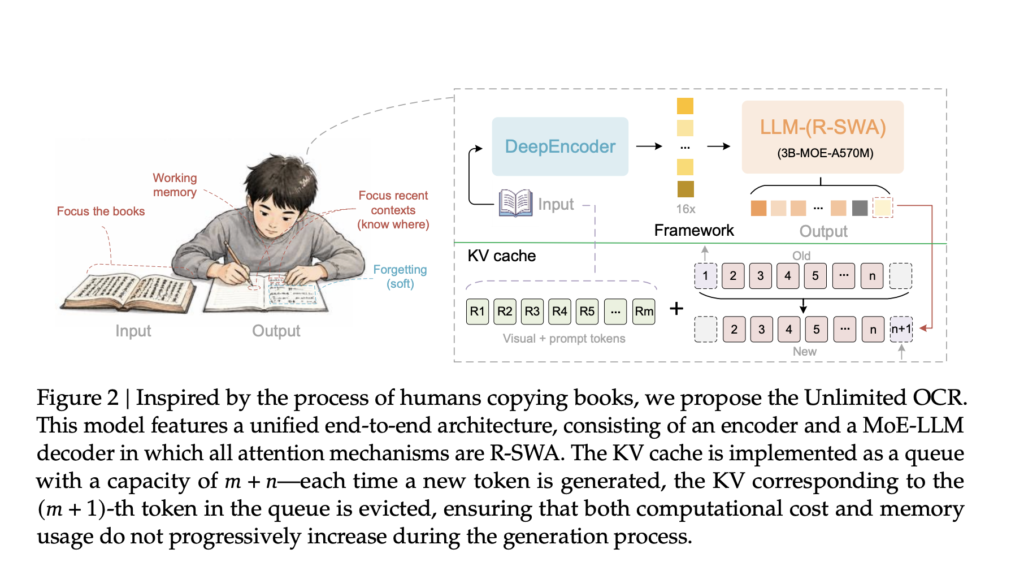
Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV Cache Flat for Long-Document Parsing

Most end-to-end OCR models slow down as output grows. Each generated token adds to the KV cache. Memory rises and generation drags. Parsing dozens of pages becomes impractical. Baidu’s Unlimited OCR addresses this directly. It swaps the decoder’s attention for a design that keeps memory constant. TL;DR Unlimited OCR is a 3B-parameter Mixture-of-Experts model, with

Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV Cache Flat for Long-Document Parsing Read More »