AI Paper Summary

Auto Added by WPeMatico

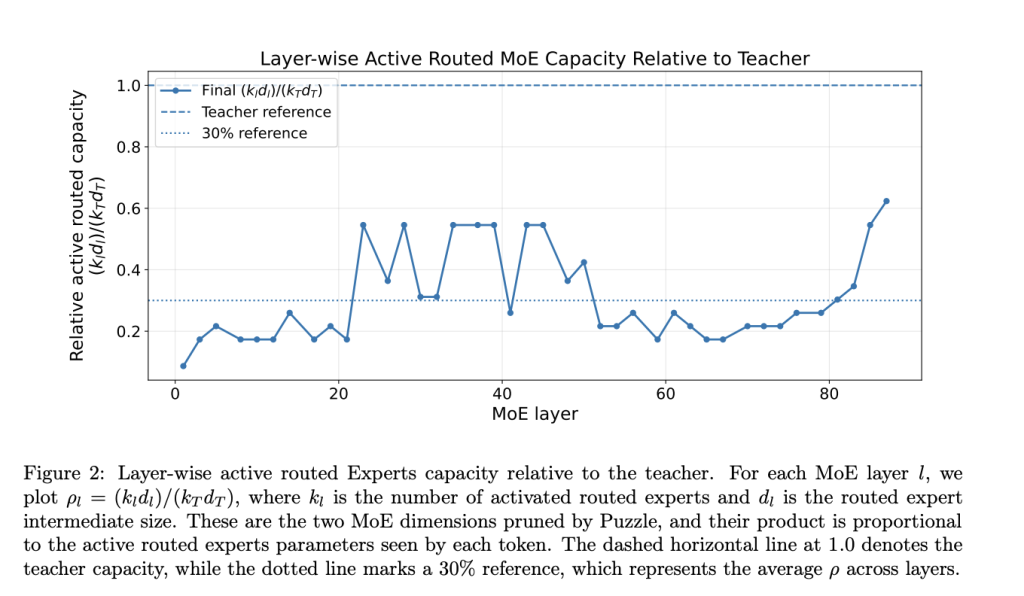
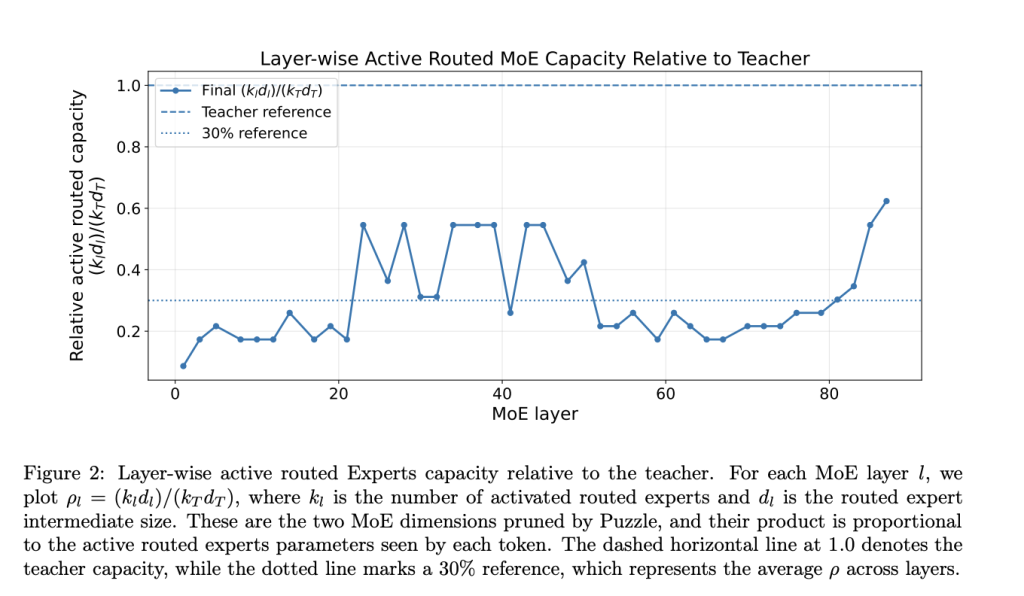
Meet Nemotron Labs 3 Puzzle 75B A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput

Large hybrid MoE models like Nemotron-3-Super are accurate but expensive to serve. Their active parameters, KV cache, and Mamba state cap how many users a node can hold at a given per-user token rate. NVIDIA AI team has released Nemotron-Labs-3-Puzzle-75B-A9B, a compressed variant of Nemotron-3-Super. The parent model has 120.7B total and 12.8B active parameters. […]
Meet Nemotron Labs 3 Puzzle 75B A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput Read More »

NVIDIA Releases Nemotron-Labs-3-Puzzle-75B-A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput at Matched User Throughput

Large hybrid MoE models like Nemotron-3-Super are accurate but expensive to serve. Their active parameters, KV cache, and Mamba state cap how many users a node can hold at a given per-user token rate. NVIDIA AI team has released Nemotron-Labs-3-Puzzle-75B-A9B, a compressed variant of Nemotron-3-Super. The parent model has 120.7B total and 12.8B active parameters.

NVIDIA Releases Nemotron-Labs-3-Puzzle-75B-A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput at Matched User Throughput Read More »

Robbyant Releases LingBot-VLA 2.0: An Open-Source 6B Vision-Language-Action (VLA) Model for Cross-Embodiment Robot Manipulation

Ant Group’s Robbyant has released LingBot-VLA 2.0, a Vision-Language-Action (VLA) foundation model for robots. The release includes a technical report, an Apache-2.0 codebase, and a 6B checkpoint. The research team targets a well-known gap: VLA models often work in labs but stumble in deployment. LingBot-VLA 2.0 advances the prior version along three practical axes. These

Robbyant Releases LingBot-VLA 2.0: An Open-Source 6B Vision-Language-Action (VLA) Model for Cross-Embodiment Robot Manipulation Read More »

Ant Group’s Robbyant Open-Sources LingBot-Vision: A 1B Boundary-Centric Vision Foundation Model for Dense Spatial Perception

Robbyant, the embodied-AI company within Ant Group, has open-sourced LingBot-Vision, a family of self-supervised Vision Transformers built for dense spatial perception. The weights ship under Apache-2.0 on Hugging Face in four sizes — ViT-giant, ViT-large, ViT-base, and ViT-small — together with a technical report and inference code. Most vision foundation models are trained for semantic

Ant Group’s Robbyant Open-Sources LingBot-Vision: A 1B Boundary-Centric Vision Foundation Model for Dense Spatial Perception Read More »

NVIDIA HORIZON: A Hands-Free Agent that Evolves Git Worktrees and Hits 100% RTL Benchmark Completion

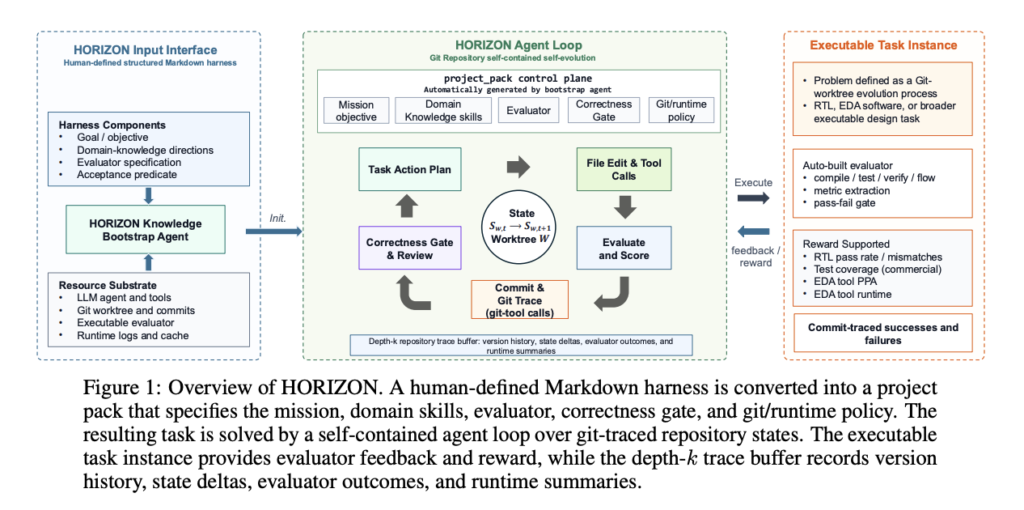
NVIDIA Research introduced HORIZON, a hands-free agent framework for hardware design. It treats hardware design as repository-level code evolution. This research team exercises the register-transfer level (RTL) instantiation. A structured Markdown harness becomes a project pack. A self-contained agent loop then evolves an isolated git worktree. It commits a version only when an executable acceptance

NVIDIA HORIZON: A Hands-Free Agent that Evolves Git Worktrees and Hits 100% RTL Benchmark Completion Read More »

NVIDIA Releases Nemotron-Labs-TwoTower: an Open-Weight Diffusion Language Model Built on a Frozen Autoregressive Nemotron-3-Nano-30B-A3B Backbone

NVIDIA has released Nemotron-Labs-TwoTower, a diffusion language model built on a pretrained autoregressive backbone. It ships as open weights under the NVIDIA Nemotron Open Model License. The release targets a throughput bottleneck in text generation. Autoregressive (AR) models decode one token at a time. That serial process caps generation throughput. Discrete diffusion language models take

NVIDIA Releases Nemotron-Labs-TwoTower: an Open-Weight Diffusion Language Model Built on a Frozen Autoregressive Nemotron-3-Nano-30B-A3B Backbone Read More »

Meta AI Releases Brain2Qwerty v2: A Non-Invasive MEG Brain-to-Text Pipeline Decoding Typed Sentences at 61% Word Accuracy

Meta AI just introduced Brain2Qwerty v2. It decodes natural sentences from non-invasive brain recordings in real time. The system reads magnetoencephalography (MEG) signals while a person types. It reconstructs what they typed, with no implant and no surgery. This is the follow-up to Brain2Qwerty v1, released in February 2025. Meta is also releasing the full

Meta AI Releases Brain2Qwerty v2: A Non-Invasive MEG Brain-to-Text Pipeline Decoding Typed Sentences at 61% Word Accuracy Read More »

DeepSeek Releases DSpark, a Speculative Decoding Framework That Accelerates DeepSeek-V4 Per-User Generation 60–85% Over MTP-1

DeepSeek released DSpark, a speculative decoding framework, with open-source checkpoints and training code. It is a serving optimization, not a new model. The checkpoints DeepSeek-V4-Pro-DSpark and DeepSeek-V4-Flash-DSpark reuse the existing V4 weights, with a draft module attached. The DeepSeek research team also open-sourced DeepSpec, an MIT-licensed codebase for training and evaluating speculative decoding drafters. The

DeepSeek Releases DSpark, a Speculative Decoding Framework That Accelerates DeepSeek-V4 Per-User Generation 60–85% Over MTP-1 Read More »

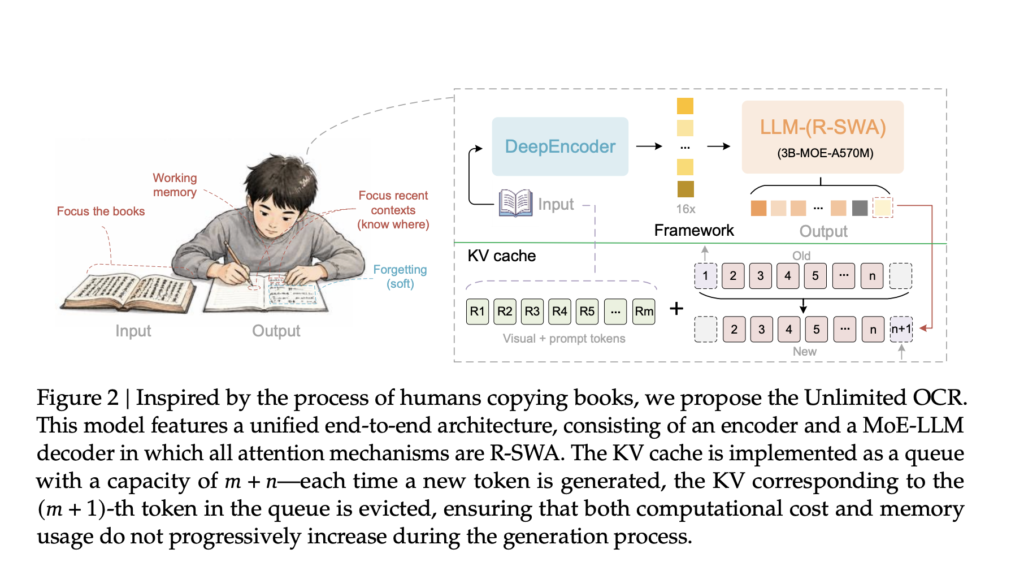
Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV Cache Flat for Long-Document Parsing

Most end-to-end OCR models slow down as output grows. Each generated token adds to the KV cache. Memory rises and generation drags. Parsing dozens of pages becomes impractical. Baidu’s Unlimited OCR addresses this directly. It swaps the decoder’s attention for a design that keeps memory constant. TL;DR Unlimited OCR is a 3B-parameter Mixture-of-Experts model, with

Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV Cache Flat for Long-Document Parsing Read More »

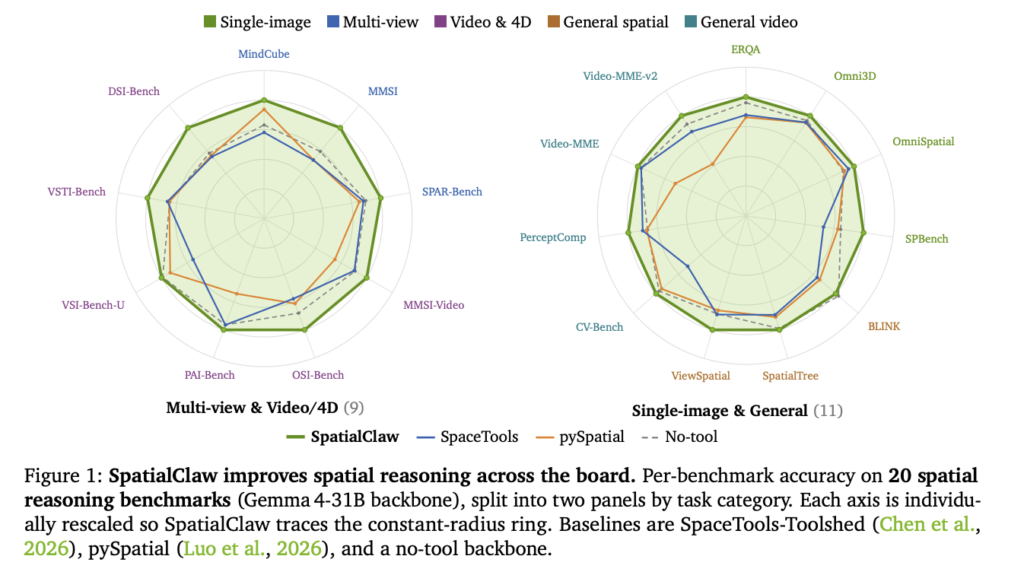
NVIDIA AI Introduce SpatialClaw: A Training-Free Agent That Treats Code as the Action Interface for Spatial Reasoning

NVIDIA Research has released SpatialClaw, a training-free framework for spatial reasoning. It targets a persistent weakness in vision-language models (VLMs). These models still struggle to judge where objects are, how they relate, and how they move in 3D. SpatialClaw does not retrain the model. Instead, it changes the action interface the agent uses to call

NVIDIA AI Introduce SpatialClaw: A Training-Free Agent That Treats Code as the Action Interface for Spatial Reasoning Read More »