AI Paper Summary

Auto Added by WPeMatico

Tencent Open-Sources AngelSpec: A Unified Training Framework for MTP and Block-Parallel Speculative Decoding on Hy3 Models

Tencent has released AngelSpec, an open-source, torch-native training framework for speculative-decoding draft models. The release covers both autoregressive multi-token prediction (MTP) and the block-parallel DFlash family. Most speculative-decoding work searches for one drafter that scores well on an averaged benchmark mixture. Real serving traffic does not look like that mixture. AngelSpec treats workload heterogeneity as […]
Tencent Open-Sources AngelSpec: A Unified Training Framework for MTP and Block-Parallel Speculative Decoding on Hy3 Models Read More »

Sakana AI’s Error Diffusion Trains Dale-Compliant Dual-Stream Networks, Reaching 96.7% MNIST and 61.7% CIFAR-10 Without Backpropagation

Backpropagation dominates deep learning, yet it uses a mechanism the brain likely cannot. Specifically, the backward pass needs exact transposes of forward weight matrices. This is the weight transport problem. Sakana AI’s new paper, Diffusing Blame, confronts this constraint directly. The research team trains networks that obey Dale’s principle while avoiding weight transport entirely. What

Sakana AI’s Error Diffusion Trains Dale-Compliant Dual-Stream Networks, Reaching 96.7% MNIST and 61.7% CIFAR-10 Without Backpropagation Read More »

Soofi Consortium Releases Soofi S 30B-A3B: An Open Hybrid Mamba-Transformer MoE Foundation Model For German And English

A German research consortium has published the pretraining report for Soofi S 30B-A3B. It is an open base model for German and English. Training ran end to end on Deutsche Telekom’s Industrial AI Cloud in Munich. Preview weights are on Hugging Face. It is worth noting that among some of the fully open base models

Soofi Consortium Releases Soofi S 30B-A3B: An Open Hybrid Mamba-Transformer MoE Foundation Model For German And English Read More »

Skyfall AI Releases MORPHEUS: A Persistent Enterprise Simulation Benchmark That Makes Continual Reinforcement Learning Necessary Under Structured Non-Stationarity

Most reinforcement learning benchmarks reset the world after every episode. Real operations never reset. Skyfall AI’s MORPHEUS targets that gap. It is a persistent enterprise simulation platform for continual reinforcement learning (CRL). What is MORPHEUS? MORPHEUS is grounded in the Big World Hypothesis (Javed & Sutton, 2024). It says the world’s complexity exceeds any agent’s

Skyfall AI Releases MORPHEUS: A Persistent Enterprise Simulation Benchmark That Makes Continual Reinforcement Learning Necessary Under Structured Non-Stationarity Read More »

🔒

Stanford Researchers Introduce TRACE: A Capability-Targeted Agentic Training System That Turns Recurrent Agent Failures Into Synthetic RL Environment

Agentic LLMs often fail the same way, again and again. A Stanford research team traced this to missing, reusable capabilities. Their system, TRACE, diagnoses those gaps and trains for them directly. TRACE stands for Turning Recurrent Agent failures into Capability-targeted training Environments. It was released open-source under an MIT license. What problem does TRACE solve?

Stanford Researchers Introduce TRACE: A Capability-Targeted Agentic Training System That Turns Recurrent Agent Failures Into Synthetic RL Environment Read More »

▶

Meet NeuroVFM: A New Neuroimaging Foundation Model Trained With Vol-JEPA on Uncurated Clinical MRI and CT Volumes

Frontier models learn mostly from public internet data. However, clinical neuroimaging rarely appears there, because MRI and CT scans contain identifiable facial features. Consequently, general models underperform on brain-imaging tasks. A University of Michigan research team addresses this gap with NeuroVFM, published in Nature Medicine. What is NeuroVFM? At its core, NeuroVFM is a generalist

Meet NeuroVFM: A New Neuroimaging Foundation Model Trained With Vol-JEPA on Uncurated Clinical MRI and CT Volumes Read More »

Ant Group’s Robbyant Unveils LingBot-VA 2.0: A Causal Video-Action Model Built Natively for Physical AI

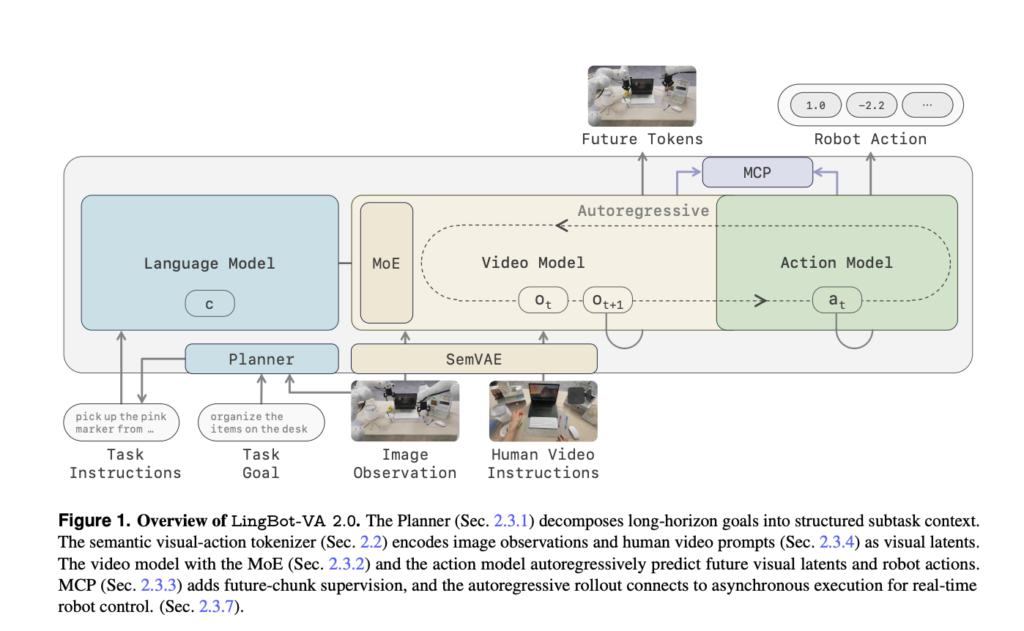
Robbyant, the embodied AI unit inside Ant Group, has released the LingBot-VA 2.0.The first embodied-native foundation model. It describes a video-action foundation model for generalist robot manipulation. The research team pretrains the whole stack for embodiment instead of fine-tuning a video generator. What is LingBot-VA 2.0? Most video-action models reuse two components built for digital

Ant Group’s Robbyant Unveils LingBot-VA 2.0: A Causal Video-Action Model Built Natively for Physical AI Read More »

▶

Kyutai Releases MuScriptor: An Open-Weight Decoder-Only Transformer for Multi-Instrument Music Transcription to MIDI

Automatic Music Transcription (AMT) converts an audio recording into symbolic notes, usually MIDI. Single-instrument transcription already works reasonably well. However, transcribing a full multi-instrument mix stays difficult. Kyutai and Mirelo team now release MuScriptor to close that gap. It is an open-weight model trained on real, multi-instrument recordings across many genres. This article explains how

Kyutai Releases MuScriptor: An Open-Weight Decoder-Only Transformer for Multi-Instrument Music Transcription to MIDI Read More »

Google Research Introduces SensorFM: A Wearable Health Foundation Model Pretrained on One Trillion Minutes of Sensor Data

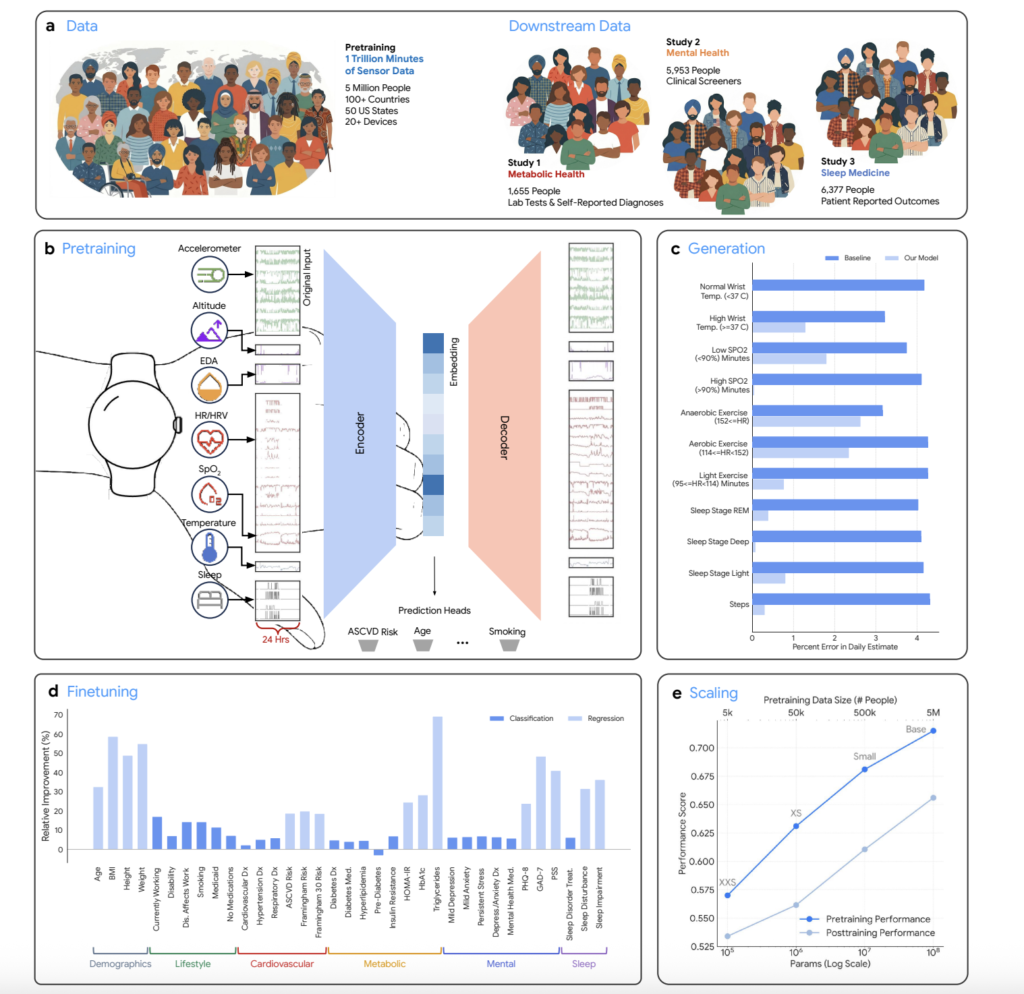
Most wearable health models are built one outcome at a time. That approach breaks down at thirty-five endpoints. Labels are expensive and retrospective annotation is infeasible. Google Research introduced SensorFM, a foundation model for wearable health pre-trained on more than 1 trillion minutes of sensor data from 5 million people. https://arxiv.org/pdf/2605.22759 What is SensorFM? SensorFM

Google Research Introduces SensorFM: A Wearable Health Foundation Model Pretrained on One Trillion Minutes of Sensor Data Read More »

Meet LingBot-World-Infinity: An Open Causal World Model With An Agentic Harness

Robbyant, Ant Group’s embodied-intelligence unit, has released LingBot-World-Infinity (LingBot-World 2.0). It is a causal video generation model that behaves as an interactive world simulator. It is how the team attacks two failure modes: long-horizon drift and interactive latency. What is LingBot-World-Infinity? An interactive world model generates video frame by frame, conditioned on a stream of

Meet LingBot-World-Infinity: An Open Causal World Model With An Agentic Harness Read More »