
AI Paper Summary

Auto Added by WPeMatico

Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable MuJoCo Physics Programs

MirroS released Code-as-World: a paradigm that represents physical worlds through executable world representations. The argument is narrow and testable: pixels are evidence of a physical scene, not its ontology. A video model can predict plausible frames without ever representing mass, contact, or gravity. So instead of pixels, latents, or captions, Code-as-World represents a scene as […]
Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable MuJoCo Physics Programs Read More »

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous Glucose Monitoring

Google Research and UNSW Sydney have released GlucoFM, a self-supervised foundation model for continuous glucose monitoring. Its core move is a split. Existing CGM models — CGMformer, GluFormer, CGM-JEPA — encode a glucose trace as one entangled sequence. GlucoFM decomposes it into a slow physiological “state” stream and a transient “event” stream, keeps the observation

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous Glucose Monitoring Read More »

Google Research Introduces ME-POIs: A Mobility-Informed Framework that Adds “How a Place Is Used” to Text-Based POI Embeddings

A team from Google Research and USC has released Mobility-Embedded POIs (ME-POIs), a framework that folds aggregate human movement into text-based place embeddings. The premise is that language models describe what a place is, but not how it is used. Two coffee shops can share a category, an address block, and a text vector, while

Google Research Introduces ME-POIs: A Mobility-Informed Framework that Adds “How a Place Is Used” to Text-Based POI Embeddings Read More »

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2 on a Single Workstation GPU

Frontier open-weight models are shipping faster than the hardware assumptions around them. Kimi-K3, GLM-5.2 and DeepSeek-V4-Flash are closing the capability gap with proprietary systems, but releasing parameters only determines who can obtain a model — not who can afford to run it. Serving them still assumes datacenter-class GPU clusters, and as agentic workloads push inference

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2 on a Single Workstation GPU Read More »

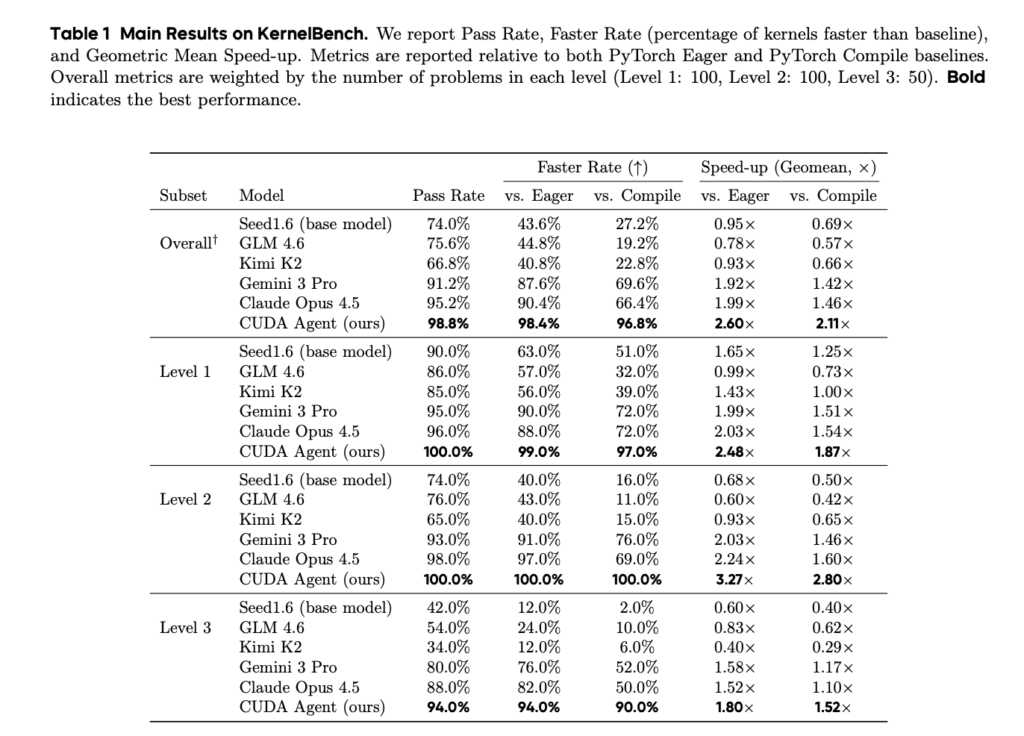
ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic RL System for CUDA Kernel Generation

ByteDance Seed and Tsinghua AIR have released CUDA Agent, an agentic reinforcement learning system that trains a large language model to write GPU kernels that beat a compiler. The gap it targets is narrow but stubborn: frontier models already produce correct CUDA, they just produce slow CUDA. On KernelBench, the base model Seed1.6 passes 74.0%

ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic RL System for CUDA Kernel Generation Read More »

Xiaomi’s MiLM Plus Releases PROVE: Perception-Aligned Object Removal Metrics RC-S and RC-T With a Real-World Video Benchmark

Object removal models have improved faster than the metrics used to judge them. Diffusion erasers now reconstruct shadows, reflections and occluded structure convincingly, yet PSNR, SSIM, LPIPS, ReMOVE and CFD frequently rank their outputs the wrong way. The root cause is structural: erasure is an ill-posed, one-to-many task, so no single ground truth exists to

Xiaomi’s MiLM Plus Releases PROVE: Perception-Aligned Object Removal Metrics RC-S and RC-T With a Real-World Video Benchmark Read More »

Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size

Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that treats content moderation as a single yes/no question rather than a fixed taxonomy of harm categories. Most guardrail models bake their category list into the weights, so re-targeting one to a new deployment context means retraining — and the same content

Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size Read More »

NVIDIA AI Releases NOOA: An Object-Oriented Python Framework That Turns an AI Agent Into a Single Python Class

NVIDIA Labs has open-sourced NOOA (NVIDIA Object-Oriented Agents), a model-agnostic Python framework for building AI agents. Agent development today is split across prompt templates, tool schemas, callback code, and workflow graphs. NOOA collapses all of it into one Python class. Methods are the actions the model can take. Fields are agent state. Docstrings are prompts.

NVIDIA AI Releases NOOA: An Object-Oriented Python Framework That Turns an AI Agent Into a Single Python Class Read More »

Microsoft’s SkillOpt Shows Optimized Agent Skill Artifacts Transfer Across Model Scales and Between Codex and Claude Code Harnesses

SkillOpt is a text-space optimizer developed by a team of researchers from Microsoft, Shanghai Jiao Tong University, Tongji University, and Fudan University. SkillOpt trains a single natural-language skill document while the target model stays frozen. An optimizer model reads scored rollouts and proposes bounded add/delete/replace edits. A held-out selection split accepts an edit only when

Microsoft’s SkillOpt Shows Optimized Agent Skill Artifacts Transfer Across Model Scales and Between Codex and Claude Code Harnesses Read More »

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains

DeepSeek published DeepSeek-V4-Flash-0731 on Hugging Face and moved the official V4-Flash API into public beta on July 31, 2026. The model card is explicit that this is the official release superseding the preview, and that the architecture and size are unchanged. The gains come from re-post-training, not a new design. The checkpoint ships with the

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains Read More »