
AI Paper Summary

Auto Added by WPeMatico

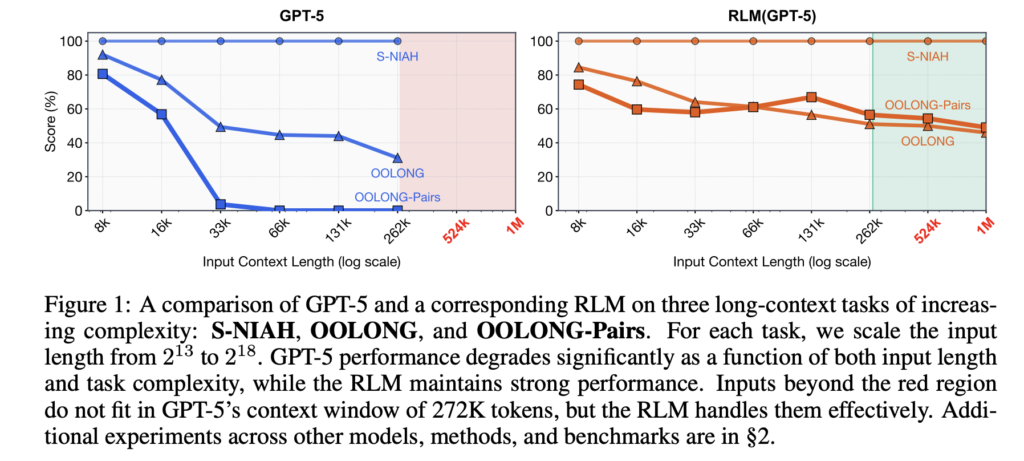
Recursive Language Models (RLMs): From MIT’s Blueprint to Prime Intellect’s RLMEnv for Long Horizon LLM Agents

Recursive Language Models aim to break the usual trade off between context length, accuracy and cost in large language models. Instead of forcing a model to read a giant prompt in one pass, RLMs treat the prompt as an external environment and let the model decide how to inspect it with code, then recursively call […]
Recursive Language Models (RLMs): From MIT’s Blueprint to Prime Intellect’s RLMEnv for Long Horizon LLM Agents Read More »

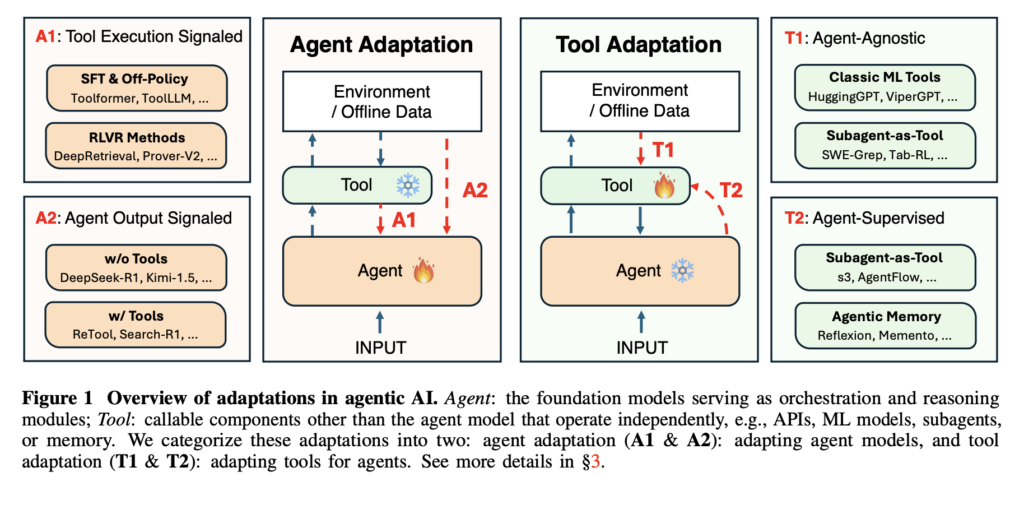
This AI Paper from Stanford and Harvard Explains Why Most ‘Agentic AI’ Systems Feel Impressive in Demos and then Completely Fall Apart in Real Use

Agentic AI systems sit on top of large language models and connect to tools, memory, and external environments. They already support scientific discovery, software development, and clinical research, yet they still struggle with unreliable tool use, weak long horizon planning, and poor generalization. The latest research paper ‘Adaptation of Agentic AI‘ from Stanford, Harvard, UC

This AI Paper from Stanford and Harvard Explains Why Most ‘Agentic AI’ Systems Feel Impressive in Demos and then Completely Fall Apart in Real Use Read More »

Google DeepMind Researchers Release Gemma Scope 2 as a Full Stack Interpretability Suite for Gemma 3 Models

Google DeepMind Researchers introduce Gemma Scope 2, an open suite of interpretability tools that exposes how Gemma 3 language models process and represent information across all layers, from 270M to 27B parameters. Its core goal is simple, give AI safety and alignment teams a practical way to trace model behavior back to internal features instead

Google DeepMind Researchers Release Gemma Scope 2 as a Full Stack Interpretability Suite for Gemma 3 Models Read More »

NVIDIA AI Releases Nemotron 3: A Hybrid Mamba Transformer MoE Stack for Long Context Agentic AI

NVIDIA has released the Nemotron 3 family of open models as part of a full stack for agentic AI, including model weights, datasets and reinforcement learning tools. The family has three sizes, Nano, Super and Ultra, and targets multi agent systems that need long context reasoning with tight control over inference cost. Nano has about

NVIDIA AI Releases Nemotron 3: A Hybrid Mamba Transformer MoE Stack for Long Context Agentic AI Read More »

OpenAI has Released the ‘circuit-sparsity’: A Set of Open Tools for Connecting Weight Sparse Models and Dense Baselines through Activation Bridges

OpenAI team has released their openai/circuit-sparsity model on Hugging Face and the openai/circuit_sparsity toolkit on GitHub. The release packages the models and circuits from the paper ‘Weight-sparse transformers have interpretable circuits‘. https://arxiv.org/pdf/2511.13653 What is a weight sparse transformer? The models are GPT-2 style decoder only transformers trained on Python code. Sparsity is not added after

OpenAI has Released the ‘circuit-sparsity’: A Set of Open Tools for Connecting Weight Sparse Models and Dense Baselines through Activation Bridges Read More »

Apple Researchers Release CLaRa: A Continuous Latent Reasoning Framework for Compression‑Native RAG with 16x–128x Semantic Document Compression

How do you keep RAG systems accurate and efficient when every query tries to stuff thousands of tokens into the context window and the retriever and generator are still optimized as 2 separate, disconnected systems? A team of researchers from Apple and University of Edinburgh released CLaRa, Continuous Latent Reasoning, (CLaRa-7B-Base, CLaRa-7B-Instruct and CLaRa-7B-E2E) a

Apple Researchers Release CLaRa: A Continuous Latent Reasoning Framework for Compression‑Native RAG with 16x–128x Semantic Document Compression Read More »

DeepSeek Researchers Introduce DeepSeek-V3.2 and DeepSeek-V3.2-Speciale for Long Context Reasoning and Agentic Workloads

How do you get GPT-5-level reasoning on real long-context, tool-using workloads without paying the quadratic attention and GPU cost that usually makes those systems impractical? DeepSeek research introduces DeepSeek-V3.2 and DeepSeek-V3.2-Speciale. They are reasoning-first models built for agents and targets high quality reasoning, long context and agent workflows, with open weights and production APIs. The

DeepSeek Researchers Introduce DeepSeek-V3.2 and DeepSeek-V3.2-Speciale for Long Context Reasoning and Agentic Workloads Read More »

Meta AI Researchers Introduce Matrix: A Ray Native a Decentralized Framework for Multi Agent Synthetic Data Generation

How do you keep synthetic data fresh and diverse for modern AI models without turning a single orchestration pipeline into the bottleneck? Meta AI researchers introduce Matrix, a decentralized framework where both control and data flow are serialized into messages that move through distributed queues. As LLM training increasingly relies on synthetic conversations, tool traces

Meta AI Researchers Introduce Matrix: A Ray Native a Decentralized Framework for Multi Agent Synthetic Data Generation Read More »

NVIDIA AI Releases Orchestrator-8B: A Reinforcement Learning Trained Controller for Efficient Tool and Model Selection

How can an AI system learn to pick the right model or tool for each step of a task instead of always relying on one large model for everything? NVIDIA researchers release ToolOrchestra, a novel method for training a small language model to act as the orchestrator- the ‘brain’ of a heterogeneous tool-use agent https://arxiv.org/pdf/2511.21689

NVIDIA AI Releases Orchestrator-8B: A Reinforcement Learning Trained Controller for Efficient Tool and Model Selection Read More »

DeepSeek AI Releases DeepSeekMath-V2: The Open Weights Maths Model That Scored 118/120 on Putnam 2024

How can an AI system prove complex olympiad level math problems in clear natural language while also checking that its own reasoning is actually correct? DeepSeek AI has released DeepSeekMath-V2, an open weights large language model that is optimized for natural language theorem proving with self verification. The model is built on DeepSeek-V3.2-Exp-Base, runs as

DeepSeek AI Releases DeepSeekMath-V2: The Open Weights Maths Model That Scored 118/120 on Putnam 2024 Read More »