
Software engineering

Auto Added by WPeMatico

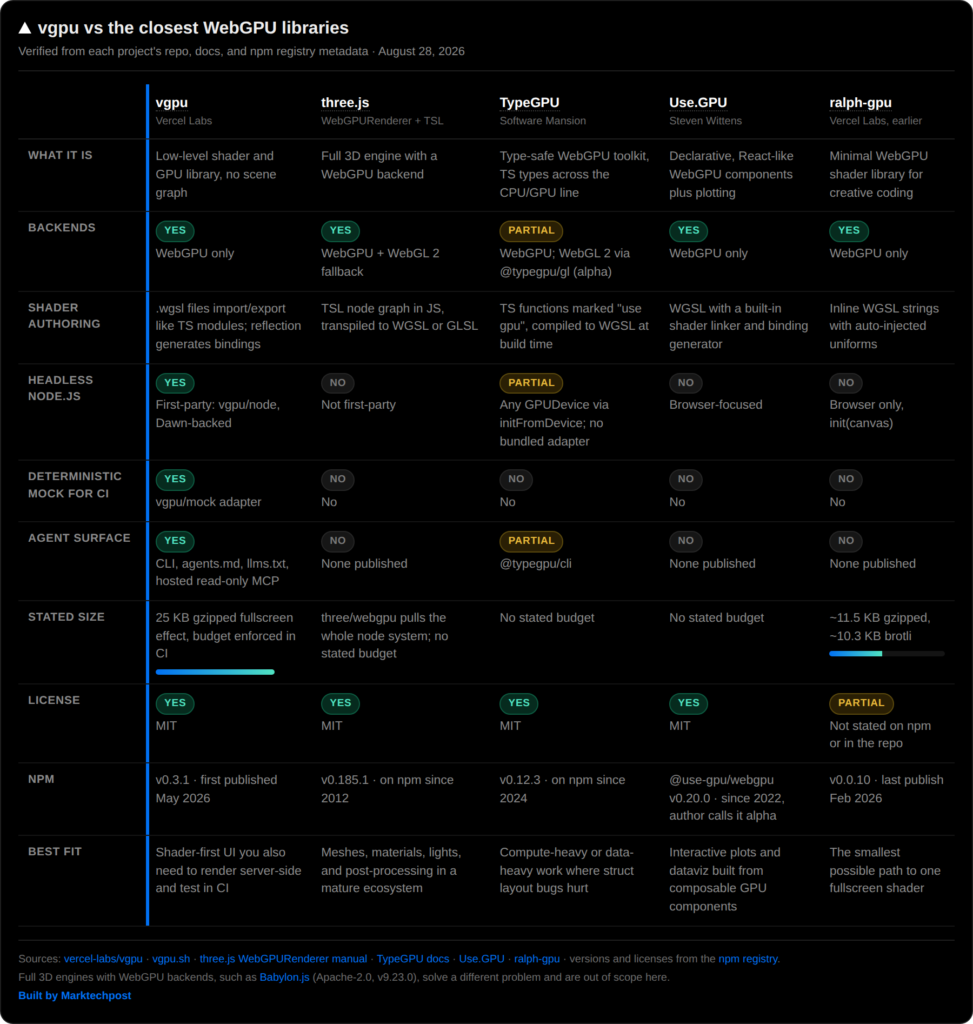
Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent Shaders

Shaders are still the hardest thing to ship on a normal web team. WebGPU gives you the hardware, then hands you adapters, bind group layouts, and pipeline descriptors before a single pixel moves. Vercel spent that cost internally building the shaders on vercel.com, and has now open-sourced the result. vgpu is a TypeScript library that […]

Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent Shaders Read More »

Best Agent Sandboxes in 2026: Cold Start, Per-Second Pricing, and Network Policy Across E2B, Daytona, Modal, Cloudflare, and Vercel

Every agent that writes code needs somewhere to run it. That “somewhere” is now a product category with at least a dozen vendors, four incompatible billing models, and marketing pages that quote cold starts measured under conditions nobody publishes. This comparison fixes the units. It covers the five platforms most teams shortlist — E2B, Daytona,

Best Agent Sandboxes in 2026: Cold Start, Per-Second Pricing, and Network Policy Across E2B, Daytona, Modal, Cloudflare, and Vercel Read More »

What Would Have to Be True for Agentic Coding to Replace Junior Engineers

I read every major model release. Most of them ship a coding number. The number goes up. The conclusion everyone draws is that junior engineers are finished. I think that conclusion is being reached the wrong way. People are reasoning from a benchmark score to a labor market outcome, skipping every step in between. So

What Would Have to Be True for Agentic Coding to Replace Junior Engineers Read More »

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device Models, Quantization, Runtime and Hardware Together

Model cards report quality under server-class, full-precision conditions. Those numbers rarely predict how the same model behaves on a phone. This week, Liquid AI released Pipette. It is an open-source platform for benchmarking foundation models on edge devices, built in partnership with Artificial Analysis as an independent methodology validator. Pipette treats on-device behavior as a

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device Models, Quantization, Runtime and Hardware Together Read More »

Meta AI Introduces MetaRoCE: A Clean-Sheet RDMA Transport Built for AI-Scale Ethernet

Training and serving frontier models is now a networking problem as much as a compute problem. Collective operations like all-reduce and all-to-all synchronize thousands of accelerators during training, and the slowest transfer sets the pace for the entire job. Even small amounts of network friction directly strand significant compute capacity. This week, Meta introduced MetaRoCE.

Meta AI Introduces MetaRoCE: A Clean-Sheet RDMA Transport Built for AI-Scale Ethernet Read More »

Fastino Releases GLiNER2.5: A Boundary-Prediction Architecture That Removes Span Enumeration From Information Extraction

Information extraction teams face a recurring choice. Small encoder models are cheap but rigid, and large language models are flexible but expensive per document. Fastino released GLiNER2.5 to narrow that gap. The release replaces span enumeration with boundary prediction: the model scores where an entity starts and ends instead of scoring every candidate span against

Fastino Releases GLiNER2.5: A Boundary-Prediction Architecture That Removes Span Enumeration From Information Extraction Read More »

The Developer’s Guide to NeMo Guardrails for Enterprise AI Safety

In this tutorial, we build an in-depth NeMo Guardrails pipeline that demonstrates how layered guardrails can control an LLM-based financial assistant across the full request lifecycle. We combine deterministic PII detection and redaction, LLM-based input and output self-checks, retrieval filtering, account-number masking, topical restrictions, and policy-based tool gating. We also implement stateful multi-turn interactions, detailed

The Developer’s Guide to NeMo Guardrails for Enterprise AI Safety Read More »

Anthropic Brings Claude Mythos 5 to Claude Security: Enterprise Teams Get Frontier Vulnerability Scanning Without Direct Model Access

Anthropic has moved its most cyber-capable model into a product security teams can switch on themselves. As of August 21, 2026, Claude Security scans run on Claude Mythos 5, the Mythos-class model that until now reached only vetted defenders through Project Glasswing. The scan connects to a GitHub repository, traces data flows across files, and

Anthropic Brings Claude Mythos 5 to Claude Security: Enterprise Teams Get Frontier Vulnerability Scanning Without Direct Model Access Read More »

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs

Liquid AI has released DSpark draft model checkpoints for three models in its LFM2.5 family: LFM2.5-1.2B-Instruct, LFM2.5-2.6B, and LFM2.5-8B-A1B. Each drafter adds a speculative decoding path to an existing target model. A roughly 300M-parameter draft proposes a block of nine candidate tokens, and the target model verifies the whole block in a single forward pass.

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs Read More »

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands

NVIDIA has released TensorRT Model Connect (TRTMC) in public preview, an open-source project that takes a supported Hugging Face or local checkpoint to end-to-end TensorRT inference in two commands. There is no intermediate ONNX export step. The build produces a versioned .bundle artifact that runs through native C++ task APIs, so inference can execute in

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands Read More »