
Software engineering

Auto Added by WPeMatico

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs

Liquid AI has released DSpark draft model checkpoints for three models in its LFM2.5 family: LFM2.5-1.2B-Instruct, LFM2.5-2.6B, and LFM2.5-8B-A1B. Each drafter adds a speculative decoding path to an existing target model. A roughly 300M-parameter draft proposes a block of nine candidate tokens, and the target model verifies the whole block in a single forward pass. […]
Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs Read More »

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands

NVIDIA has released TensorRT Model Connect (TRTMC) in public preview, an open-source project that takes a supported Hugging Face or local checkpoint to end-to-end TensorRT inference in two commands. There is no intermediate ONNX export step. The build produces a versioned .bundle artifact that runs through native C++ task APIs, so inference can execute in

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands Read More »

DeepSeek AI Releases DeepSeek Harness in Developer Preview: An MIT-Licensed Agent Harness Where Everything is a Plugin

DeepSeek released DeepSeek Harness v0.1 in developer preview and published the full source code under the MIT license. The project ships as dsh at deepseek-ai/deepseek-harness. A harness is the layer between a model and the environment it acts in — the tools, files, sandboxes, and control loop that let an agent keep working. DeepSeek frames

DeepSeek AI Releases DeepSeek Harness in Developer Preview: An MIT-Licensed Agent Harness Where Everything is a Plugin Read More »

Z.ai Ships GLM-5.3 Without Retraining the Base Model: Better at Complex Coding and Long-Horizon Tasks

Z.ai just released GLM-5.3. GLM-5.3 runs on the same 743B base model as GLM-5.2. Every reported gain comes from scaled post-training: more task environments, more environment types, longer training. The results land in two places. Coding jumps most on the longest-horizon benchmarks, with Terminal-Bench 3.0 moving from 4.6 to 28.3. Cybersecurity moved further than Z.ai

Z.ai Ships GLM-5.3 Without Retraining the Base Model: Better at Complex Coding and Long-Horizon Tasks Read More »

Meet Needle 2: An Open 45M-Parameter Tool-Calling Model That Ships as a 14MB Binary and Runs a Full Session in 28MB of RAM

Cactus Compute has released Needle 2, an open 45M-parameter model for tool calling, device use, and structured extraction. The entire model ships as a single 14MB binary that runs a full session in about 28MB of RAM. Weights are trained and deployed at CQ2-bit using Cactus Quants, and the model is sealed inside the company’s

Meet Needle 2: An Open 45M-Parameter Tool-Calling Model That Ships as a 14MB Binary and Runs a Full Session in 28MB of RAM Read More »

Google AI Just Released Gemini 3.7 Flash: A Coding and Agent Model at $0.75/1M Input Tokens

Google has released Gemini 3.7 Flash, the newest model in its Flash tier, three weeks after Gemini 3.6 Flash. The model card describes it as a refinement of 3.6 Flash with algorithmic improvements to the core reasoning foundation — not a new pretraining run. It accepts text, images, audio, and video across a 1M-token context

Google AI Just Released Gemini 3.7 Flash: A Coding and Agent Model at $0.75/1M Input Tokens Read More »

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with 3B Active Parameters, and NeMo Switchyard Model Router

NVIDIA introduced open technologies for building always-on AI agents from systems of specialized models. Two artifacts shipped together. Nemotron 3.5 Lightning is a lightweight, customizable open model built for high-volume agentic tasks, and NeMo Switchyard is an open source routing library that directs each step of an agent workflow to the most capable and efficient

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with 3B Active Parameters, and NeMo Switchyard Model Router Read More »

webAI Releases TwIL-LM: A 1.7B and 3B Formal-Logic Model Family for Autoformalization on Local Hardware

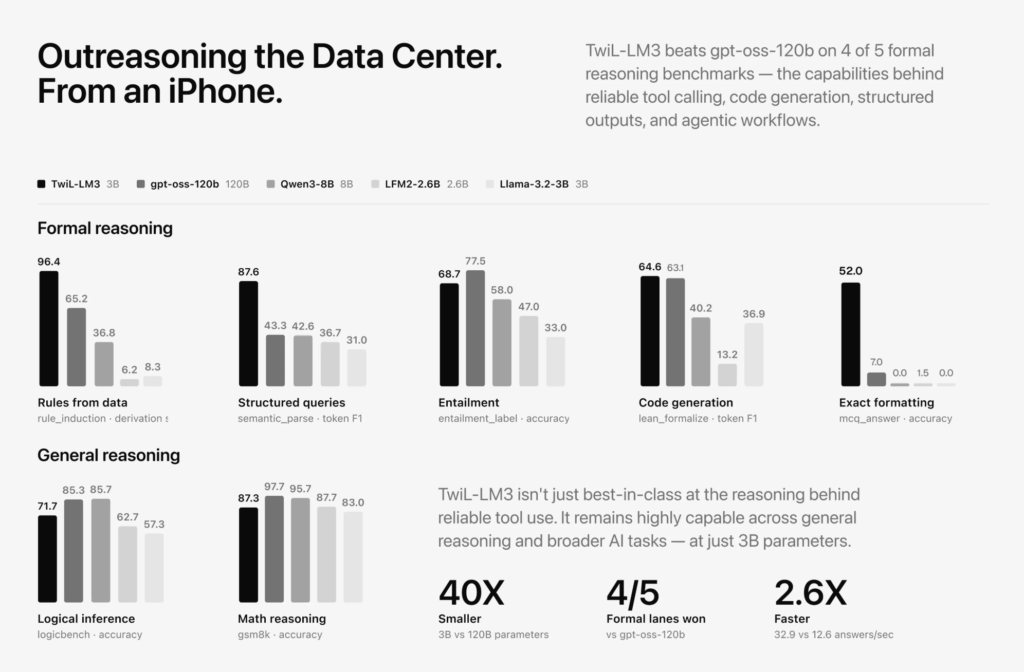
webAI has released TwIL-LM, a two-model family of formal-logic reasoners at 1.7B and 3B parameters. The 3B member, TwIL-LM3, is a merged fine-tune of SmolLM3-3B; the 1.7B member is a PEFT LoRA adapter for SmolLM2-1.7B-Instruct. Both target autoformalization: translating English into first-order logic and checking whether a conclusion follows from its premises. Both run locally,

webAI Releases TwIL-LM: A 1.7B and 3B Formal-Logic Model Family for Autoformalization on Local Hardware Read More »

Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size

Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that treats content moderation as a single yes/no question rather than a fixed taxonomy of harm categories. Most guardrail models bake their category list into the weights, so re-targeting one to a new deployment context means retraining — and the same content

Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size Read More »

Tencent Cloud Open-Sources TencentDB Agent Memory v2.0: A Team-Level Memory Hub for AI Coding Agents

Tencent Cloud has open-sourced TencentDB Agent Memory v2.0, a team-level memory hub for AI agents. The idea is super simple: if project context was already explained once, a new session should not need it repeated. The system turns conversations, documents and code into four reusable memory assets — Chat Memory, Skill, LLM-Wiki and Code-Graph —

Tencent Cloud Open-Sources TencentDB Agent Memory v2.0: A Team-Level Memory Hub for AI Coding Agents Read More »