Open Source

Auto Added by WPeMatico

Perplexity Open Sources Lily: A Rust + Metal Inference Engine for Qwen3.6-35B-A3B on Apple Silicon

Perplexity has open sourced Lily, the local inference engine behind Hybrid Compute in Perplexity Computer. It is a single-process runtime: a Rust layer loads the checkpoint and drives the generation loop, an OpenAI-compatible chat-completions API streams tokens, and hand-written Metal kernels execute the model. Neither PyTorch nor MLX sits in the execution path. Lily is […]
Perplexity Open Sources Lily: A Rust + Metal Inference Engine for Qwen3.6-35B-A3B on Apple Silicon Read More »

Qwen Developers Open-Sources zg (zvec-grep): A Local-First Search Layer Unifying ripgrep, BM25, and Vector Search

Coding agents spend a large share of their tool budget on search. When the target is a known symbol, ripgrep answers it exactly. When the target is a behavior described in plain language, keyword matching often misses, and the agent falls back to guessing terms, reading whole files, and assembling context by hand. Each of

Qwen Developers Open-Sources zg (zvec-grep): A Local-First Search Layer Unifying ripgrep, BM25, and Vector Search Read More »

Meet Switchyard: A Rust Proxy and Library That Routes and Translates LLM Traffic Across OpenAI and Anthropic APIs

Teams running coding agents hit the same wall. Claude Code speaks the Anthropic Messages API, Codex CLI speaks OpenAI, and the model a team actually wants to serve sits behind vLLM, NVIDIA NIM, or Ollama. Rewriting the agent is not an option, so the translation layer has to live somewhere else. Switchyard is NVIDIA’s answer:

Meet Switchyard: A Rust Proxy and Library That Routes and Translates LLM Traffic Across OpenAI and Anthropic APIs Read More »

Keenable AI Open-Sources NEEDLE: A Live Search Benchmark That Rebuilds Its Query Set Every Hour

How do you benchmark a web search API when the thing being tested can read the answer key? A search agent has a fetch tool. If the gold labels sit in a public dataset, the agent can download them mid-evaluation and skip retrieval entirely. A similar problem arises when the answers are already encoded in

Keenable AI Open-Sources NEEDLE: A Live Search Benchmark That Rebuilds Its Query Set Every Hour Read More »

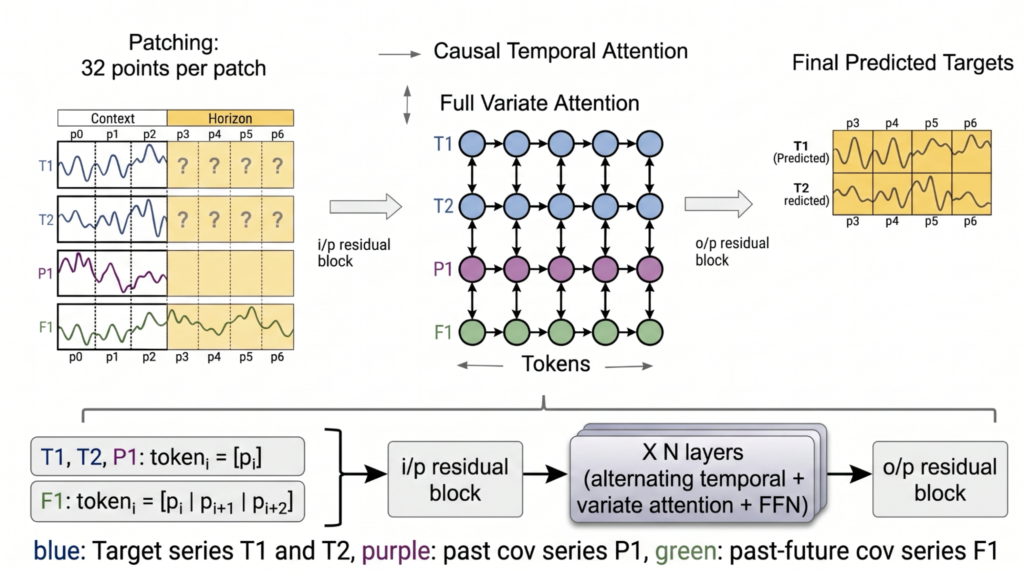
Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For Multivariate Time Series Forecasting

Google Research has released TimesFM-3, a 330 million parameter time series foundation model that forecasts multiple related series in a single forward pass. Every TimesFM checkpoint through 2.5 was univariate: one series, its own history, nothing else. TimesFM-3 is pretrained natively for multivariate forecasting on more than 1 trillion time points, and accepts multiple targets,

Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For Multivariate Time Series Forecasting Read More »

OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI Startup, and One Trust Boundary Per Gateway

The OpenClaw team has just released OpenClaw 2.0. The team shipped nothing for nearly seven weeks, after 106 releases in the previous 230 days. The update rewrites installation and rebuilds the browser Control UI. It also moves sessions and transcripts into SQLite and adds shared cloud sessions. Is it deployable? Yes for single-operator and single-team

OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI Startup, and One Trust Boundary Per Gateway Read More »

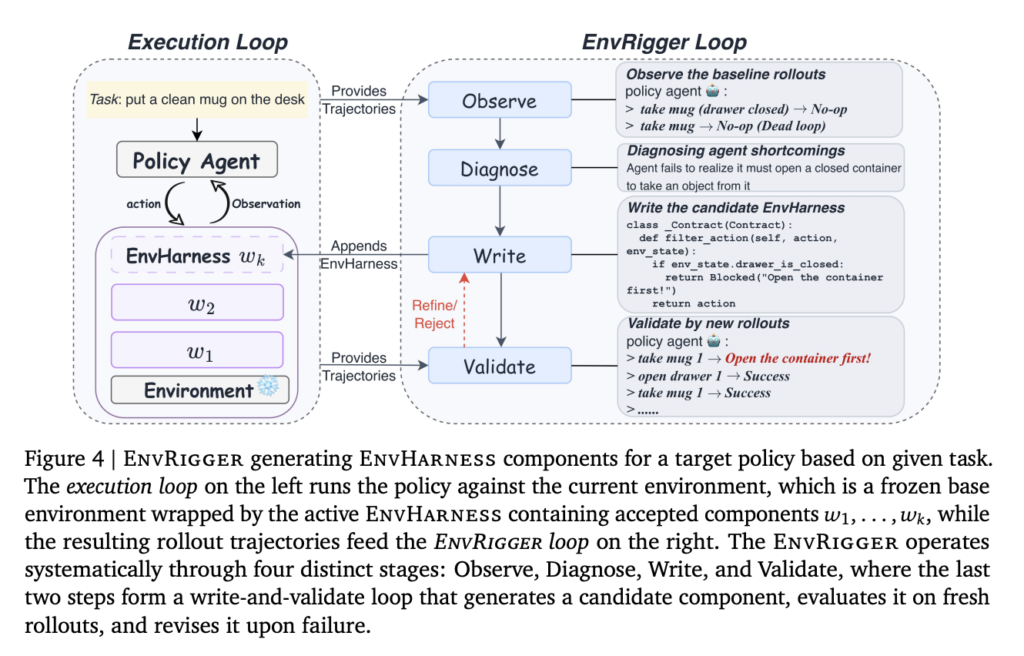
Google AI Introduces EnvHarness: A Programmable Layer That Turns Static Agent Environments Into Adaptive Training Worlds

A team of researchers from Google Cloud AI Research, Washington University in St. Louis and UNC Chapel Hill has released EnvHarness, a programmable layer that turns a static agent benchmark into one that adapts to the policy training on it. LLM agents now learn less from curated text and more from interactive environments, but those

Google AI Introduces EnvHarness: A Programmable Layer That Turns Static Agent Environments Into Adaptive Training Worlds Read More »

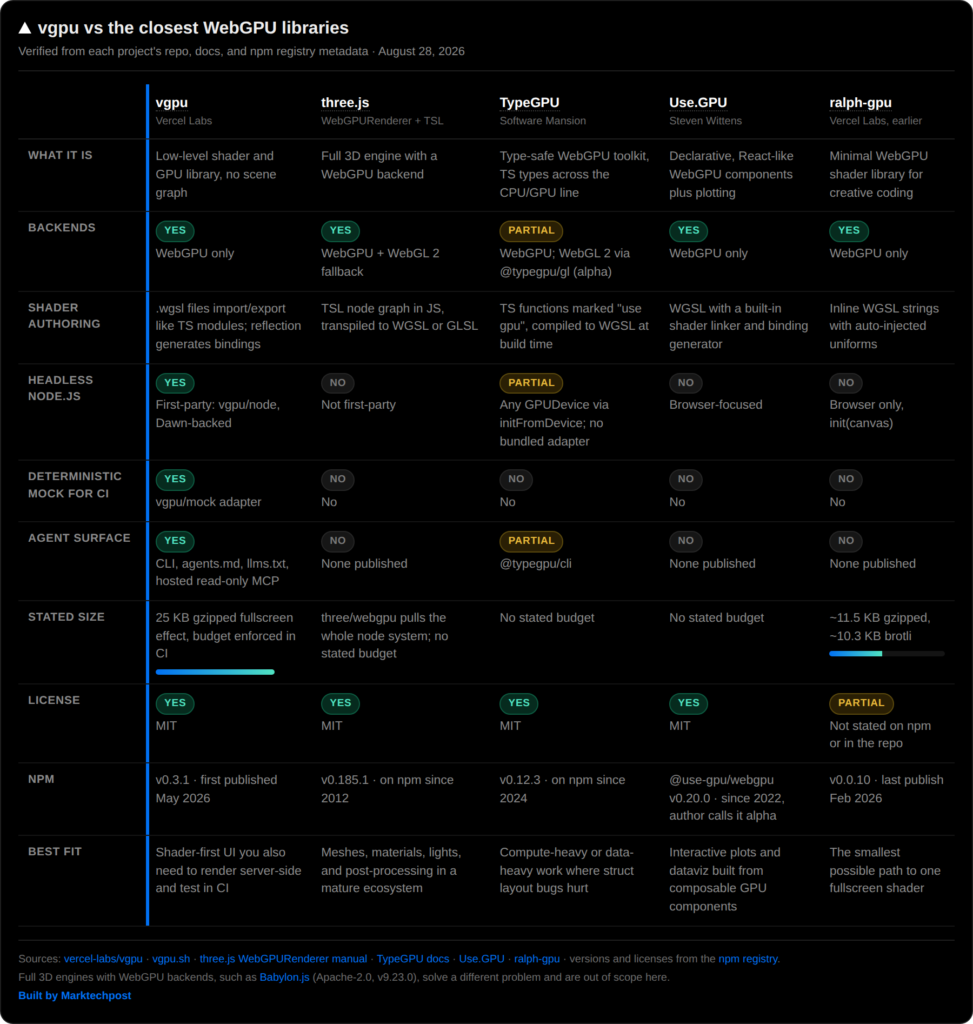
Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent Shaders

Shaders are still the hardest thing to ship on a normal web team. WebGPU gives you the hardware, then hands you adapters, bind group layouts, and pipeline descriptors before a single pixel moves. Vercel spent that cost internally building the shaders on vercel.com, and has now open-sourced the result. vgpu is a TypeScript library that

Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent Shaders Read More »

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device Models, Quantization, Runtime and Hardware Together

Model cards report quality under server-class, full-precision conditions. Those numbers rarely predict how the same model behaves on a phone. This week, Liquid AI released Pipette. It is an open-source platform for benchmarking foundation models on edge devices, built in partnership with Artificial Analysis as an independent methodology validator. Pipette treats on-device behavior as a

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device Models, Quantization, Runtime and Hardware Together Read More »

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs

Liquid AI has released DSpark draft model checkpoints for three models in its LFM2.5 family: LFM2.5-1.2B-Instruct, LFM2.5-2.6B, and LFM2.5-8B-A1B. Each drafter adds a speculative decoding path to an existing target model. A roughly 300M-parameter draft proposes a block of nine candidate tokens, and the target model verifies the whole block in a single forward pass.

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs Read More »