
Large Language Model

Auto Added by WPeMatico

Cognition Releases SWE-2: A Kimi K3 Post-Trained Coding Model That Matches Fable 5.1 on FrontierCode at 64% Lower Cost

Cognition, the company behind the Devin coding agent, has released SWE-2, its most capable coding model to date. SWE-2 is post-trained with reinforcement learning from Kimi K3, Moonshot AI’s 2.8T-parameter open model. Cognition reports a score of 50.0% on FrontierCode 1.1 Main, within 1 point of Fable 5.1 at 64% lower cost. It is also […]
Cognition Releases SWE-2: A Kimi K3 Post-Trained Coding Model That Matches Fable 5.1 on FrontierCode at 64% Lower Cost Read More »

Fly Language Model (FLM) Wires the Full Fruit Fly Connectome Into a Frozen 1.2B LLM, and Its Own Controls Show the Wiring Does Not Help

The Fly Language Model (FLM) is a public chatbot that couples the complete retained MaleCNS v1.0 fruit fly connectome to a frozen LiquidAI LFM2.5-1.2B-Instruct backbone. The developer who created the FLM calls it the world’s first Fly Language Model, built on an architecture called GPF (Generative Pre-trained Fly). It does not use the GPF label,

Fly Language Model (FLM) Wires the Full Fruit Fly Connectome Into a Frozen 1.2B LLM, and Its Own Controls Show the Wiring Does Not Help Read More »

Cohere Releases North Small Translate: A 218B MoE Translation Model That Scores 83.6 on WMT26 Across 50 Languages

Cohere has released North Small Translate, an open-weight machine translation model from Cohere and Cohere Labs. It is a sparse Mixture-of-Experts (MoE) model with 218B total and 25B active parameters. It covers 50 languages, from Albanian to Vietnamese. On Cohere’s WMT26 evaluation, it scores 83.6 averaged across all languages. Cohere says that beats DeepL and

Cohere Releases North Small Translate: A 218B MoE Translation Model That Scores 83.6 on WMT26 Across 50 Languages Read More »

DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse

Long-horizon agents have turned LLM serving into an input-heavy workload. Repeated prefills and million-token contexts leave KV caches that strain HBM, SSD capacity, and bandwidth. DeepSeek AI built its newest release around that exact bottleneck. DeepSeek-V4.1-Flash is a multimodal Mixture-of-Experts model with 552B backbone parameters, 196B additional Engram parameters, and a 1M-token context window. It

DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse Read More »

Google DeepMind Releases AlphaGenome Atlas With Precomputed Molecular Effect Predictions and AVI Scores for 9 Billion Human DNA Variants

Google DeepMind has released AlphaGenome Atlas, a catalogue of precomputed predictions for the molecular effects of every possible single-nucleotide variant in the human genome. That is roughly 9 billion single-letter changes. The release also introduces the AlphaGenome Variant Impact (AVI) score, a single number that ranks variants by predicted impact, plus per-variant feature attributions and

Google DeepMind Releases AlphaGenome Atlas With Precomputed Molecular Effect Predictions and AVI Scores for 9 Billion Human DNA Variants Read More »

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page

Last week, Reducto announced r-1. It is the first model in a new parsing family built on a rewritten architecture, and it replaces the company’s multi stage agentic OCR with one full page pass. Reducto says r-1 is more accurate than its most powerful legacy agentic models, faster, and up to 6x cheaper. Is it

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page Read More »

OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34 Benchmarks and Built to Run On Device

OpenBMB has released MiniCPM5-2B, the second checkpoint in the MiniCPM5 series and the follow-up to MiniCPM5-1B. It is a dense causal language model with 2,516,756,480 parameters, of which 1,981,982,720 sit outside the embeddings. It uses 42 layers, grouped-query attention with 16 query heads and 2 key/value heads, and a native context window of 131,072 tokens.

OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34 Benchmarks and Built to Run On Device Read More »

Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot Manipulation Tasks and 50,129 Trajectories

Robot manipulation datasets have grown far slower than the models trained on them, mostly because collection stays closed and centralized. Expert operators gather demonstrations on lab hardware, process them offline, and ship a fixed benchmark that never grows again. A research team from Axis Robotics, UC Berkeley, Georgia Tech, NTU… is proposing a different shape

Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot Manipulation Tasks and 50,129 Trajectories Read More »

IFM Releases K2 Horizon: Six Apache 2.0 Models From 0.9B to 375B

Most open model launches release one checkpoint and a benchmark table. The Institute of Foundation Models (IFM) released something wider last week. IFM is the frontier lab launched by MBZUAI in May 2025. K2 Horizon is a fleet of six models: 375B-A23B, 36B-A4B, 32B, 7B, 3.7B and 0.9B. Shipping alongside them are the pre-training corpus,

IFM Releases K2 Horizon: Six Apache 2.0 Models From 0.9B to 375B Read More »

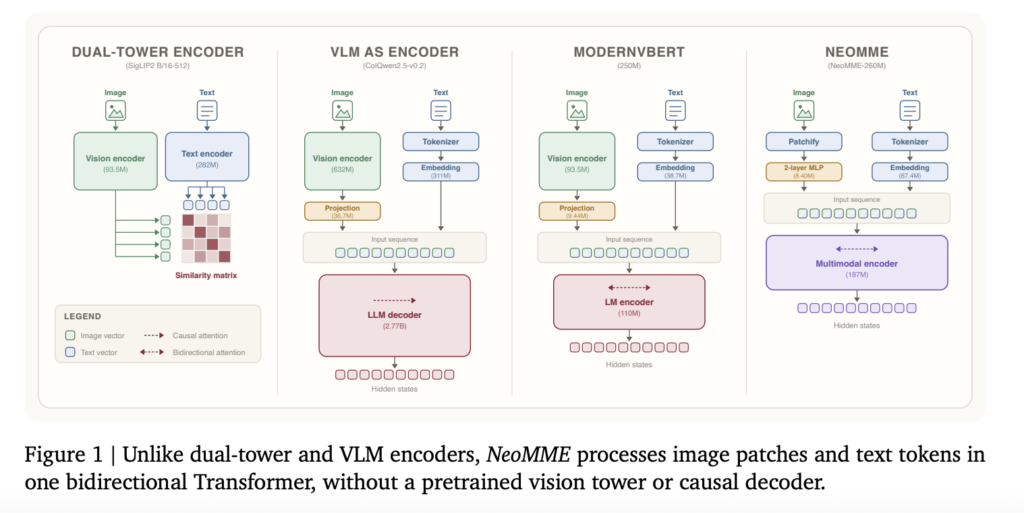
H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder

Most visual document retrievers in production today are hand-me-downs. ColPali and the models that followed it take a generative vision-language model and repurpose it as an encoder. The result still carries a separately pretrained vision tower and a causal decoder that never generates a token. That is parameter and compute overhead for a task that

H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder Read More »