
Editors Pick

Auto Added by WPeMatico

Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown

Cohere has released Parse (parse-v5.0), a document parsing model aimed at high-volume enterprise ingestion. It is a 2.3B-parameter vision language model with an 8,192-token context window and a ~4.6GB footprint, built on Cohere Labs’ North-Micro-Vision-Instruct architecture. Parse takes a PDF, PPT or JPEG page as a base64-encoded data URI and returns Markdown containing text in […]
Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown Read More »

Best Agent Sandboxes in 2026: Cold Start, Per-Second Pricing, and Network Policy Across E2B, Daytona, Modal, Cloudflare, and Vercel

Every agent that writes code needs somewhere to run it. That “somewhere” is now a product category with at least a dozen vendors, four incompatible billing models, and marketing pages that quote cold starts measured under conditions nobody publishes. This comparison fixes the units. It covers the five platforms most teams shortlist — E2B, Daytona,

Best Agent Sandboxes in 2026: Cold Start, Per-Second Pricing, and Network Policy Across E2B, Daytona, Modal, Cloudflare, and Vercel Read More »

From In-Silico to Wet-Lab: Evaluating AI Protein Design Performance

In this tutorial, we use Anthropic’s claude-protein-binder-design dataset, which contains 1,440 AI-designed miniprotein binders tested against 16 targets. Because the release includes both computational predictions and real wet-lab results from two independent labs, we can go beyond simply studying the designs. We evaluate how well structure predictors identify successful binders, whether combining predictions improves performance,

From In-Silico to Wet-Lab: Evaluating AI Protein Design Performance Read More »

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous Glucose Monitoring

Google Research and UNSW Sydney have released GlucoFM, a self-supervised foundation model for continuous glucose monitoring. Its core move is a split. Existing CGM models — CGMformer, GluFormer, CGM-JEPA — encode a glucose trace as one entangled sequence. GlucoFM decomposes it into a slow physiological “state” stream and a transient “event” stream, keeps the observation

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous Glucose Monitoring Read More »

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token Context

Z.ai has released GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series and the cheapest capable coding model the lab has shipped. It is a mixture-of-experts model with 320B total parameters and 18B active per token, a 1,048,576-token context window, and image and video input — released under an MIT license with weights on

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token Context Read More »

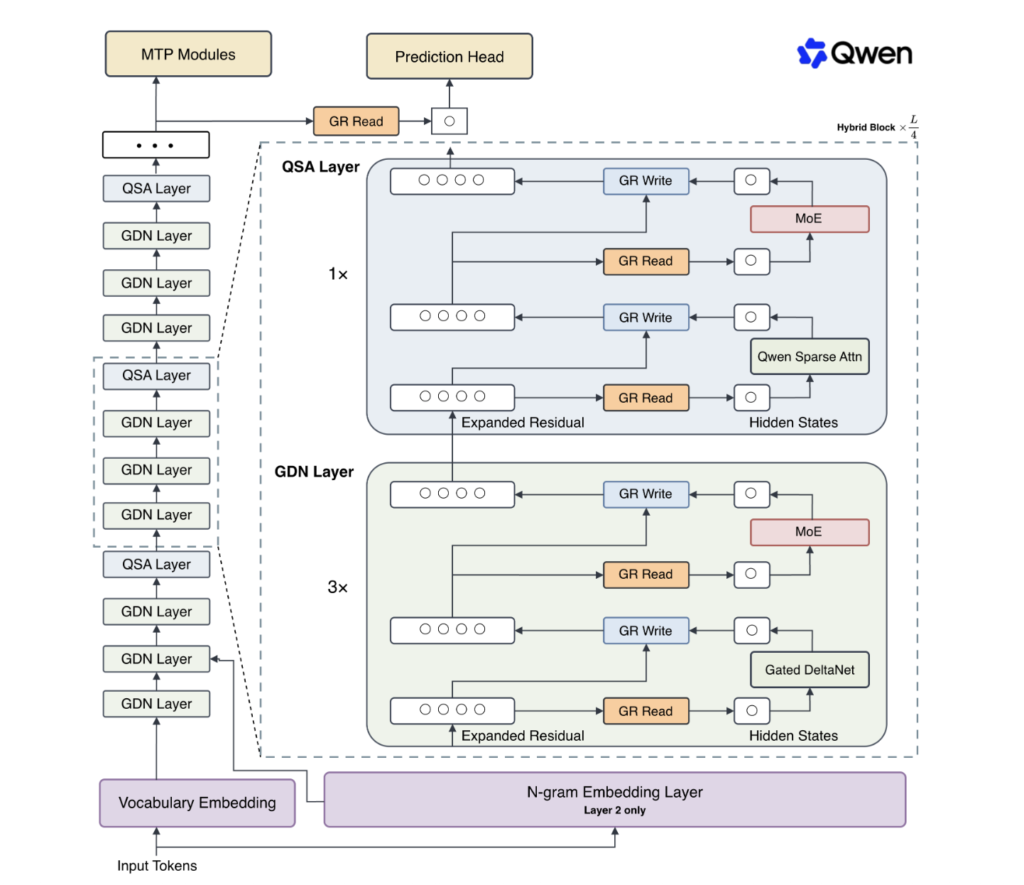
Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B Active Parameters Previewing the Qwen4 Architecture

Alibaba’s Qwen team has released Qwen3.8-Flash-Next, an open-weight multimodal Mixture-of-Experts model built for cost per token. The checkpoint pairs a 125B backbone with a 51B N-gram embedding table and a 4B multi-token prediction module. Only 6B parameters activate per token. The team positions it as an early preview of the architecture that will underpin Qwen4,

Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B Active Parameters Previewing the Qwen4 Architecture Read More »

What Would Have to Be True for Agentic Coding to Replace Junior Engineers

I read every major model release. Most of them ship a coding number. The number goes up. The conclusion everyone draws is that junior engineers are finished. I think that conclusion is being reached the wrong way. People are reasoning from a benchmark score to a labor market outcome, skipping every step in between. So

What Would Have to Be True for Agentic Coding to Replace Junior Engineers Read More »

IBM Releases Granite 4.2: Bringing Native Reasoning and Agentic RL to Open Enterprise Models

IBM has released Granite 4.2, a family of open reasoning language models in 3B, 8B, and 30B parameter sizes. Unlike earlier Granite releases, which were instruction-following assistants, Granite 4.2 is built around explicit reasoning. Every model can emit a chain of thought before answering, and every model exposes a thinking / non-thinking switch plus a

IBM Releases Granite 4.2: Bringing Native Reasoning and Agentic RL to Open Enterprise Models Read More »

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device Models, Quantization, Runtime and Hardware Together

Model cards report quality under server-class, full-precision conditions. Those numbers rarely predict how the same model behaves on a phone. This week, Liquid AI released Pipette. It is an open-source platform for benchmarking foundation models on edge devices, built in partnership with Artificial Analysis as an independent methodology validator. Pipette treats on-device behavior as a

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device Models, Quantization, Runtime and Hardware Together Read More »

Perplexity Ships Portable Computer on NVIDIA DGX Spark: Local Harness, OS-Enforced Sandbox, and Zero Per-Token Cost for Local Steps

Perplexity has released Portable Computer, a local-first build of its agentic Computer platform that runs the agent harness, orchestrator, planner, tool router and post-trained models directly on NVIDIA DGX Spark. The local model, inference engine, tool sandbox and app connectors ship as one packaged system, every task begins on the device, and work handled by

Perplexity Ships Portable Computer on NVIDIA DGX Spark: Local Harness, OS-Enforced Sandbox, and Zero Per-Token Cost for Local Steps Read More »