Software engineering

Auto Added by WPeMatico

Someone Fine-Tuned OpenBMB’s MiniCPM5-1B on Claude Fable 5 Traces to Ship a 657MB Local Thinking Model

A community developer, GnLOLot, has published a 1B model that runs fully on local hardware. The model is MiniCPM5-1B-Claude-Opus-Fable5-Thinking, with GGUF builds for llama.cpp-compatible runtimes. It needs no API key and makes no cloud calls. The Proposed Model The model is built on openbmb/MiniCPM5-1B. That base is a real, documented release from OpenBMB. It is […]
Someone Fine-Tuned OpenBMB’s MiniCPM5-1B on Claude Fable 5 Traces to Ship a 657MB Local Thinking Model Read More »

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the Database Before Writing a Query

Most text-to-SQL systems treat the task as translation. Feyn AI (YC-backed startup) reframes it around inspection. The Feyn team has released SQRL, a family of models that turn natural language questions into SQL. Instead of generating a query immediately, SQRL can inspect the database first. This lets it resolve ambiguity and write only queries the

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the Database Before Writing a Query Read More »

Alibaba Previews Qwen3.8-Max, a 2.4 Trillion-Parameter Multimodal Model, Days After Moonshot’s Kimi K3 Open-Weight Launch

On July 19, Alibaba’s Qwen team previewed Qwen3.8-Max-Preview, the next flagship in the Qwen family. The research team describes it as a 2.4 trillion-parameter model, ‘second only to Fable 5’ among the systems it benchmarked. The preview is live now. The benchmark table, model card, and license are not. The July 19th 2026 announcement landed

Alibaba Previews Qwen3.8-Max, a 2.4 Trillion-Parameter Multimodal Model, Days After Moonshot’s Kimi K3 Open-Weight Launch Read More »

🖼

Google Cloud’s Always-On Memory Agent Replaces RAG and Embeddings With Continuous LLM Consolidation on Gemini 3.1 Flash-Lite

Most AI agents forget. They process a request, answer it, then drop the context. Google Cloud’s generative-ai repository now ships a sample that tackles this directly. It is the Always-On Memory Agent, a reference implementation that treats memory as a running process. Always-On Memory Agent Fundamentally, the project is a lightweight background agent that never

Google Cloud’s Always-On Memory Agent Replaces RAG and Embeddings With Continuous LLM Consolidation on Gemini 3.1 Flash-Lite Read More »

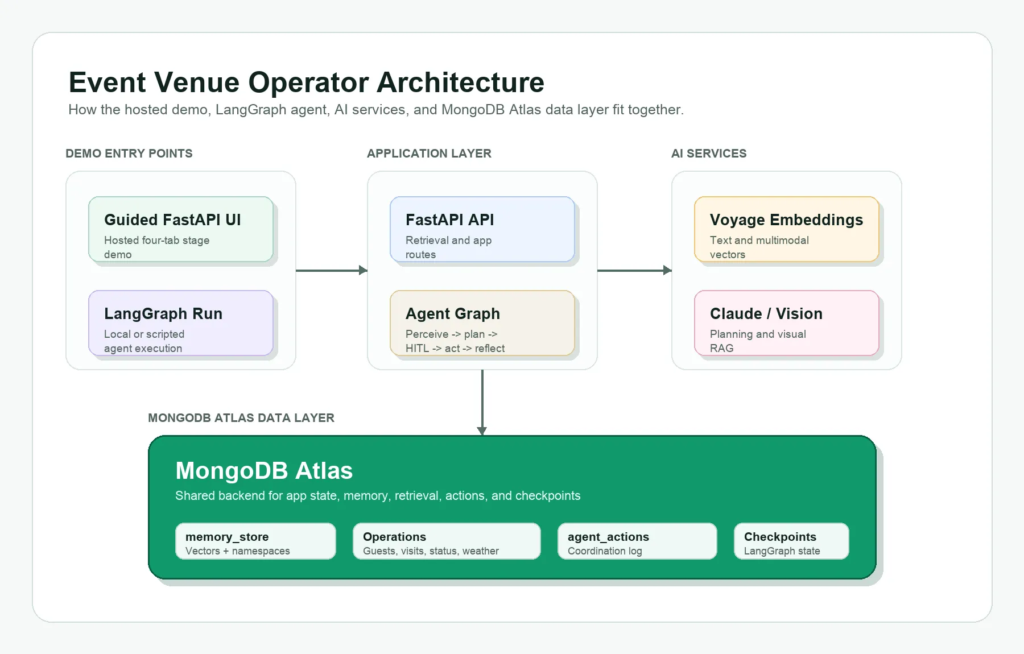
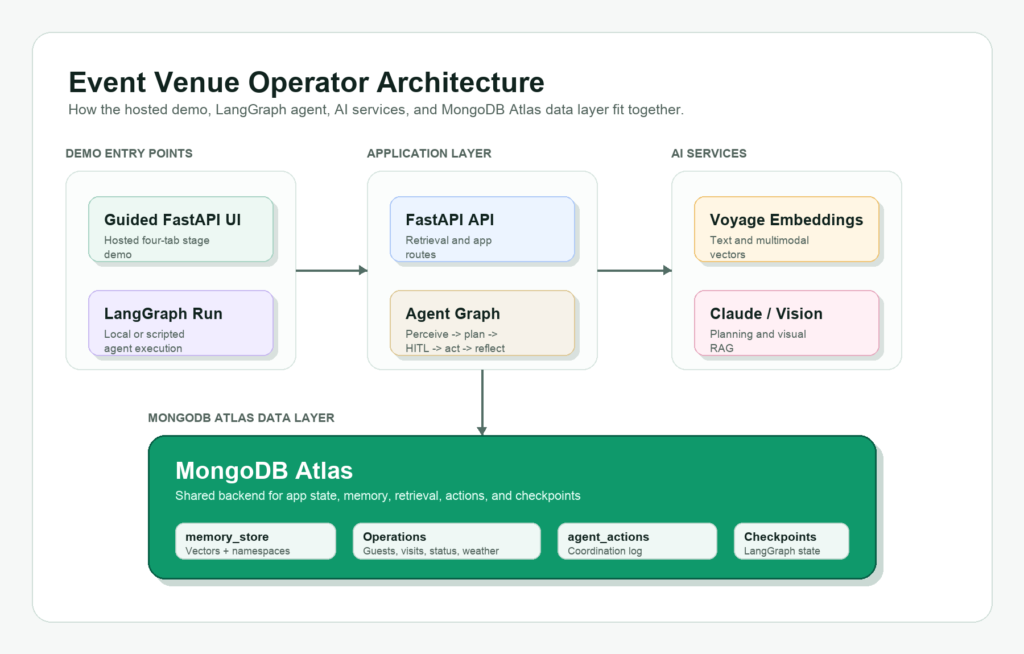
Build an Agentic Event Venue Operator with MongoDB Atlas, Voyage, and LangGraph

Introduction This tutorial starts where most agent demos stop: giving the agent persistent memory, operational context, and a place to write back what happened. An event operator does not just need an agent that can summarize a weather report or generate a generic plan. The operator needs an agent that can remember what happened at

Build an Agentic Event Venue Operator with MongoDB Atlas, Voyage, and LangGraph Read More »

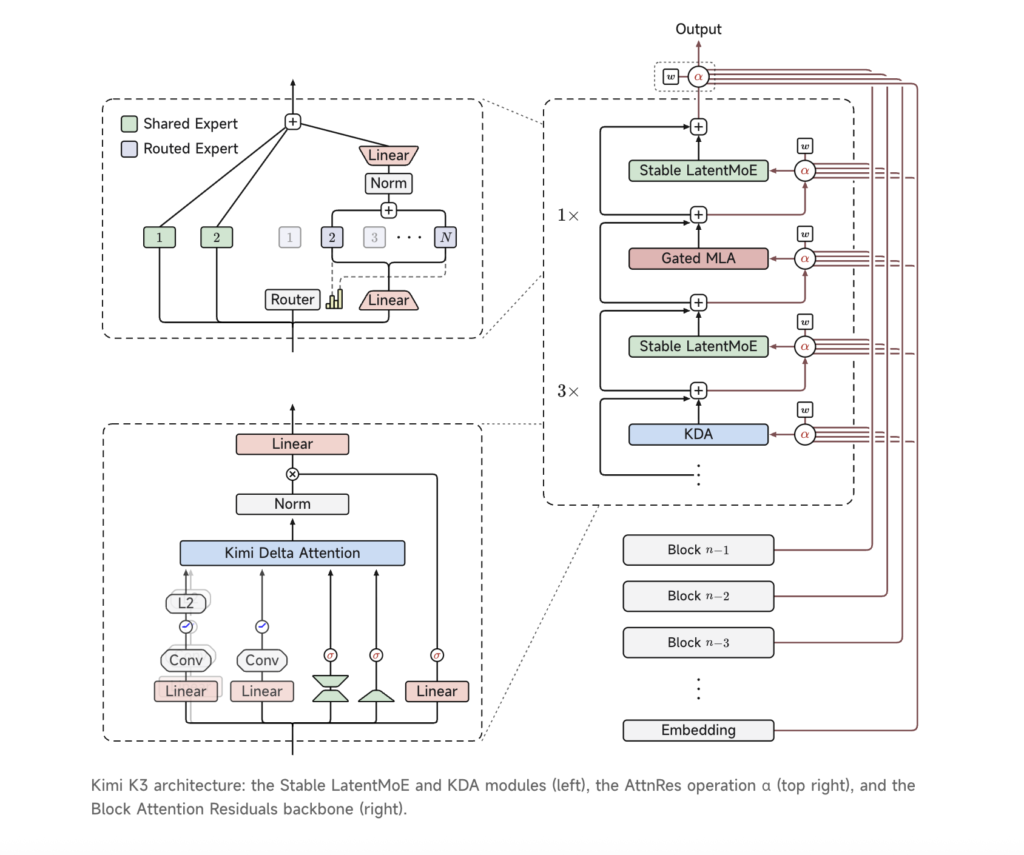
Moonshot AI Releases Kimi K3: A 2.8 Trillion Parameter Open MoE Model With Kimi Delta Attention and 1M Context

Moonshot AI just released Kimi K3. It is a 2.8-trillion-parameter model with native vision and a 1-million-token context window. Moonshot calls it the world’s first open 3T-class model. What is Kimi K3? Kimi K3 is a sparse Mixture-of-Experts (MoE) model built on two architectural updates. Those are Kimi Delta Attention (KDA) and Attention Residuals (AttnRes).

Moonshot AI Releases Kimi K3: A 2.8 Trillion Parameter Open MoE Model With Kimi Delta Attention and 1M Context Read More »

OpenAI Details GPT-Red: An Internal Automated Red-Teaming Model That Beat Human Red-Teamers 84% To 13% On Prompt Injection

This week, OpenAI published details of GPT-Red, an internal-only automated red-teaming model. Its job is to attack OpenAI’s own models and find prompt injection vulnerabilities. OpenAI gives two reasons. Human red-teaming is time-intensive and does not scale. Commonly used robustness evaluations are already saturated by its latest models. Meanwhile, the attack surface grows. Agents read

OpenAI Details GPT-Red: An Internal Automated Red-Teaming Model That Beat Human Red-Teamers 84% To 13% On Prompt Injection Read More »

SpaceXAI Open-Sources Grok Build: The Rust Agent Harness, TUI, and Tool Layer Behind Its Coding CLI

SpaceXAI has open-sourced Grok Build, the terminal-based AI coding agent behind its grok CLI. The source landed on GitHub today. The release covers the agent harness, TUI, CLI shell, and developer tooling under the Apache 2.0 license What is Grok Build? A harness is the scaffolding around a model. It assembles context, calls the model,

SpaceXAI Open-Sources Grok Build: The Rust Agent Harness, TUI, and Tool Layer Behind Its Coding CLI Read More »

Google Releases LiteRT.js: A JavaScript Binding of LiteRT That Runs .tflite Models in Browsers via WebGPU

Google released LiteRT.js, a JavaScript binding of LiteRT. LiteRT is Google’s on-device inference library, previously called TensorFlow Lite. LiteRT.js runs .tflite models directly inside the browser. Because inference stays local, Google cites enhanced user privacy, zero server costs, and ultra-low latency. What is LiteRT.js? It is not a new model format. Rather, Google compiled its

Google Releases LiteRT.js: A JavaScript Binding of LiteRT That Runs .tflite Models in Browsers via WebGPU Read More »