
Language Model

Auto Added by WPeMatico

DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse

Long-horizon agents have turned LLM serving into an input-heavy workload. Repeated prefills and million-token contexts leave KV caches that strain HBM, SSD capacity, and bandwidth. DeepSeek AI built its newest release around that exact bottleneck. DeepSeek-V4.1-Flash is a multimodal Mixture-of-Experts model with 552B backbone parameters, 196B additional Engram parameters, and a 1M-token context window. It […]
DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse Read More »

LandingAI Releases Agentic Document Extraction Gen2 with DPT-3 Pro and DPT-3 Verity

LandingAI has shipped Agentic Document Extraction (ADE) Gen2, a rebuild of its document intelligence stack around a new model family called DPT-3. Gen1 treated a document as a flat list of chunks. Gen2 treats it as a tree, prices it by the characters it returns rather than by the page, and grounds every answer back

LandingAI Releases Agentic Document Extraction Gen2 with DPT-3 Pro and DPT-3 Verity Read More »

Google DeepMind Releases AlphaGenome Atlas With Precomputed Molecular Effect Predictions and AVI Scores for 9 Billion Human DNA Variants

Google DeepMind has released AlphaGenome Atlas, a catalogue of precomputed predictions for the molecular effects of every possible single-nucleotide variant in the human genome. That is roughly 9 billion single-letter changes. The release also introduces the AlphaGenome Variant Impact (AVI) score, a single number that ranks variants by predicted impact, plus per-variant feature attributions and

Google DeepMind Releases AlphaGenome Atlas With Precomputed Molecular Effect Predictions and AVI Scores for 9 Billion Human DNA Variants Read More »

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page

Last week, Reducto announced r-1. It is the first model in a new parsing family built on a rewritten architecture, and it replaces the company’s multi stage agentic OCR with one full page pass. Reducto says r-1 is more accurate than its most powerful legacy agentic models, faster, and up to 6x cheaper. Is it

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page Read More »

OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34 Benchmarks and Built to Run On Device

OpenBMB has released MiniCPM5-2B, the second checkpoint in the MiniCPM5 series and the follow-up to MiniCPM5-1B. It is a dense causal language model with 2,516,756,480 parameters, of which 1,981,982,720 sit outside the embeddings. It uses 42 layers, grouped-query attention with 16 query heads and 2 key/value heads, and a native context window of 131,072 tokens.

OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34 Benchmarks and Built to Run On Device Read More »

Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot Manipulation Tasks and 50,129 Trajectories

Robot manipulation datasets have grown far slower than the models trained on them, mostly because collection stays closed and centralized. Expert operators gather demonstrations on lab hardware, process them offline, and ship a fixed benchmark that never grows again. A research team from Axis Robotics, UC Berkeley, Georgia Tech, NTU… is proposing a different shape

Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot Manipulation Tasks and 50,129 Trajectories Read More »

IFM Releases K2 Horizon: Six Apache 2.0 Models From 0.9B to 375B

Most open model launches release one checkpoint and a benchmark table. The Institute of Foundation Models (IFM) released something wider last week. IFM is the frontier lab launched by MBZUAI in May 2025. K2 Horizon is a fleet of six models: 375B-A23B, 36B-A4B, 32B, 7B, 3.7B and 0.9B. Shipping alongside them are the pre-training corpus,

IFM Releases K2 Horizon: Six Apache 2.0 Models From 0.9B to 375B Read More »

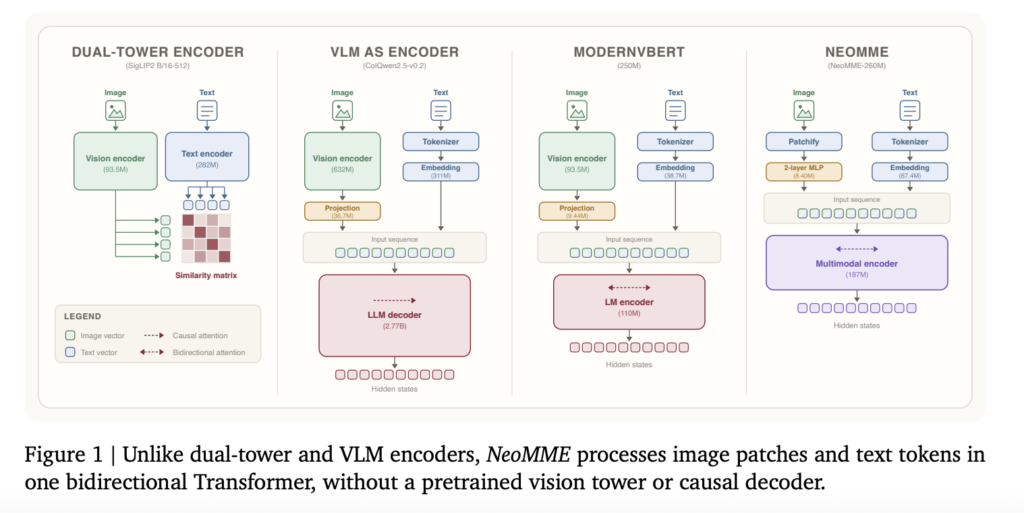
H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder

Most visual document retrievers in production today are hand-me-downs. ColPali and the models that followed it take a generative vision-language model and repurpose it as an encoder. The result still carries a separately pretrained vision tower and a causal decoder that never generates a token. That is parameter and compute overhead for a task that

H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder Read More »

Meta FAIR Introduces AI Research Preference Models (RPMs): Ranking ML Experiments Before Spending GPU Hours

AI research agents can already propose, implement and score their own machine learning experiments. Idea generation is cheap; verification is not. Training one candidate can consume hours to days of GPU time, so an agent proposes far more candidates than it can afford to run. Which ones get run is the real lever on research

Meta FAIR Introduces AI Research Preference Models (RPMs): Ranking ML Experiments Before Spending GPU Hours Read More »

Google Launches Agentic Video Understanding for Gemini Flash Models, Cutting Video Tokens by Up to 88%

Video has been the most expensive modality to reason over. A Gemini model handed a 90-minute lecture has, until now, ingested the whole thing at a fixed one frame per second, whether the question was ‘summarize this’ or ‘what time does the speaker switch to the pricing slide?’ That single-pass design forces a bad trade:

Google Launches Agentic Video Understanding for Gemini Flash Models, Cutting Video Tokens by Up to 88% Read More »