AI Interview Series #5: Prompt Caching
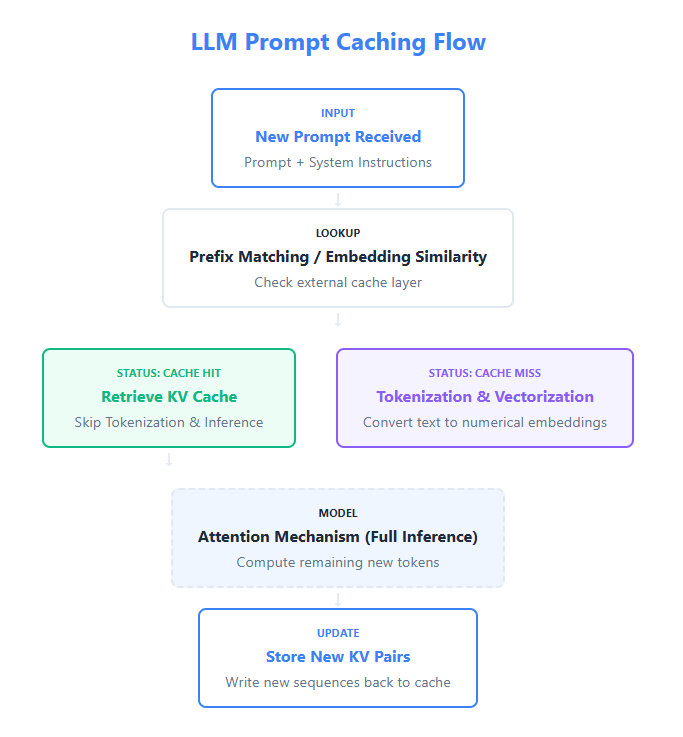
Question: Imagine your company’s LLM API costs suddenly doubled last month. A deeper analysis shows that while user inputs look different at a text level, many of them are semantically similar. As an engineer, how would you identify and reduce this redundancy without impacting response quality? What is Prompt Caching? Prompt caching is an optimization […]