Computer vision

Auto Added by WPeMatico

LingBot-Map Tutorial: GPU-Aware Inference and Point Cloud Export

In this tutorial, we implement an end-to-end streaming 3D reconstruction pipeline with LingBot-Map. We begin by configuring the input source, reconstruction settings, checkpoint selection, and output controls, then probe the available GPU and automatically tune frame limits, camera iterations, scale frames, and KV-cache parameters according to the detected VRAM. We install the repository and its

LingBot-Map Tutorial: GPU-Aware Inference and Point Cloud Export Read More »
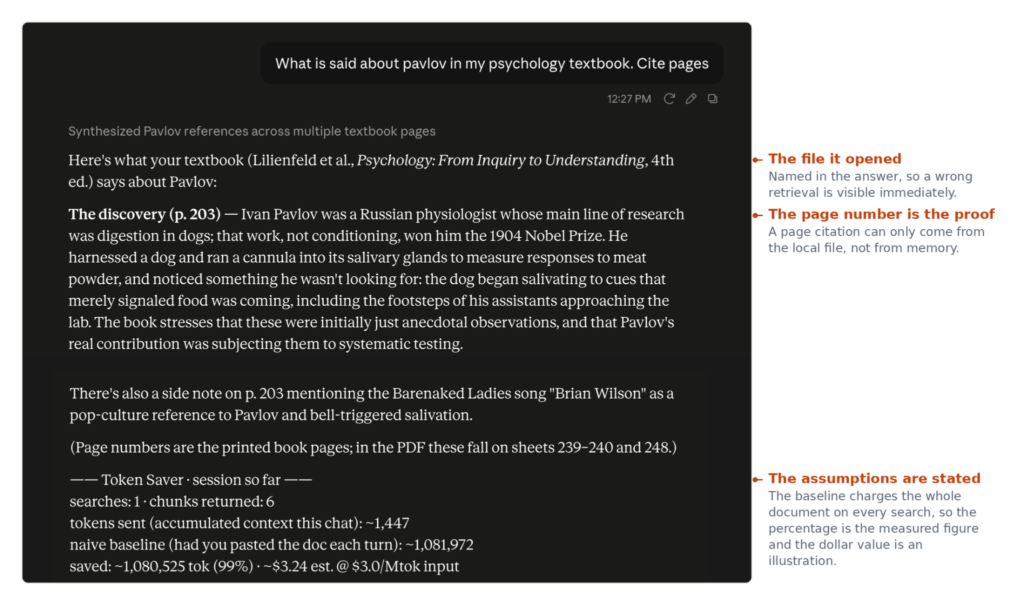
Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG to Cut Claude PDF Token Costs 90-99%

AI developers, researchers, and professionals frequently hit a frustrating wall when analyzing large documents with LLMs: the hidden, compounding cost of context windows. Pasting a 200-page PDF into a chat isn’t a one-time charge. Because the conversation history is re-sent to the model on every single turn, that massive document is paid for again with

Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG to Cut Claude PDF Token Costs 90-99% Read More »

Banner for the AI & Big Data Expo event series.

Guardoc Health processes clinical documentation using Amazon Nova models

Guardoc Health says it processes over one million clinical documents daily using Amazon Nova models through Bedrock. Bringing AI into clinical documentation comes down to a specific kind of risk calculation. Get it wrong and the errors compound into denied Medicare claims under the Patient-Driven Payment Model, audit fines, litigation exposure, and in the worst

Guardoc Health processes clinical documentation using Amazon Nova models Read More »

Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for Image, Video, Audio and Robot Action Prediction

Black Forest Labs (BFL) has released FLUX 3, a multimodal foundation model that learns from images, videos and audio inside a single architecture. It is also the first FLUX model to ship video, audio and action prediction from one set of weights. The Black Forest Labs (BFL) research team argues that no single modality gives

Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for Image, Video, Audio and Robot Action Prediction Read More »

Induction Labs Photon-1 Simulates Desktops, Plays Checkers, and Models Billiard Physics From One Pretraining Run

Most agents that learn from video need to know what action produced each frame. Induction Labs is arguing that this requirement is the bottleneck. Last week, they released imagination models, a foundation model architecture that pretrains on raw video with no action labels at all. Their test system is Photon-1, a sparse 106B-A5B mixture-of-experts (MoE)

Induction Labs Photon-1 Simulates Desktops, Plays Checkers, and Models Billiard Physics From One Pretraining Run Read More »

NVIDIA Released DeepStream 9.1: Bringing Agentic AI to Vision AI With 13 Skills and Multi-View 3D Tracking

NVIDIA just released DeepStream 9.1. The update targets a persistent problem in video analytics. Tracking one object across many cameras traditionally requires manual camera calibration and complicated calculations. DeepStream 9.1 addresses this with two additions: Multi-View 3D Tracking (MV3DT) and AutoMagicCalib (AMC). Both ship as agentic skills for coding agents. As a result, developers move

NVIDIA Released DeepStream 9.1: Bringing Agentic AI to Vision AI With 13 Skills and Multi-View 3D Tracking Read More »

How to Measure Video Similarity: 6 Techniques I Tested (and the One I Shipped) 

Two short clips. One question: how alike do they look? Sounds trivial, it isn’t, and I learned that the slow way.  My setup: one reference clip, eight others to rank against it, all waterfalls (more on why in a second). I figured this was an afternoon job, grab a model, compute a number, move on.

How to Measure Video Similarity: 6 Techniques I Tested (and the One I Shipped)  Read More »

✅

NVIDIA’s Cosmos-Framework Tutorial: Designing a Colab-Friendly Miniature of Cosmos 3 World Models with Omnimodal Mixture-of-Transformers

In this tutorial, we explore NVIDIA’s cosmos-framework from a practical Colab-friendly angle while staying honest about the hardware limits of running real Cosmos 3 checkpoints. We begin by checking the current runtime, GPU capabilities, CUDA availability, memory, and disk space to understand why full Cosmos 3 inference is not realistic on standard Colab hardware. Instead

NVIDIA’s Cosmos-Framework Tutorial: Designing a Colab-Friendly Miniature of Cosmos 3 World Models with Omnimodal Mixture-of-Transformers Read More »

Modern VLMs Explained: How GPT-4o, Gemini, Claude Vision, and Qwen-VL Work 

Vision Language Models, or VLMs, are AI models that can understand both visual content and language. While earlier models like CLIP and BLIP connected images with text, modern VLMs can analyze images, read documents, interpret charts, answer visual questions, and support multimodal conversations. Models like GPT-4o, Gemini, Claude Vision, and Qwen-VL are making visual AI

Modern VLMs Explained: How GPT-4o, Gemini, Claude Vision, and Qwen-VL Work  Read More »