
Applications

Auto Added by WPeMatico

Google AI Releases Gemini Omni 1.1 Flash: 40-Second Scene Extension, First/Last Frame Control, and 4K Upscaling

Google has released Gemini Omni 1.1 Flash (gemini-omni-1.1-flash), a production update to its native multimodal video generation and editing model. The release moves Omni from a capable generator to a directable one: scene extension now reads up to 10 seconds of prior context instead of a single final frame, first and last frames can be […]
Google AI Releases Gemini Omni 1.1 Flash: 40-Second Scene Extension, First/Last Frame Control, and 4K Upscaling Read More »

Hugging Face Unveils Microduck: A $399 Open-Source 25 cm Biped You Train with Reinforcement Learning

Most robotics launches ask you to trust a demo video. Pollen Robotics, the Bordeaux robotics team at Hugging Face, is instead shipping the training loop. This week it opened pre-orders for Microduck, a 25 cm bipedal robot in which every movement — walking, sitting, kicking, roller-skating, standing back up after a fall — is a

Hugging Face Unveils Microduck: A $399 Open-Source 25 cm Biped You Train with Reinforcement Learning Read More »

GLM-5.3-Flash vs Qwen3.8-Flash-Next: Two Chinese AI Labs Independently Converge on the Same Model Architecture

Two frontier open-weight models shipped within a day of each other this week. Z.ai released GLM-5.3-Flash, a 320B-parameter multimodal MoE model with 18B active parameters. Alibaba’s Qwen team released Qwen3.8-Flash-Next, a 125B model with 6B active parameters that previews the Qwen4 architecture. The two teams designed these systems independently. Yet their configs read like near-copies

GLM-5.3-Flash vs Qwen3.8-Flash-Next: Two Chinese AI Labs Independently Converge on the Same Model Architecture Read More »

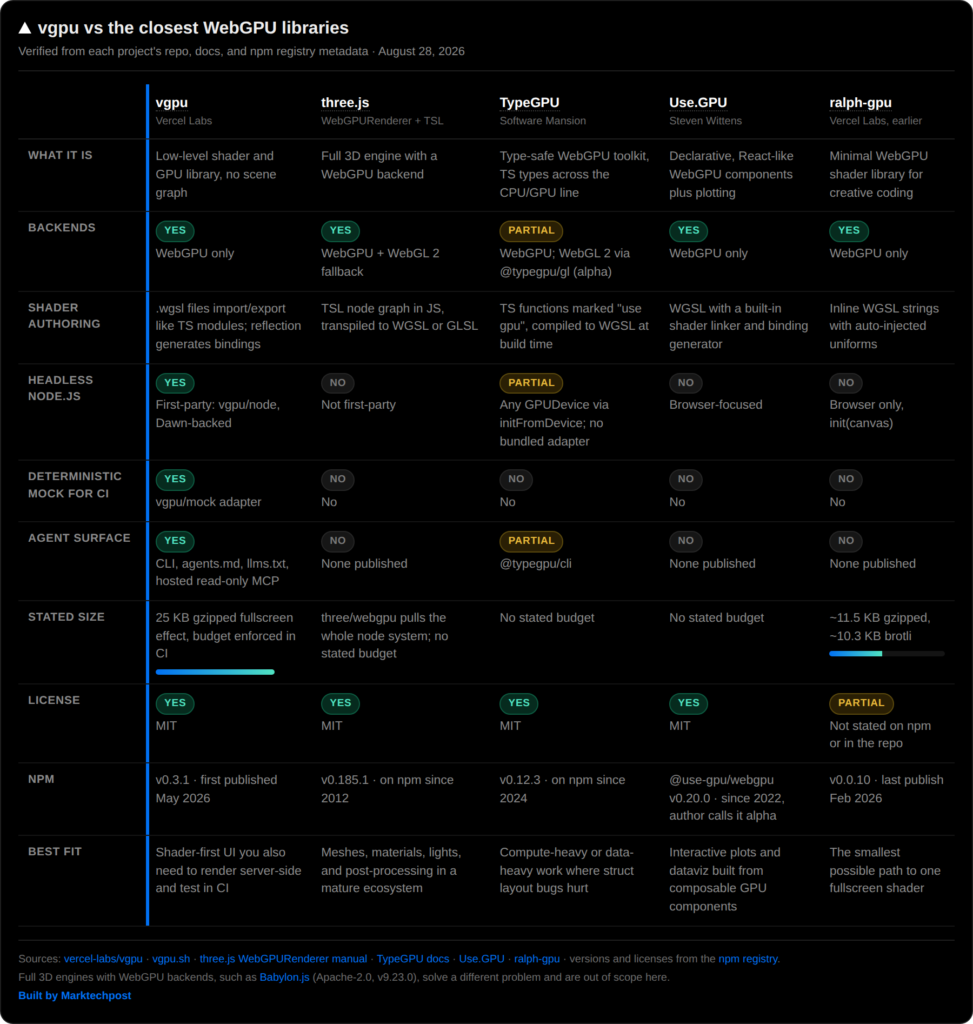
Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent Shaders

Shaders are still the hardest thing to ship on a normal web team. WebGPU gives you the hardware, then hands you adapters, bind group layouts, and pipeline descriptors before a single pixel moves. Vercel spent that cost internally building the shaders on vercel.com, and has now open-sourced the result. vgpu is a TypeScript library that

Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent Shaders Read More »

Google AI Releases Gemini 3.5 Transcribe: A Speech-to-Text Model Reporting 2.6% Average WER Across 85+ Languages

Google has released Gemini 3.5 Transcribe, a speech-to-text model for real-time voice interfaces and recorded audio. It ships as two endpoints, not one. gemini-3.5-transcribe handles pre-recorded files through the Interactions API. gemini-3.5-transcribe-live handles bidirectional streaming through the Live API. Google reports average word error rates of 4.0% streaming and 2.6% non-streaming, as measured by Artificial

Google AI Releases Gemini 3.5 Transcribe: A Speech-to-Text Model Reporting 2.6% Average WER Across 85+ Languages Read More »

Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown

Cohere has released Parse (parse-v5.0), a document parsing model aimed at high-volume enterprise ingestion. It is a 2.3B-parameter vision language model with an 8,192-token context window and a ~4.6GB footprint, built on Cohere Labs’ North-Micro-Vision-Instruct architecture. Parse takes a PDF, PPT or JPEG page as a base64-encoded data URI and returns Markdown containing text in

Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown Read More »

From In-Silico to Wet-Lab: Evaluating AI Protein Design Performance

In this tutorial, we use Anthropic’s claude-protein-binder-design dataset, which contains 1,440 AI-designed miniprotein binders tested against 16 targets. Because the release includes both computational predictions and real wet-lab results from two independent labs, we can go beyond simply studying the designs. We evaluate how well structure predictors identify successful binders, whether combining predictions improves performance,

From In-Silico to Wet-Lab: Evaluating AI Protein Design Performance Read More »

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous Glucose Monitoring

Google Research and UNSW Sydney have released GlucoFM, a self-supervised foundation model for continuous glucose monitoring. Its core move is a split. Existing CGM models — CGMformer, GluFormer, CGM-JEPA — encode a glucose trace as one entangled sequence. GlucoFM decomposes it into a slow physiological “state” stream and a transient “event” stream, keeps the observation

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous Glucose Monitoring Read More »

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token Context

Z.ai has released GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series and the cheapest capable coding model the lab has shipped. It is a mixture-of-experts model with 320B total parameters and 18B active per token, a 1,048,576-token context window, and image and video input — released under an MIT license with weights on

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token Context Read More »

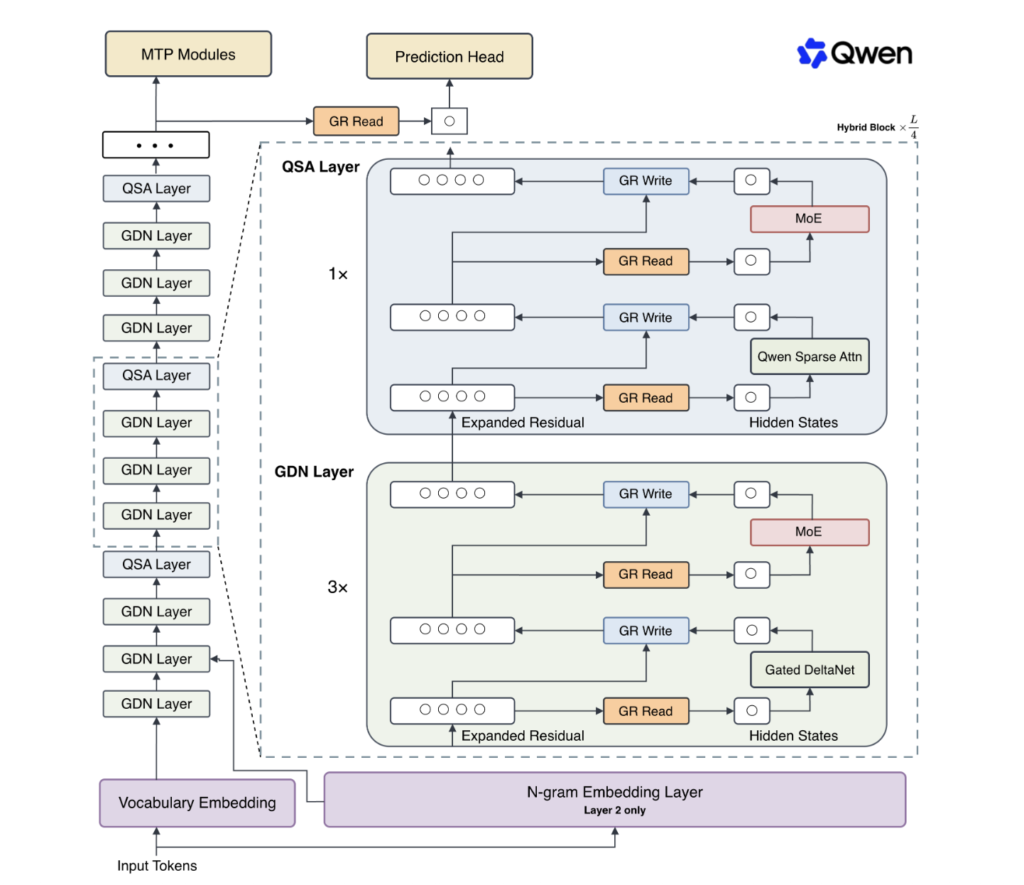
Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B Active Parameters Previewing the Qwen4 Architecture

Alibaba’s Qwen team has released Qwen3.8-Flash-Next, an open-weight multimodal Mixture-of-Experts model built for cost per token. The checkpoint pairs a 125B backbone with a 51B N-gram embedding table and a 4B multi-token prediction module. Only 6B parameters activate per token. The team positions it as an early preview of the architecture that will underpin Qwen4,

Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B Active Parameters Previewing the Qwen4 Architecture Read More »