
Applications

Auto Added by WPeMatico

Perplexity Releases Hybrid Compute on Mac: Cloud Agents Orchestrate Down to a Local Model, Gated On Device

Agentic assistants have a structural problem: the context that makes them useful — deal documents, privileged files, client records — is exactly the context users cannot send to a cloud endpoint. This week, Perplexity shipped its answer for Mac. Hybrid compute splits a single Perplexity Computer task between frontier models in the cloud and a […]
Perplexity Releases Hybrid Compute on Mac: Cloud Agents Orchestrate Down to a Local Model, Gated On Device Read More »

Anthropic Releases Claude Fable 5.1 and Claude Mythos 5.1: 52.6% on Terminal-Bench-Science and 75% Cheaper Cache Reads

Anthropic has released Claude Fable 5.1 and Claude Mythos 5.1, three months after the Fable 5 line shipped in June 2026. The two are the same underlying model behind different safeguard layers. Fable 5.1 is generally available as claude-fable-5-1; Mythos 5.1 stays restricted to vetted organizations. Both carry a 1M token context window and 128K

Anthropic Releases Claude Fable 5.1 and Claude Mythos 5.1: 52.6% on Terminal-Bench-Science and 75% Cheaper Cache Reads Read More »

Researchers from Princeton, Ant Group and Stanford Introduce AQuA: A Two-Part Agentic Framework for Autonomous Factor Discovery and Model Development in Quantitative Finance

Quantitative research agents that write their own experiments can corrupt the evidence they later learn from. A leaky feature that scores well gets stored as a successful precedent and propagated through later iterations. Prompt-level instructions and reviewer agents do not close this, because author and reviewer share the same blind spots. A team of researchers

Researchers from Princeton, Ant Group and Stanford Introduce AQuA: A Two-Part Agentic Framework for Autonomous Factor Discovery and Model Development in Quantitative Finance Read More »

Gradium AI Releases New Default TTS Model: 81.0% Hard-Case Pass Rate at 216 ms Time-to-First-Audio

Voice agents fail on exactly the parts of a call that matter most: the order number, the callback digits, the email address the caller has to write down. Gradium AI has released a new text-to-speech model and made it the default across its API and Studio. The company reports an 81.0% human-rated pass rate on

Gradium AI Releases New Default TTS Model: 81.0% Hard-Case Pass Rate at 216 ms Time-to-First-Audio Read More »

Keenable AI Open-Sources NEEDLE: A Live Search Benchmark That Rebuilds Its Query Set Every Hour

How do you benchmark a web search API when the thing being tested can read the answer key? A search agent has a fetch tool. If the gold labels sit in a public dataset, the agent can download them mid-evaluation and skip retrieval entirely. A similar problem arises when the answers are already encoded in

Keenable AI Open-Sources NEEDLE: A Live Search Benchmark That Rebuilds Its Query Set Every Hour Read More »

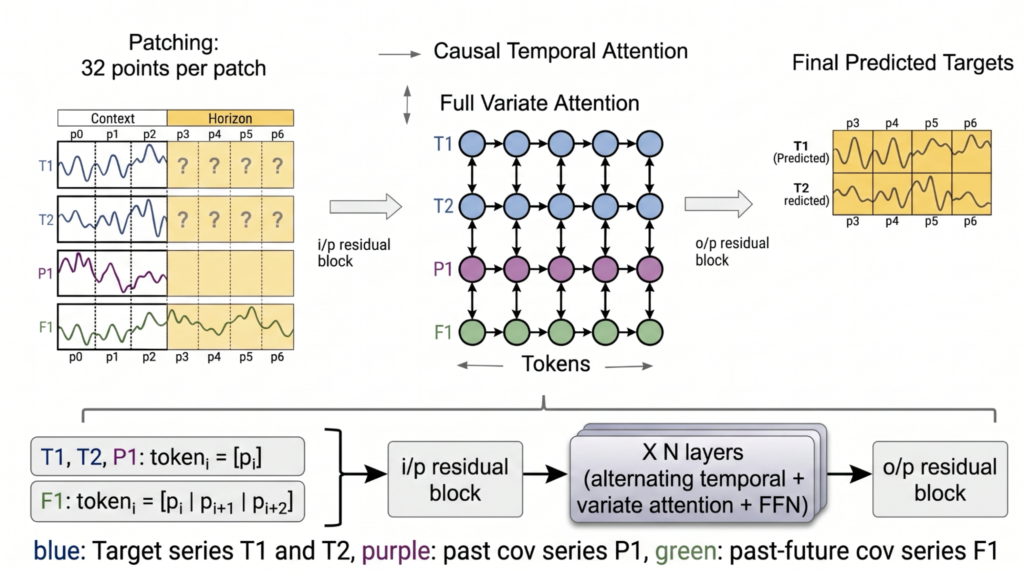
Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For Multivariate Time Series Forecasting

Google Research has released TimesFM-3, a 330 million parameter time series foundation model that forecasts multiple related series in a single forward pass. Every TimesFM checkpoint through 2.5 was univariate: one series, its own history, nothing else. TimesFM-3 is pretrained natively for multivariate forecasting on more than 1 trillion time points, and accepts multiple targets,

Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For Multivariate Time Series Forecasting Read More »

OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI Startup, and One Trust Boundary Per Gateway

The OpenClaw team has just released OpenClaw 2.0. The team shipped nothing for nearly seven weeks, after 106 releases in the previous 230 days. The update rewrites installation and rebuilds the browser Control UI. It also moves sessions and transcripts into SQLite and adds shared cloud sessions. Is it deployable? Yes for single-operator and single-team

OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI Startup, and One Trust Boundary Per Gateway Read More »

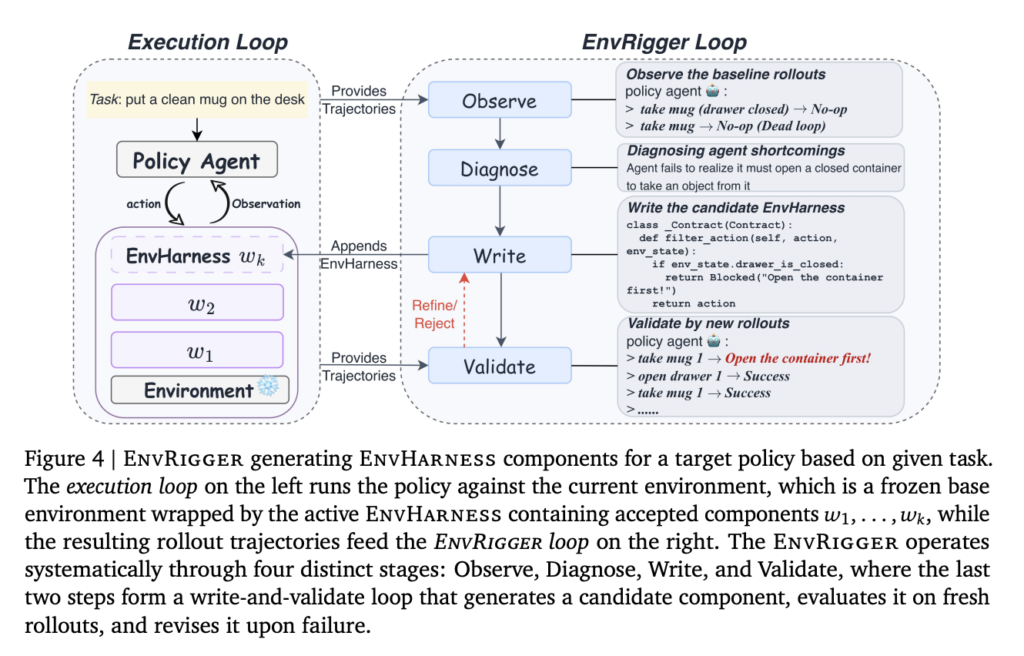
Google AI Introduces EnvHarness: A Programmable Layer That Turns Static Agent Environments Into Adaptive Training Worlds

A team of researchers from Google Cloud AI Research, Washington University in St. Louis and UNC Chapel Hill has released EnvHarness, a programmable layer that turns a static agent benchmark into one that adapts to the policy training on it. LLM agents now learn less from curated text and more from interactive environments, but those

Google AI Introduces EnvHarness: A Programmable Layer That Turns Static Agent Environments Into Adaptive Training Worlds Read More »

Anthropic Opens a Research Preview of the Model Hardware Standard (MHS): A Shared Specification for AI Agents to Safely Operate Physical Devices

Anthropic has opened a research preview of the Model Hardware Standard (MHS), a shared specification that lets AI agents discover and operate physical devices. The problem it targets is plumbing. A lab bench or factory cell is assembled from vendors that never planned to interoperate, so every instrument ships its own interface and specialists hand-write

Anthropic Opens a Research Preview of the Model Hardware Standard (MHS): A Shared Specification for AI Agents to Safely Operate Physical Devices Read More »

Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable MuJoCo Physics Programs

MirroS released Code-as-World: a paradigm that represents physical worlds through executable world representations. The argument is narrow and testable: pixels are evidence of a physical scene, not its ontology. A video model can predict plausible frames without ever representing mass, contact, or gravity. So instead of pixels, latents, or captions, Code-as-World represents a scene as

Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable MuJoCo Physics Programs Read More »