Tutorials

Auto Added by WPeMatico

Research-Grade EdgeBench Analysis: AI Agent Benchmarking, Leaderboard Analytics, Scaling Laws, and Evaluation Metrics

In this tutorial, we explore EdgeBench as a practical benchmark for evaluating advanced AI agents across diverse task categories, runtime environments, and interaction-time budgets. We begin by downloading the dataset snapshot from Hugging Face, parsing the released task specifications, and examining the benchmark taxonomy, execution settings, internet requirements, judging logic, and scoring metadata. We then

Research-Grade EdgeBench Analysis: AI Agent Benchmarking, Leaderboard Analytics, Scaling Laws, and Evaluation Metrics Read More »

✅

Validating Distributed LLM Serving Benchmarks with NVIDIA srt-slurm, SLURM Recipes, Parameter Sweeps, and Pareto Analysis

In this tutorial, we explore NVIDIA’s srt-slurm framework and learn how we use srtctl to convert declarative YAML configurations into reproducible SLURM benchmark workflows for distributed LLM serving. We set up the project in Google Colab, inspect its internal architecture, define a cluster configuration, dry-run built-in and custom recipes, and model a disaggregated prefill-and-decode deployment

Validating Distributed LLM Serving Benchmarks with NVIDIA srt-slurm, SLURM Recipes, Parameter Sweeps, and Pareto Analysis Read More »

Fine-Tuning Qwen3 with LoRA Using NVIDIA NeMo AutoModel: A Complete Single-GPU Google Colab Workflow Tutorial

In this tutorial, we build an end-to-end NVIDIA NeMo AutoModel workflow in Google Colab and use a single GPU to explore the same configuration-driven training architecture that scales to distributed multi-GPU environments. We verify the available CUDA hardware and precision support, install NeMo AutoModel directly from its source repository, load an official Qwen3-0.6B LoRA fine-tuning

Fine-Tuning Qwen3 with LoRA Using NVIDIA NeMo AutoModel: A Complete Single-GPU Google Colab Workflow Tutorial Read More »

⚠

How to Build Plasmid Engineering Workbench with Circular Mapping, Restriction Analysis, Virtual Gels, and Primer Design

In this tutorial, we build a Google Colab-native plasmid workbench that recreates the core ideas of SpliceCraft inside an interactive notebook environment. Instead of relying on a terminal-based TUI, we use Biopython, NumPy, and Matplotlib to load plasmid records, normalize annotated genomic features, render circular and linear plasmid maps, compute sequence statistics, analyze restriction enzyme

How to Build Plasmid Engineering Workbench with Circular Mapping, Restriction Analysis, Virtual Gels, and Primer Design Read More »

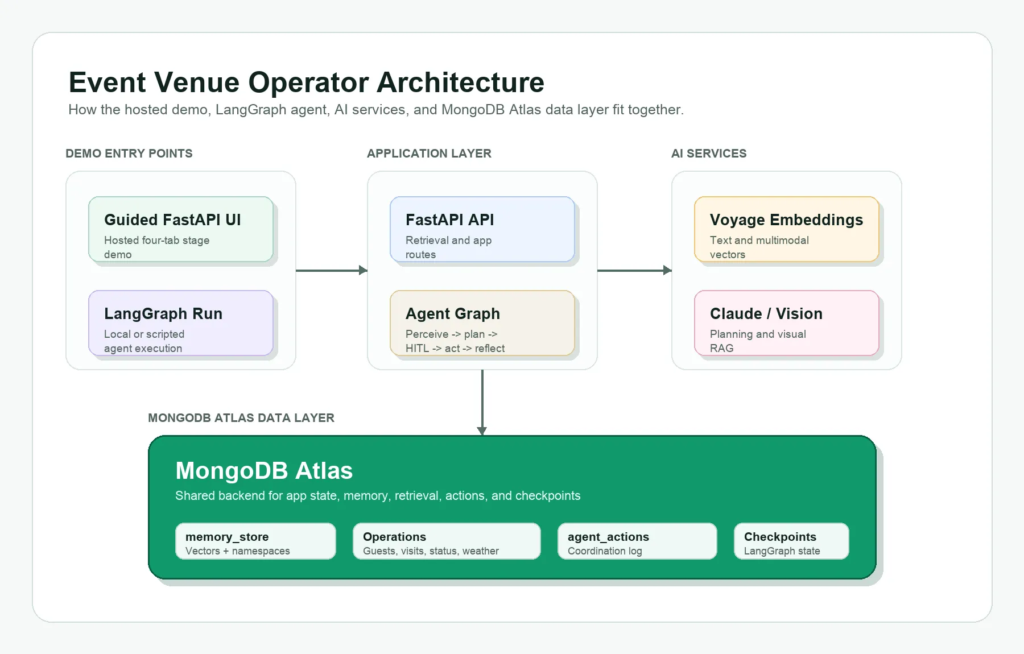
Build an Agentic Event Venue Operator with MongoDB Atlas, Voyage, and LangGraph

Introduction This tutorial starts where most agent demos stop: giving the agent persistent memory, operational context, and a place to write back what happened. An event operator does not just need an agent that can summarize a weather report or generate a generic plan. The operator needs an agent that can remember what happened at

Build an Agentic Event Venue Operator with MongoDB Atlas, Voyage, and LangGraph Read More »

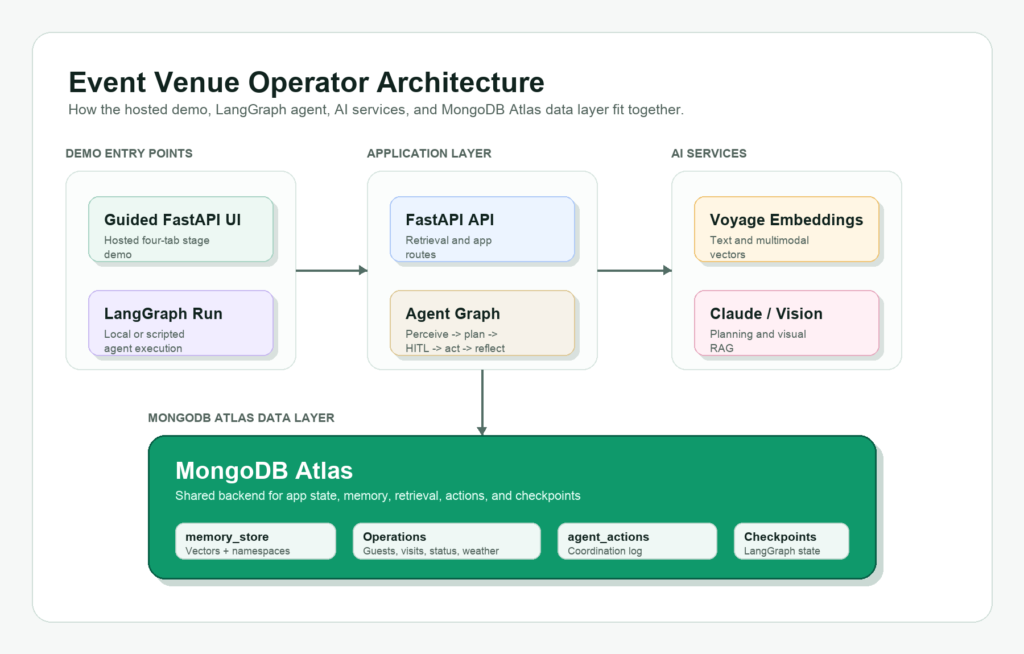
Build an Agentic Event Venue Operator with MongoDB Atlas, Voyage, and LangGraph

Introduction This tutorial starts where most agent demos stop: giving the agent persistent memory, operational context, and a place to write back what happened. An event operator does not just need an agent that can summarize a weather report or generate a generic plan. The operator needs an agent that can remember what happened at

Build an Agentic Event Venue Operator with MongoDB Atlas, Voyage, and LangGraph Read More »

📞

Patter SDK Guide to Building a Restaurant Booking Phone Agent with Dynamic Variables, Guardrails, Latency Dashboards, and Eval Checks

In this tutorial, we explore the Patter SDK by building a voice-agent workflow that simulates how an AI phone assistant behaves during real conversations. We work with a restaurant booking use case in which we define dynamic caller variables, register callable tools, apply output guardrails, simulate speech-to-text and text-to-speech behavior, and run a complete scripted

Patter SDK Guide to Building a Restaurant Booking Phone Agent with Dynamic Variables, Guardrails, Latency Dashboards, and Eval Checks Read More »

Building a Gin Config Controlled PyTorch Pipeline with Configurable MLP Variants, Cosine Scheduling, and Runtime Parameter Overrides

In this tutorial, we implement a Gin Config–controlled PyTorch experiment pipeline in which the executable training code remains stable. At the same time, the experimental degrees of freedom are moved into declarative configuration files. We construct a nonlinear spiral binary classification task, define a configurable MLP with scoped architectural variants, and expose parameters for the

Building a Gin Config Controlled PyTorch Pipeline with Configurable MLP Variants, Cosine Scheduling, and Runtime Parameter Overrides Read More »

▶

Building a VideoAgent-Style Multi-Agent System: Intent Parsing, Graph Planning, and Tool Routing for Video Editing Tasks

In this tutorial, we build a runnable reconstruction of the VideoAgent workflow, focusing on the core agentic pipeline behind video understanding, retrieval, editing, and remaking. We start by configuring a lightweight environment that works without API keys. We define an intent parser, an agent library, a tool router, a graph planner, and a textual-gradient optimizer

Building a VideoAgent-Style Multi-Agent System: Intent Parsing, Graph Planning, and Tool Routing for Video Editing Tasks Read More »

A Coding Guide to NVIDIA’s Tile-Based GPU Programming: From cuTile and Triton Kernels to Flash Attention

In this tutorial, we explore TileGym GPU programming by building a practical Colab workflow that runs across different hardware conditions. We begin by probing the available CUDA environment, checking whether NVIDIA cuTile runs directly, and falling back to Triton when standard Colab GPUs lack the required cuTile stack. Through this setup, we learn the core

A Coding Guide to NVIDIA’s Tile-Based GPU Programming: From cuTile and Triton Kernels to Flash Attention Read More »