Open Source

Auto Added by WPeMatico

Meet container: Apple’s Open-Source Swift Tool for Running Linux Containers as Lightweight VMs on Apple Silicon

Apple research team recently released the container project. It is an open-source command-line tool written in Swift. It creates and runs Linux containers as lightweight virtual machines on a Mac. The project ships under the Apache 2.0 license and targets Apple silicon. Containers are how you ship reproducible environments from a laptop to a datacenter. […]

Meet container: Apple’s Open-Source Swift Tool for Running Linux Containers as Lightweight VMs on Apple Silicon Read More »

▶

DeepReinforce Releases Ornith-1.0: An Open-Source Coding Model Family That Learns Its Own RL Scaffolds

DeepReinforce has released Ornith-1.0, an open-source model family built for agentic coding. The lineup spans four sizes, from a 9B dense model to a 397B mixture-of-experts flagship. Every checkpoint ships under the MIT license on Hugging Face. The models are post-trained on top of pretrained Gemma 4 and Qwen 3.5. Most coding agents pair a

DeepReinforce Releases Ornith-1.0: An Open-Source Coding Model Family That Learns Its Own RL Scaffolds Read More »

Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV Cache Flat for Long-Document Parsing

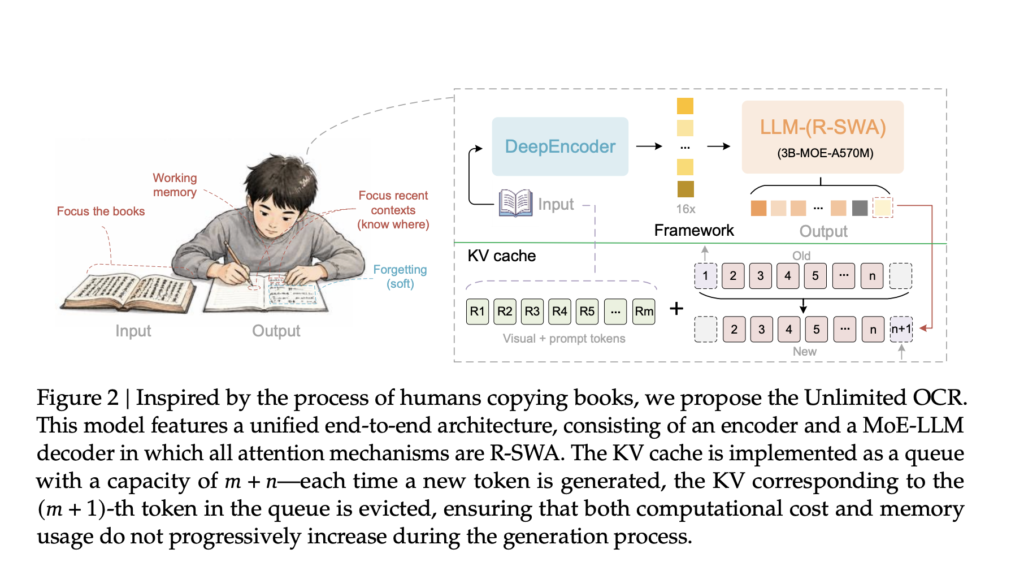
Most end-to-end OCR models slow down as output grows. Each generated token adds to the KV cache. Memory rises and generation drags. Parsing dozens of pages becomes impractical. Baidu’s Unlimited OCR addresses this directly. It swaps the decoder’s attention for a design that keeps memory constant. TL;DR Unlimited OCR is a 3B-parameter Mixture-of-Experts model, with

Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV Cache Flat for Long-Document Parsing Read More »

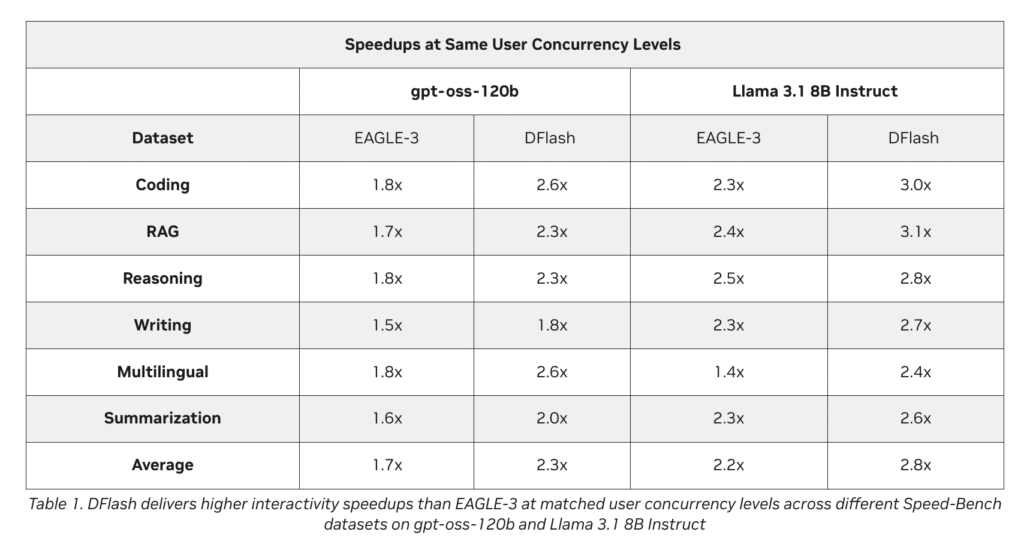
DFlash Speculative Decoding Drafts Whole Token Blocks in Parallel for Up to 15x Higher Throughput on NVIDIA Blackwell

Autoregressive large language models generate text one token at a time. Each token waits for the one before it. This serial loop leaves modern GPUs underused and keeps inference slow. The cost grows worse with long Chain-of-Thought reasoning models. Their lengthy outputs make latency the dominant part of generation. Speculative decoding is the standard fix.

DFlash Speculative Decoding Drafts Whole Token Blocks in Parallel for Up to 15x Higher Throughput on NVIDIA Blackwell Read More »

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured JSON From PDFs Using Schemas

Datalab has released lift, a 9B open-weights vision model for structured extraction. You pass it a JSON schema, and it returns a JSON object that matches. The model reads PDFs and images directly, then decodes against your schema. This is Datalab’s first model built purely for extraction. The team already ships open-source OCR tools: chandra,

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured JSON From PDFs Using Schemas Read More »

↔

Prime Intellect Releases prime-rl 0.6.0 to Train Trillion-Parameter MoE Models on Agentic RL Workloads

Prime Intellect has released prime-rl version 0.6.0. The framework targets reinforcement learning on trillion-parameter Mixture-of-Experts (MoE) models. It focuses on heavy agentic workloads, like long-horizon software-engineering tasks. The research team trained GLM-5 on SWE tasks at up to 131k sequence length. Step times stayed under five minutes. The batch size was 256 rollouts. The run

Prime Intellect Releases prime-rl 0.6.0 to Train Trillion-Parameter MoE Models on Agentic RL Workloads Read More »

MoonMath AI Open-Sources a HIP Attention Kernel for AMD MI300X That Beats AITER v3 on Every Shape and Rounding Mode

MoonMath AI team has released a bf16 forward attention kernel for AMD’s MI300X GPU. It is written in HIP, not hand-written assembly. The code is open-source under the MIT license. The MoonMath.ai team reports it beats AITER v3, AMD’s own optimized kernel, on every tested shape. Bare-metal access came from HotAisle, an AMD cloud provider.

MoonMath AI Open-Sources a HIP Attention Kernel for AMD MI300X That Beats AITER v3 on Every Shape and Rounding Mode Read More »

Cisco AI Introduces FAPO: Pipeline-Aware Prompt Optimization With Step-Level Failure Attribution and Claude Code Orchestration

Getting prompts right is still the hardest part of shipping reliable LLM applications. Small wording changes can swing accuracy by 20 percent. What works on a few examples often breaks at scale. When a multi-step pipeline returns a wrong answer, finding the failing step means inspecting intermediate outputs by hand. Cisco AI introduced FAPO to

Cisco AI Introduces FAPO: Pipeline-Aware Prompt Optimization With Step-Level Failure Attribution and Claude Code Orchestration Read More »

Nous Research Updates Hermes Agent With a Blank Slate Mode That Pins Toolsets via platform_toolsets.cli and disabled_toolsets

Nous Research has added a Blank Slate setup mode to its open-source Hermes Agent. It inverts the usual onboarding. Instead of a fully loaded default, you start with almost nothing. Hermes Agent is the self-improving agent framework from Nous Research. It runs on your own machine. The team announced the new mode on X. Blank

Nous Research Updates Hermes Agent With a Blank Slate Mode That Pins Toolsets via platform_toolsets.cli and disabled_toolsets Read More »

Yandex Open-Sources YaFF: A Zero-Copy Wire Format for Protobuf With Near-Struct Read Speed

TLDR YaFF is Yandex’s open-source zero-copy wire format for Protobuf — Apache 2.0, currently C++, v0.1.0. The .proto file stays the source of truth; only the physical memory layout changes. On Yandex’s benchmarks, the Flat Layout reads hot data ~3.8× faster than FlatBuffers, within 1.2× of a raw C++ struct. Four layouts — Fixed, Flat,

Yandex Open-Sources YaFF: A Zero-Copy Wire Format for Protobuf With Near-Struct Read Speed Read More »