OCR

Auto Added by WPeMatico

✅

Using Lift to Turn Research PDFs into Structured JSON with Controlled, Schema-Guided Field-Level Evaluation

In this tutorial, we build a complete PDF-to-structured-data extraction workflow around Lift, with a focus on controlled evaluation rather than a simple demo run. We begin by preparing a Colab-compatible GPU environment, selecting the appropriate precision mode for the available hardware, and patching model loading to ensure the Lift backend runs reliably even on constrained

Using Lift to Turn Research PDFs into Structured JSON with Controlled, Schema-Guided Field-Level Evaluation Read More »

✅

OCRmyPDF Tutorial: Convert Scanned Documents into Searchable PDF/A Files with Sidecar Text Extraction and Batch Processing

In this tutorial, we build an advanced, self-contained OCRmyPDF workflow. We start by installing the required system and Python dependencies, then create a synthetic image-only PDF for scanning so we can test OCR without relying on external files. From there, we use OCRmyPDF’s real public API to convert scanned documents into searchable PDFs, generate PDF/A

OCRmyPDF Tutorial: Convert Scanned Documents into Searchable PDF/A Files with Sidecar Text Extraction and Batch Processing Read More »

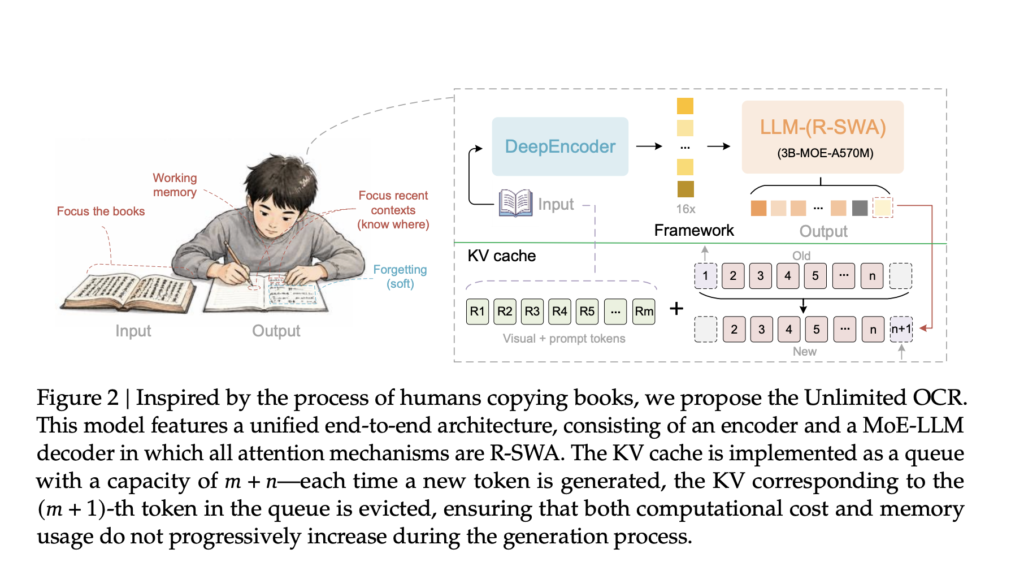
Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV Cache Flat for Long-Document Parsing

Most end-to-end OCR models slow down as output grows. Each generated token adds to the KV cache. Memory rises and generation drags. Parsing dozens of pages becomes impractical. Baidu’s Unlimited OCR addresses this directly. It swaps the decoder’s attention for a design that keeps memory constant. TL;DR Unlimited OCR is a 3B-parameter Mixture-of-Experts model, with

Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV Cache Flat for Long-Document Parsing Read More »

Mistral OCR 4 Brings Citation-Ready Structured Output to RAG, Agentic, and Enterprise Search Pipelines

Today, Mistral AI released OCR 4, its latest document-understanding model. This new release adds bounding boxes, block classification, and inline confidence scores alongside extracted text. It supports 170 languages across 10 language groups and runs in a single container for fully self-hosted deployments. OCR 4 also serves as an ingestion component for enterprise search, RAG,

Mistral OCR 4 Brings Citation-Ready Structured Output to RAG, Agentic, and Enterprise Search Pipelines Read More »

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured JSON From PDFs Using Schemas

Datalab has released lift, a 9B open-weights vision model for structured extraction. You pass it a JSON schema, and it returns a JSON object that matches. The model reads PDFs and images directly, then decodes against your schema. This is Datalab’s first model built purely for extraction. The team already ships open-source OCR tools: chandra,

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured JSON From PDFs Using Schemas Read More »

Global FMCG Brand Process 100,000+ Quality Testing

How We Helped a Global FMCG Brand Process 100,000+ Quality Documents with AI

Here’s How We Helped a Global FMCG Brand Process 100,000+ Quality Testing Documents with AI Without Losing Accuracy When a global FMCG manufacturer came to us, the problem wasn’t a lack of data. It was too much of it, trapped in the wrong format. Every batch of product that left their manufacturing facilities came with

How We Helped a Global FMCG Brand Process 100,000+ Quality Documents with AI Read More »

A Coding Guide to Build Advanced Document Intelligence Pipelines with Google LangExtract, OpenAI Models, Structured Extraction, and Interactive Visualization

In this tutorial, we explore how to use Google’s LangExtract library to transform unstructured text into structured, machine-readable information. We begin by installing the required dependencies and securely configuring our OpenAI API key to leverage powerful language models for extraction tasks. Also, we will build a reusable extraction pipeline that enables us to process a

A Coding Guide to Build Advanced Document Intelligence Pipelines with Google LangExtract, OpenAI Models, Structured Extraction, and Interactive Visualization Read More »

TII Releases Falcon Perception: A 0.6B-Parameter Early-Fusion Transformer for Open-Vocabulary Grounding and Segmentation from Natural Language Prompts

In the current landscape of computer vision, the standard operating procedure involves a modular ‘Lego-brick’ approach: a pre-trained vision encoder for feature extraction paired with a separate decoder for task prediction. While effective, this architectural separation complicates scaling and bottlenecks the interaction between language and vision. The Technology Innovation Institute (TII) research team is challenging

TII Releases Falcon Perception: A 0.6B-Parameter Early-Fusion Transformer for Open-Vocabulary Grounding and Segmentation from Natural Language Prompts Read More »

IBM Releases Granite 4.0 3B Vision: A New Vision Language Model for Enterprise Grade Document Data Extraction

IBM has announced the release of Granite 4.0 3B Vision, a vision-language model (VLM) engineered specifically for enterprise-grade document data extraction. Departing from the monolithic approach of larger multimodal models, the 4.0 Vision release is architected as a specialized adapter designed to bring high-fidelity visual reasoning to the Granite 4.0 Micro language backbone. This release

IBM Releases Granite 4.0 3B Vision: A New Vision Language Model for Enterprise Grade Document Data Extraction Read More »

Alibaba Qwen Team Releases Qwen3.5 Omni: A Native Multimodal Model for Text, Audio, Video, and Realtime Interaction

The landscape of multimodal large language models (MLLMs) has shifted from experimental ‘wrappers’—where separate vision or audio encoders are stitched onto a text-based backbone—to native, end-to-end ‘omnimodal’ architectures. Alibaba Qwen team latest release, Qwen3.5-Omni, represents a significant milestone in this evolution. Designed as a direct competitor to flagship models like Gemini 3.1 Pro, the Qwen3.5-Omni

Alibaba Qwen Team Releases Qwen3.5 Omni: A Native Multimodal Model for Text, Audio, Video, and Realtime Interaction Read More »