
Large Language Model

Auto Added by WPeMatico

Google AI Releases Gemini 3.5 Transcribe: A Speech-to-Text Model Reporting 2.6% Average WER Across 85+ Languages

Google has released Gemini 3.5 Transcribe, a speech-to-text model for real-time voice interfaces and recorded audio. It ships as two endpoints, not one. gemini-3.5-transcribe handles pre-recorded files through the Interactions API. gemini-3.5-transcribe-live handles bidirectional streaming through the Live API. Google reports average word error rates of 4.0% streaming and 2.6% non-streaming, as measured by Artificial […]
Google AI Releases Gemini 3.5 Transcribe: A Speech-to-Text Model Reporting 2.6% Average WER Across 85+ Languages Read More »

From In-Silico to Wet-Lab: Evaluating AI Protein Design Performance

In this tutorial, we use Anthropic’s claude-protein-binder-design dataset, which contains 1,440 AI-designed miniprotein binders tested against 16 targets. Because the release includes both computational predictions and real wet-lab results from two independent labs, we can go beyond simply studying the designs. We evaluate how well structure predictors identify successful binders, whether combining predictions improves performance,

From In-Silico to Wet-Lab: Evaluating AI Protein Design Performance Read More »

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous Glucose Monitoring

Google Research and UNSW Sydney have released GlucoFM, a self-supervised foundation model for continuous glucose monitoring. Its core move is a split. Existing CGM models — CGMformer, GluFormer, CGM-JEPA — encode a glucose trace as one entangled sequence. GlucoFM decomposes it into a slow physiological “state” stream and a transient “event” stream, keeps the observation

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous Glucose Monitoring Read More »

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token Context

Z.ai has released GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series and the cheapest capable coding model the lab has shipped. It is a mixture-of-experts model with 320B total parameters and 18B active per token, a 1,048,576-token context window, and image and video input — released under an MIT license with weights on

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token Context Read More »

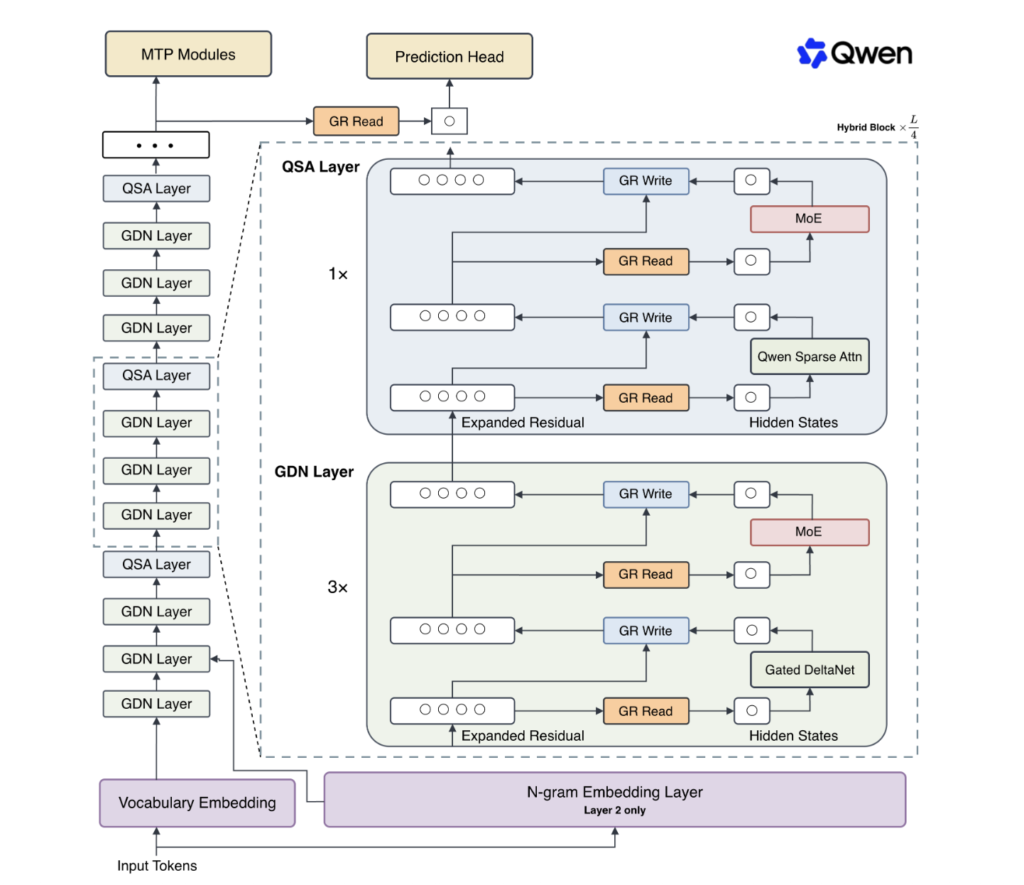
Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B Active Parameters Previewing the Qwen4 Architecture

Alibaba’s Qwen team has released Qwen3.8-Flash-Next, an open-weight multimodal Mixture-of-Experts model built for cost per token. The checkpoint pairs a 125B backbone with a 51B N-gram embedding table and a 4B multi-token prediction module. Only 6B parameters activate per token. The team positions it as an early preview of the architecture that will underpin Qwen4,

Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B Active Parameters Previewing the Qwen4 Architecture Read More »

IBM Releases Granite 4.2: Bringing Native Reasoning and Agentic RL to Open Enterprise Models

IBM has released Granite 4.2, a family of open reasoning language models in 3B, 8B, and 30B parameter sizes. Unlike earlier Granite releases, which were instruction-following assistants, Granite 4.2 is built around explicit reasoning. Every model can emit a chain of thought before answering, and every model exposes a thinking / non-thinking switch plus a

IBM Releases Granite 4.2: Bringing Native Reasoning and Agentic RL to Open Enterprise Models Read More »

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device Models, Quantization, Runtime and Hardware Together

Model cards report quality under server-class, full-precision conditions. Those numbers rarely predict how the same model behaves on a phone. This week, Liquid AI released Pipette. It is an open-source platform for benchmarking foundation models on edge devices, built in partnership with Artificial Analysis as an independent methodology validator. Pipette treats on-device behavior as a

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device Models, Quantization, Runtime and Hardware Together Read More »

Fastino Releases GLiNER2.5: A Boundary-Prediction Architecture That Removes Span Enumeration From Information Extraction

Information extraction teams face a recurring choice. Small encoder models are cheap but rigid, and large language models are flexible but expensive per document. Fastino released GLiNER2.5 to narrow that gap. The release replaces span enumeration with boundary prediction: the model scores where an entity starts and ends instead of scoring every candidate span against

Fastino Releases GLiNER2.5: A Boundary-Prediction Architecture That Removes Span Enumeration From Information Extraction Read More »

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks for Long-Horizon Legal Agent Work

Harvey has released Harvey Tenet, its first post-trained model, as a research preview as of today. Tenet is a Kimi K3 base post-trained with Fireworks through asynchronous reinforcement learning on long-horizon legal work. The training corpus combined synthetic data, publicly available legal data, and human expert data. Harvey states no customer data was used. Against

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks for Long-Horizon Legal Agent Work Read More »

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2 on a Single Workstation GPU

Frontier open-weight models are shipping faster than the hardware assumptions around them. Kimi-K3, GLM-5.2 and DeepSeek-V4-Flash are closing the capability gap with proprietary systems, but releasing parameters only determines who can obtain a model — not who can afford to run it. Serving them still assumes datacenter-class GPU clusters, and as agentic workloads push inference

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2 on a Single Workstation GPU Read More »