
Large Language Model

Auto Added by WPeMatico

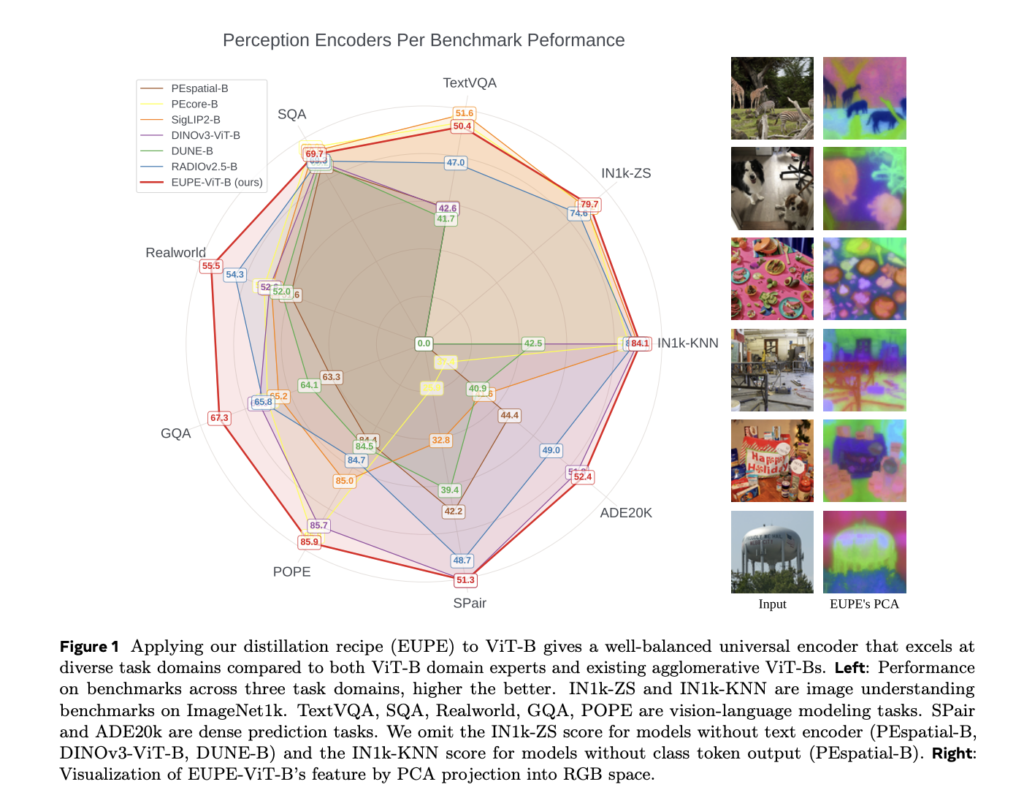
Meta AI Releases EUPE: A Compact Vision Encoder Family Under 100M Parameters That Rivals Specialist Models Across Image Understanding, Dense Prediction, and VLM Tasks

Running powerful AI on your smartphone isn’t just a hardware problem — it’s a model architecture problem. Most state-of-the-art vision encoders are enormous, and when you trim them down to fit on an edge device, they lose the capabilities that made them useful in the first place. Worse, specialized models tend to excel at one […]
Meta AI Releases EUPE: A Compact Vision Encoder Family Under 100M Parameters That Rivals Specialist Models Across Image Understanding, Dense Prediction, and VLM Tasks Read More »

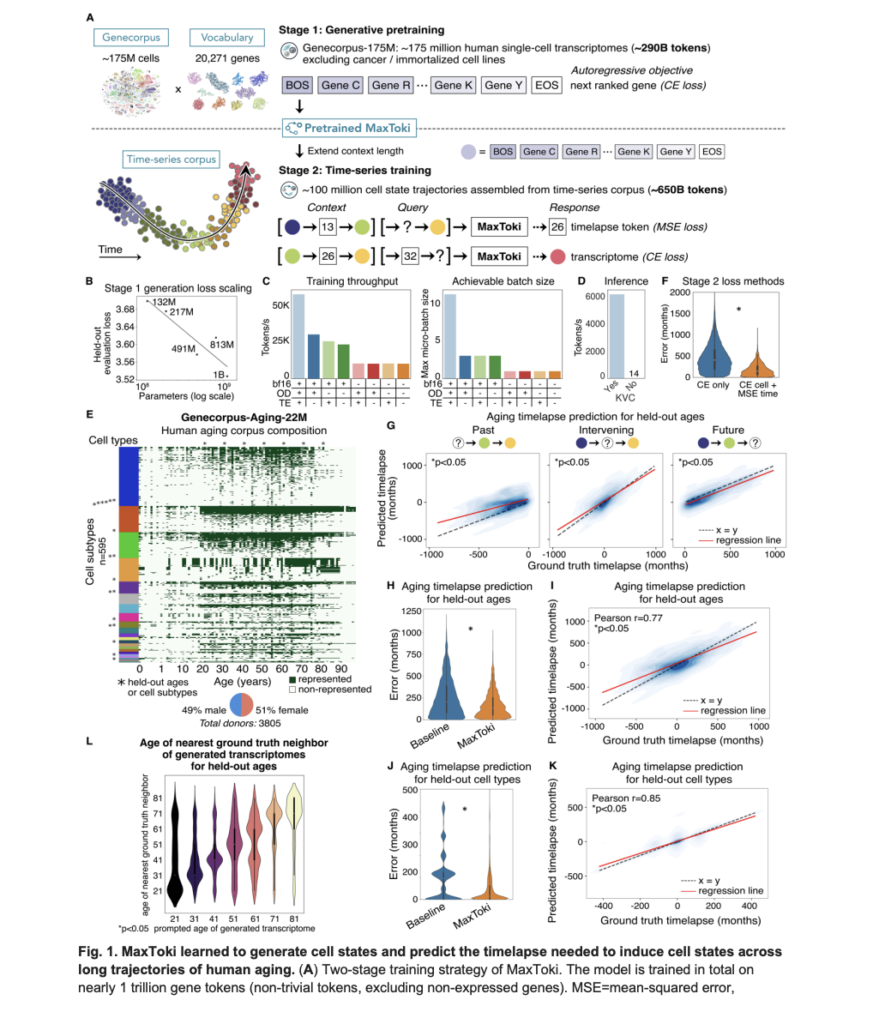
Meet MaxToki: The AI That Predicts How Your Cells Age — and What to Do About It

Most foundation models in biology have a fundamental blind spot: they see cells as frozen snapshots. Give a model a single-cell transcriptome — a readout of which genes are active in a cell at a given moment — and it can tell you a lot about what that cell is doing right now. What it

Meet MaxToki: The AI That Predicts How Your Cells Age — and What to Do About It Read More »

Google DeepMind’s Research Lets an LLM Rewrite Its Own Game Theory Algorithms — And It Outperformed the Experts

Designing algorithms for Multi-Agent Reinforcement Learning (MARL) in imperfect-information games — scenarios where players act sequentially and cannot see each other’s private information, like poker — has historically relied on manual iteration. Researchers identify weighting schemes, discounting rules, and equilibrium solvers through intuition and trial-and-error. Google DeepMind researchers proposes AlphaEvolve, an LLM-powered evolutionary coding agent

Google DeepMind’s Research Lets an LLM Rewrite Its Own Game Theory Algorithms — And It Outperformed the Experts Read More »

TII Releases Falcon Perception: A 0.6B-Parameter Early-Fusion Transformer for Open-Vocabulary Grounding and Segmentation from Natural Language Prompts

In the current landscape of computer vision, the standard operating procedure involves a modular ‘Lego-brick’ approach: a pre-trained vision encoder for feature extraction paired with a separate decoder for task prediction. While effective, this architectural separation complicates scaling and bottlenecks the interaction between language and vision. The Technology Innovation Institute (TII) research team is challenging

TII Releases Falcon Perception: A 0.6B-Parameter Early-Fusion Transformer for Open-Vocabulary Grounding and Segmentation from Natural Language Prompts Read More »

Step by Step Guide to Build an End-to-End Model Optimization Pipeline with NVIDIA Model Optimizer Using FastNAS Pruning and Fine-Tuning

In this tutorial, we build a complete end-to-end pipeline using NVIDIA Model Optimizer to train, prune, and fine-tune a deep learning model directly in Google Colab. We start by setting up the environment and preparing the CIFAR-10 dataset, then define a ResNet architecture and train it to establish a strong baseline. From there, we apply

Step by Step Guide to Build an End-to-End Model Optimization Pipeline with NVIDIA Model Optimizer Using FastNAS Pruning and Fine-Tuning Read More »

Arcee AI Releases Trinity Large Thinking: An Apache 2.0 Open Reasoning Model for Long-Horizon Agents and Tool Use

The landscape of open-source artificial intelligence has shifted from purely generative models toward systems capable of complex, multi-step reasoning. While proprietary ‘reasoning’ models have dominated the conversation, Arcee AI has released Trinity Large Thinking. This release is an open-weight reasoning model distributed under the Apache 2.0 license, positioning it as a transparent alternative for developers

Arcee AI Releases Trinity Large Thinking: An Apache 2.0 Open Reasoning Model for Long-Horizon Agents and Tool Use Read More »

Defeating the ‘Token Tax’: How Google Gemma 4, NVIDIA, and OpenClaw are Revolutionizing Local Agentic AI: From RTX Desktops to DGX Spark

Run Google’s latest omni-capable open models faster on NVIDIA RTX AI PCs, from NVIDIA Jetson Orin Nano, GeForce RTX desktops to the new DGX Spark, to build personalized, always-on AI assistants like OpenClaw without paying a massive “token tax” for every action. The landscape of modern AI is shifting rapidly. We are moving away from

Defeating the ‘Token Tax’: How Google Gemma 4, NVIDIA, and OpenClaw are Revolutionizing Local Agentic AI: From RTX Desktops to DGX Spark Read More »

IBM Releases Granite 4.0 3B Vision: A New Vision Language Model for Enterprise Grade Document Data Extraction

IBM has announced the release of Granite 4.0 3B Vision, a vision-language model (VLM) engineered specifically for enterprise-grade document data extraction. Departing from the monolithic approach of larger multimodal models, the 4.0 Vision release is architected as a specialized adapter designed to bring high-fidelity visual reasoning to the Granite 4.0 Micro language backbone. This release

IBM Releases Granite 4.0 3B Vision: A New Vision Language Model for Enterprise Grade Document Data Extraction Read More »

Z.ai Launches GLM-5V-Turbo: A Native Multimodal Vision Coding Model Optimized for OpenClaw and High-Capacity Agentic Engineering Workflows Everywhere

In the field of vision-language models (VLMs), the ability to bridge the gap between visual perception and logical code execution has traditionally faced a performance trade-off. Many models excel at describing an image but struggle to translate that visual information into the rigorous syntax required for software engineering. Zhipu AI’s (Z.ai) GLM-5V-Turbo is a vision

Z.ai Launches GLM-5V-Turbo: A Native Multimodal Vision Coding Model Optimized for OpenClaw and High-Capacity Agentic Engineering Workflows Everywhere Read More »