Large Language Model

Auto Added by WPeMatico

Meet LingBot-World-Infinity: An Open Causal World Model With An Agentic Harness

Robbyant, Ant Group’s embodied-intelligence unit, has released LingBot-World-Infinity (LingBot-World 2.0). It is a causal video generation model that behaves as an interactive world simulator. It is how the team attacks two failure modes: long-horizon drift and interactive latency. What is LingBot-World-Infinity? An interactive world model generates video frame by frame, conditioned on a stream of […]

Meet LingBot-World-Infinity: An Open Causal World Model With An Agentic Harness Read More »
Meet Nemotron Labs 3 Puzzle 75B A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput

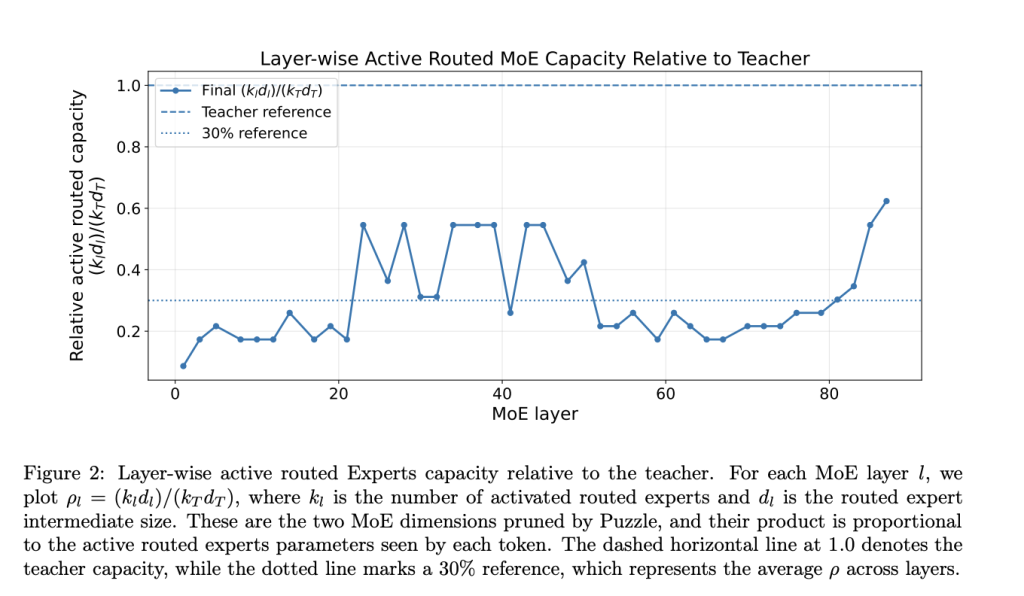
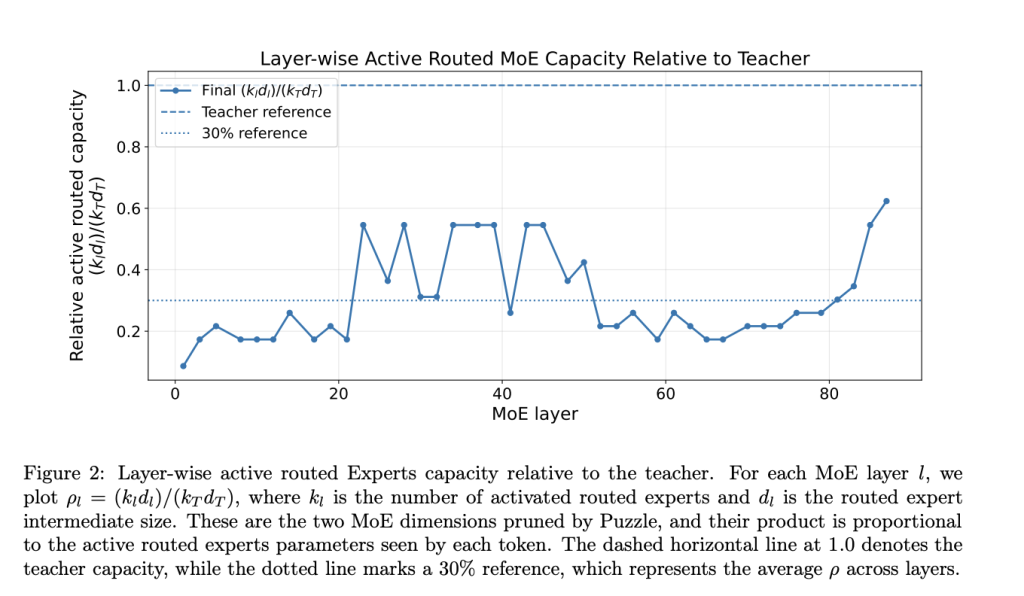
Large hybrid MoE models like Nemotron-3-Super are accurate but expensive to serve. Their active parameters, KV cache, and Mamba state cap how many users a node can hold at a given per-user token rate. NVIDIA AI team has released Nemotron-Labs-3-Puzzle-75B-A9B, a compressed variant of Nemotron-3-Super. The parent model has 120.7B total and 12.8B active parameters.

Meet Nemotron Labs 3 Puzzle 75B A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput Read More »

NVIDIA Releases Nemotron-Labs-3-Puzzle-75B-A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput at Matched User Throughput

Large hybrid MoE models like Nemotron-3-Super are accurate but expensive to serve. Their active parameters, KV cache, and Mamba state cap how many users a node can hold at a given per-user token rate. NVIDIA AI team has released Nemotron-Labs-3-Puzzle-75B-A9B, a compressed variant of Nemotron-3-Super. The parent model has 120.7B total and 12.8B active parameters.

NVIDIA Releases Nemotron-Labs-3-Puzzle-75B-A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput at Matched User Throughput Read More »

Datalab Lift vs the Field: How a 9B Schema-First Extractor Compares with NuExtract3, LlamaExtract, Marker, and Docling

Datalab’s Lift is a focused document extraction tool with a specific promise: give it a PDF or image plus a JSON Schema, and it returns schema-shaped JSON directly. Instead of converting a document to Markdown first and then asking another model to extract fields, Lift reads rendered page images and attempts to emit the final

Datalab Lift vs the Field: How a 9B Schema-First Extractor Compares with NuExtract3, LlamaExtract, Marker, and Docling Read More »

Robbyant Releases LingBot-VLA 2.0: An Open-Source 6B Vision-Language-Action (VLA) Model for Cross-Embodiment Robot Manipulation

Ant Group’s Robbyant has released LingBot-VLA 2.0, a Vision-Language-Action (VLA) foundation model for robots. The release includes a technical report, an Apache-2.0 codebase, and a 6B checkpoint. The research team targets a well-known gap: VLA models often work in labs but stumble in deployment. LingBot-VLA 2.0 advances the prior version along three practical axes. These

Robbyant Releases LingBot-VLA 2.0: An Open-Source 6B Vision-Language-Action (VLA) Model for Cross-Embodiment Robot Manipulation Read More »

SpaceXAI Releases Grok 4.5, a Cursor-Trained Model for Coding, Agentic Tasks, and Knowledge Work at $2/M Input

SpaceXAI just released Grok 4.5. The company calls it its smartest model to date. It targets coding, agentic tasks, and knowledge work. SpaceXAI says Grok 4.5 was trained alongside Cursor, an AI coding editor. TL;DR Grok 4.5 targets coding, agentic tasks, and knowledge work, trained alongside Cursor. In SpaceXAI’s own chart, Fable (max) leads all

SpaceXAI Releases Grok 4.5, a Cursor-Trained Model for Coding, Agentic Tasks, and Knowledge Work at $2/M Input Read More »

Netflix AI Team Cuts Wide-Partition Read Latency from Seconds to Milliseconds by Splitting Cassandra Partitions Per ID

Netflix’s engineering team published a method for handling wide partitions in Apache Cassandra. The research work targets Netflix’s TimeSeries Abstraction, a platform for temporal event data. TL;DR Dynamic partitioning splits wide Cassandra partitions per TimeSeries ID, asynchronously and transparently, with no application changes. Detection runs on the read path via byte counting and a Kafka

Netflix AI Team Cuts Wide-Partition Read Latency from Seconds to Milliseconds by Splitting Cassandra Partitions Per ID Read More »

OpenAI Releases GPT-Live and GPT-Live-1 mini: Full-Duplex Voice Models That Delegate Deeper Reasoning to GPT-5.5

Today, OpenAI released GPT-Live. It is a new generation of voice models. GPT-Live now powers the ChatGPT Voice experience. The stated goal is natural, real-time conversation with AI. Two versions ship first: GPT-Live-1 and GPT-Live-1 mini. Both roll out to ChatGPT users globally today. TL;DR GPT-Live is a full-duplex voice model family that listens and

OpenAI Releases GPT-Live and GPT-Live-1 mini: Full-Duplex Voice Models That Delegate Deeper Reasoning to GPT-5.5 Read More »

Ant Group’s Robbyant Open-Sources LingBot-Vision: A 1B Boundary-Centric Vision Foundation Model for Dense Spatial Perception

Robbyant, the embodied-AI company within Ant Group, has open-sourced LingBot-Vision, a family of self-supervised Vision Transformers built for dense spatial perception. The weights ship under Apache-2.0 on Hugging Face in four sizes — ViT-giant, ViT-large, ViT-base, and ViT-small — together with a technical report and inference code. Most vision foundation models are trained for semantic

Ant Group’s Robbyant Open-Sources LingBot-Vision: A 1B Boundary-Centric Vision Foundation Model for Dense Spatial Perception Read More »

NVIDIA Releases Audex (Nemotron-Labs-Audex-30B-A3B): A Unified Audio-Text LLM That Preserves the Text Intelligence of Its Backbone

NVIDIA has released Audex (Nemotron-Labs-Audex-30B-A3B), a unified audio-text large language model. It understands and generates both audio and speech. It also keeps the text intelligence of its backbone. The checkpoints, along with a smaller Audex-2B, are released under a noncommercial license. Most multimodal models pay a text tax. When labs add audio or vision output,

NVIDIA Releases Audex (Nemotron-Labs-Audex-30B-A3B): A Unified Audio-Text LLM That Preserves the Text Intelligence of Its Backbone Read More »