Large Language Model

Auto Added by WPeMatico

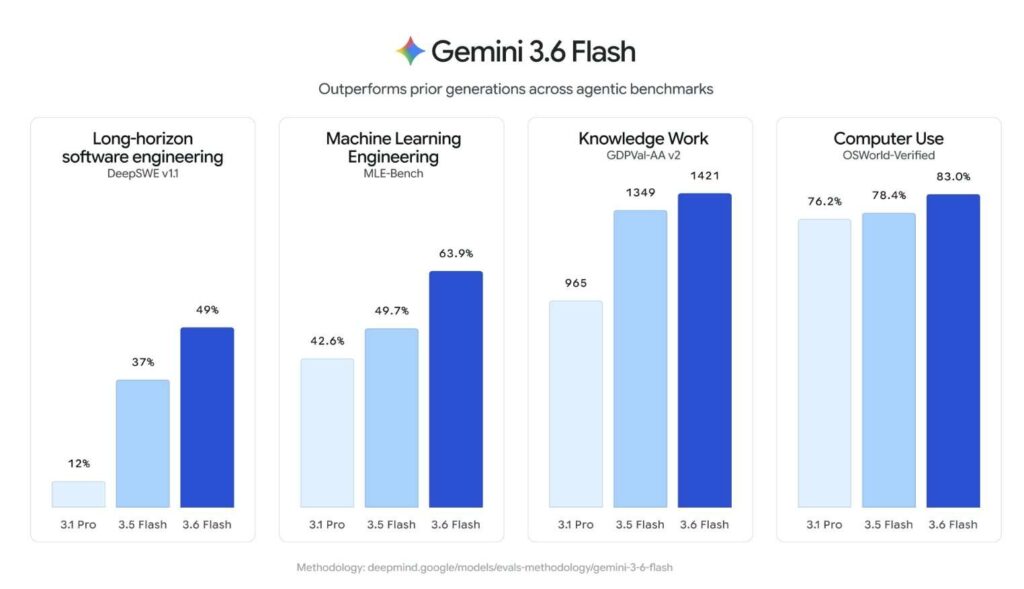
Google Releases Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber: A Cheaper, More Token-Efficient Flash Tier Built for Agentic Workloads

Developers building production agents need higher token efficiency, lower latency, and more reliable performance. Today, Google has released three new Gemini models. The lineup is Gemini 3.6 Flash, Gemini 3.5 Flash-Lite, and Gemini 3.5 Flash Cyber. All three sit in the Flash tier, which Google tunes for speed, cost, and high-volume agentic work rather than […]
Google Releases Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber: A Cheaper, More Token-Efficient Flash Tier Built for Agentic Workloads Read More »

NVIDIA Releases Cosmos 3 Edge: A 4B-Parameter Open World Model That Reasons and Generates Robot Actions On-Device

NVIDIA has released Cosmos 3 Edge, a 4-billion-parameter open world model built to run on-device. It helps robots and vision AI agents understand surroundings, reason in real time, and generate robot actions locally. The Cosmos 3 family included Cosmos 3 Nano (16B) and Cosmos 3 Super (64B) shipped on May 31, 2026 at GTC Taipei.

NVIDIA Releases Cosmos 3 Edge: A 4B-Parameter Open World Model That Reasons and Generates Robot Actions On-Device Read More »

Someone Fine-Tuned OpenBMB’s MiniCPM5-1B on Claude Fable 5 Traces to Ship a 657MB Local Thinking Model

A community developer, GnLOLot, has published a 1B model that runs fully on local hardware. The model is MiniCPM5-1B-Claude-Opus-Fable5-Thinking, with GGUF builds for llama.cpp-compatible runtimes. It needs no API key and makes no cloud calls. The Proposed Model The model is built on openbmb/MiniCPM5-1B. That base is a real, documented release from OpenBMB. It is

Someone Fine-Tuned OpenBMB’s MiniCPM5-1B on Claude Fable 5 Traces to Ship a 657MB Local Thinking Model Read More »

Best Local LLMs You Can Run on a Single 24GB GPU in 2026: Qwen, Gemma, Mistral, DeepSeek Compared

A single 24GB card is the practical floor for serious local inference. It is enough for genuinely capable models, and small enough to sit on one GPU. An RTX 3090 or RTX 4090 both land in this tier. The card you own matters less than the models you pick for it. The old hobbyist move

Best Local LLMs You Can Run on a Single 24GB GPU in 2026: Qwen, Gemma, Mistral, DeepSeek Compared Read More »

Alibaba Previews Qwen3.8-Max, a 2.4 Trillion-Parameter Multimodal Model, Days After Moonshot’s Kimi K3 Open-Weight Launch

On July 19, Alibaba’s Qwen team previewed Qwen3.8-Max-Preview, the next flagship in the Qwen family. The research team describes it as a 2.4 trillion-parameter model, ‘second only to Fable 5’ among the systems it benchmarked. The preview is live now. The benchmark table, model card, and license are not. The July 19th 2026 announcement landed

Alibaba Previews Qwen3.8-Max, a 2.4 Trillion-Parameter Multimodal Model, Days After Moonshot’s Kimi K3 Open-Weight Launch Read More »

Kimi K3 vs DeepSeek V4 Pro vs GLM-5.2: Open Trillion-Scale MoE Models Compared on Benchmarks, License, and Serving Cost

Three Chinese labs now hold the top of the open-weight leaderboard. Moonshot AI’s Kimi K3, DeepSeek V4 Pro, and Zhipu AI’s GLM-5.2 are all sparse Mixture-of-Experts (MoE) models with million-token context windows. Each targets long-horizon coding and agent workloads. This article compares them on three axes an AI team actually decides on: measured capability, license

Kimi K3 vs DeepSeek V4 Pro vs GLM-5.2: Open Trillion-Scale MoE Models Compared on Benchmarks, License, and Serving Cost Read More »

Sakana AI’s Error Diffusion Trains Dale-Compliant Dual-Stream Networks, Reaching 96.7% MNIST and 61.7% CIFAR-10 Without Backpropagation

Backpropagation dominates deep learning, yet it uses a mechanism the brain likely cannot. Specifically, the backward pass needs exact transposes of forward weight matrices. This is the weight transport problem. Sakana AI’s new paper, Diffusing Blame, confronts this constraint directly. The research team trains networks that obey Dale’s principle while avoiding weight transport entirely. What

Sakana AI’s Error Diffusion Trains Dale-Compliant Dual-Stream Networks, Reaching 96.7% MNIST and 61.7% CIFAR-10 Without Backpropagation Read More »

Zyphra Releases ZUNA1.1: An Apache 2.0 EEG Foundation Model With Variable-Length Inputs From 0.5 To 30 Seconds

This week, Zyphra released ZUNA1.1 under the Apache 2.0 license. The EEG foundation model reconstructs, denoises, and upsamples data across arbitrary channel layouts. It builds on ZUNA1, the Zyphra’s earlier open EEG foundation model. The main change is flexibility, not a jump in raw accuracy. Real EEG recordings are messy. Sessions vary in length, and

Zyphra Releases ZUNA1.1: An Apache 2.0 EEG Foundation Model With Variable-Length Inputs From 0.5 To 30 Seconds Read More »

NVIDIA AI Releases Nemotron 3 Embed: An Open Embedding Collection Whose 8B Checkpoint Ranks #1 on RTEB

Embedding models decide which passages an agent ever sees. NVIDIA released Nemotron 3 Embed model to work on that layer. It targets production-scale RAG, agentic retrieval, code retrieval, and agent memory. What is Nemotron 3 Embed? The model collection includes three open checkpoints. Nemotron-3-Embed-8B-BF16 is the accuracy-first option. Nemotron-3-Embed-1B-BF16 carries the same design into a

NVIDIA AI Releases Nemotron 3 Embed: An Open Embedding Collection Whose 8B Checkpoint Ranks #1 on RTEB Read More »

Moonshot AI Releases Kimi K3: A 2.8 Trillion Parameter Open MoE Model With Kimi Delta Attention and 1M Context

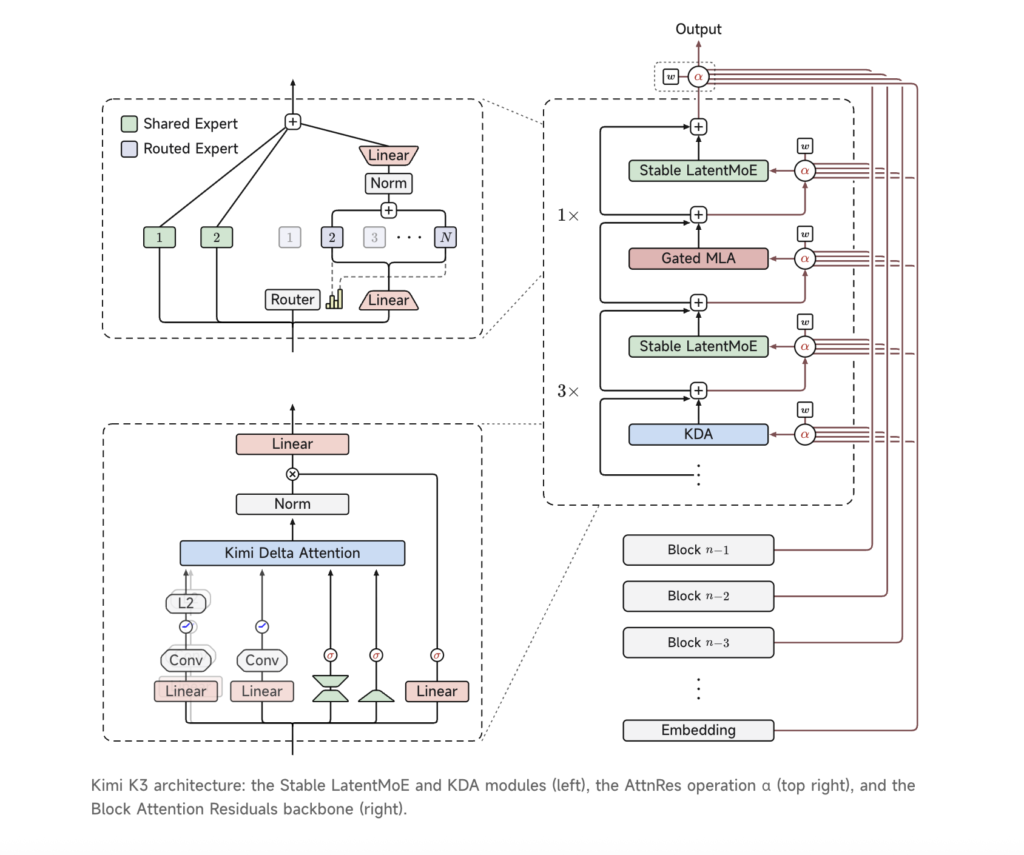
Moonshot AI just released Kimi K3. It is a 2.8-trillion-parameter model with native vision and a 1-million-token context window. Moonshot calls it the world’s first open 3T-class model. What is Kimi K3? Kimi K3 is a sparse Mixture-of-Experts (MoE) model built on two architectural updates. Those are Kimi Delta Attention (KDA) and Attention Residuals (AttnRes).

Moonshot AI Releases Kimi K3: A 2.8 Trillion Parameter Open MoE Model With Kimi Delta Attention and 1M Context Read More »