Large Language Model

Auto Added by WPeMatico

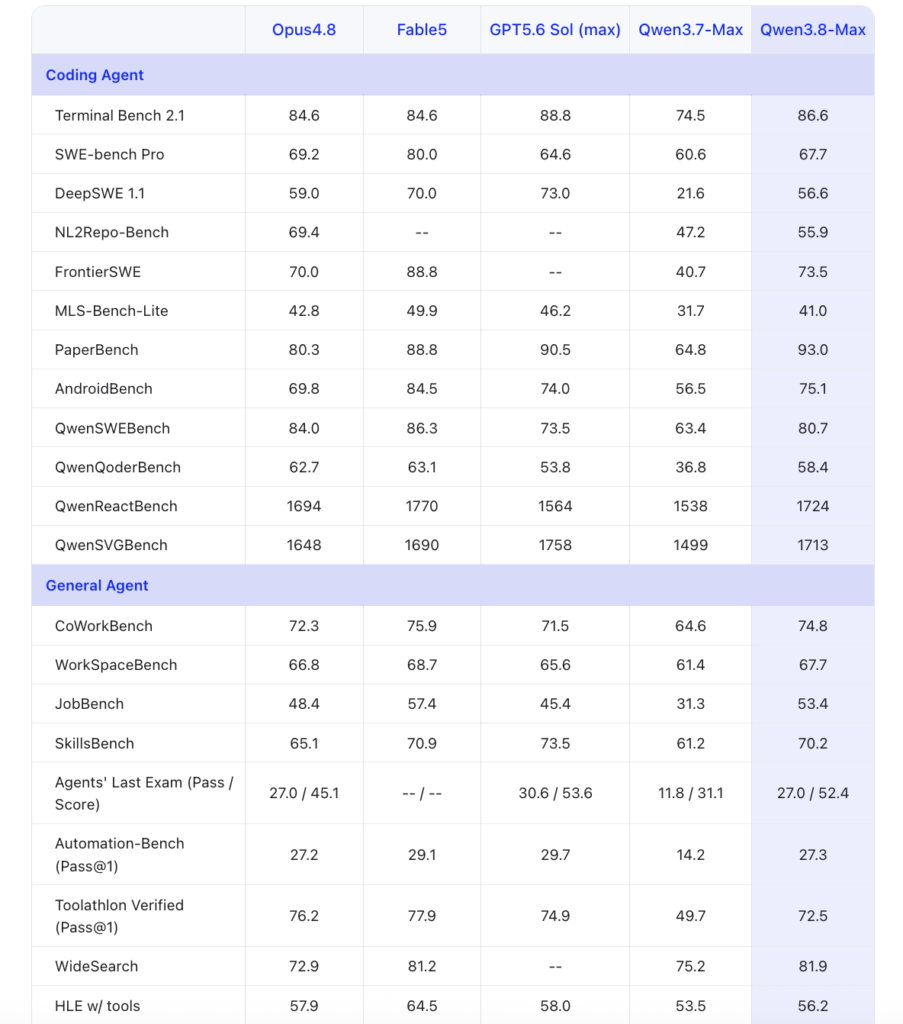
Alibaba Qwen Releases Qwen3.8-Max: A 2.4 Trillion Parameter MoE Model and the Most Capable One in the Qwen Family to Date

Alibaba’s Qwen team has made Qwen3.8-Max broadly available and confirmed that its open weights ship next week. A second checkpoint, Qwen3.8-27B, is also going open-weights. Qwen3.8-Max is a 2.4-trillion-parameter mixture-of-experts model. It accepts text, image and video as input and returns text. Is it deployable Yes, but the deployable surface depends on which artifact you […]
Alibaba Qwen Releases Qwen3.8-Max: A 2.4 Trillion Parameter MoE Model and the Most Capable One in the Qwen Family to Date Read More »

Cogent AI Team Releases VR-1: A Frontier Cyber Reasoning Model That Composes and Verifies Enterprise Attack Paths

Cogent AI team released Cogent VR-1, a reasoning model post-trained specifically for cybersecurity rather than picking up cyber capability as a side effect of general coding strength. It ships with two companions: IntrusionBench, a benchmark that scores agents on completed enterprise intrusions, and the Cogent AI Harness, a governed runtime for security agents. The launch

Cogent AI Team Releases VR-1: A Frontier Cyber Reasoning Model That Composes and Verifies Enterprise Attack Paths Read More »

AMD Releases Instella-MoE-16B-A3B: A Fully Open Mixture-of-Experts LLM With 2.8B Active Parameters Trained On Instinct GPUs

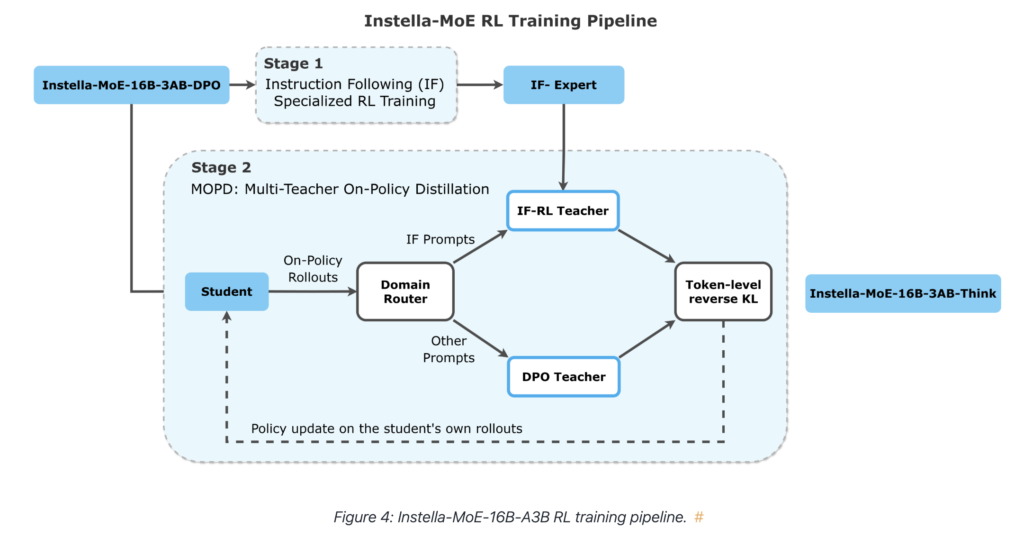
AMD released Instella-MoE-16B-A3B, a fully open Mixture-of-Experts language model trained from scratch on Instinct MI300X and MI325X GPUs. The model holds 16B total parameters but activates only 2.8B per token. AMD is publishing weights from every training stage, along with data mixtures, training configs, and inference code. Two systems-level choices carry the release: Gated Multi-head

AMD Releases Instella-MoE-16B-A3B: A Fully Open Mixture-of-Experts LLM With 2.8B Active Parameters Trained On Instinct GPUs Read More »

MiniMax Releases MiniMax H3: An Omni-Modal Video Model That Generates 15-Second 2K Clips With Native Stereo Audio

MiniMax releases MiniMax H3, a general-purpose multimodal generation model. MiniMax H3 is not a text-to-video model with add-ons. MiniMax describes it as a general-purpose multimodal generation model that reads text, images, video, and audio as one unified context and returns video with native stereo sound. The mains specs include: 2K output, 4–15 seconds, integer durations

MiniMax Releases MiniMax H3: An Omni-Modal Video Model That Generates 15-Second 2K Clips With Native Stereo Audio Read More »

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains

DeepSeek published DeepSeek-V4-Flash-0731 on Hugging Face and moved the official V4-Flash API into public beta on July 31, 2026. The model card is explicit that this is the official release superseding the preview, and that the architecture and size are unchanged. The gains come from re-post-training, not a new design. The checkpoint ships with the

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains Read More »

Google DeepMind Ships Three Physical AI Models For Whole Body Control, Dexterity And Multi Robot Collaboration

Google DeepMind has released Gemini Robotics 2, the intelligence layer for its next generation of robots. The release moves the stack past table-top manipulation into whole body control, five finger dexterity and multi robot teamwork. It ships as three separate models with three different access tiers. Most robots today are pre-programmed or tele-operated for narrow,

Google DeepMind Ships Three Physical AI Models For Whole Body Control, Dexterity And Multi Robot Collaboration Read More »

Liquid AI Releases LFM2.5-Encoder-230M and LFM2.5-Encoder-350M: Bidirectional Encoders That Stay Fast at 8K Context on CPU

Liquid AI has released two open-weight bidirectional encoders, LFM2.5-Encoder-230M and LFM2.5-Encoder-350M. Both are masked language models built on the LFM2 hybrid backbone. Both carry an 8,192-token context. Encoders sit underneath classifiers, intent routers, safety filters, and PII detectors. Those jobs run continuously, usually without a GPU, and increasingly on longer inputs. BERT established the class.

Liquid AI Releases LFM2.5-Encoder-230M and LFM2.5-Encoder-350M: Bidirectional Encoders That Stay Fast at 8K Context on CPU Read More »

Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for Image, Video, Audio and Robot Action Prediction

Black Forest Labs (BFL) has released FLUX 3, a multimodal foundation model that learns from images, videos and audio inside a single architecture. It is also the first FLUX model to ship video, audio and action prediction from one set of weights. The Black Forest Labs (BFL) research team argues that no single modality gives

Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for Image, Video, Audio and Robot Action Prediction Read More »

KwaiKAT Team Releases KAT-Coder-V2.5: An Agentic Coding Model Trained on 100,000+ Verifiable Repository Environments

The KwaiKAT Team at Kuaishou has introduced the KAT-Coder-V2.5. It is a coding model trained to operate inside real, executable repositories rather than emit single-turn code. The served model is available through StreamLake. An open-weight variant, KAT-Coder-V2.5-Dev, was released separately on Hugging Face under Apache-2.0. AutoBuilder: environments that actually run the intended tests The research

KwaiKAT Team Releases KAT-Coder-V2.5: An Agentic Coding Model Trained on 100,000+ Verifiable Repository Environments Read More »

Sakana AI Releases Fugu-Cyber: An Orchestration Model Reporting 86.9% on CyberGym and 72.1% on CTI-REALM

Sakana AI has released Fugu-Cyber (model ID is fugu-cyber-v1.0), a cybersecurity-specialized addition to its Fugu orchestration family. It is not just a new frontier model. It is a third endpoint on the Fugu orchestrator, tuned for security reasoning. Sakana launched that orchestrator a month earlier. Sakana reports a success rate of 86.9% on CyberGym and

Sakana AI Releases Fugu-Cyber: An Orchestration Model Reporting 86.9% on CyberGym and 72.1% on CTI-REALM Read More »