Enterprise AI

Auto Added by WPeMatico

Perplexity Introduces Photon: A Rust-Based Retrieval Engine That Cuts p99 Latency From 800 ms to 65 ms

Perplexity has released Photon, an in-house retrieval and ranking engine written in Rust. It replaces an open-source engine Perplexity had forked for its AI-native search stack. Photon now handles retrieval and ranking for all production traffic. It also powers a new Fast Search mode in the Perplexity Search API. Perplexity reports single-call latency of 160
Perplexity Introduces Photon: A Rust-Based Retrieval Engine That Cuts p99 Latency From 800 ms to 65 ms Read More »

H Company Releases Holo4: Open-Weight Computer-Use Models That Click, Code and Call Tools Across Desktop, Web, Android and APIs

H Company has released Holo4, a family of generalist computer-use models for AI agents. One set of weights clicks and types on screens. It also writes code and calls MCP or API tools. Holo4 ships in 2 sizes: Holo4 27B (dense) and Holo4 35B-A3B (Mixture of Experts, 3B active). Both serve a 256K context on

H Company Releases Holo4: Open-Weight Computer-Use Models That Click, Code and Call Tools Across Desktop, Web, Android and APIs Read More »

NVIDIA Launches Open Agent Safety Platform: OpenShell Sandboxes Agents on Vera CPUs While Sentry on BlueField-4 Quarantines Them in Milliseconds

NVIDIA has launched the NVIDIA Open Agent Safety Platform, an open software platform and reference system design for AI agent security. It pairs the OpenShell secure runtime with NVIDIA Sentry, an out-of-band watchdog on BlueField-4 DPUs. The core idea is simple. Safety controls should not live inside the agent they are meant to control. Today,

NVIDIA Launches Open Agent Safety Platform: OpenShell Sandboxes Agents on Vera CPUs While Sentry on BlueField-4 Quarantines Them in Milliseconds Read More »

AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared

Our ‘Top AI Coding Agents and Development Platforms‘ guide covered what each AI coding agent does and where it fits. This piece is for a different reader. It is written for the procurement lead, the general counsel and the security reviewer. Those readers ask 4 questions before any rollout. Who pays if generated code triggers

AI Coding Agents for Enterprise: IP Indemnity, Data Residency and 500-Seat Cost Compared Read More »

AI Assurance

AI Assurance in Action: Practical Testing Scenarios for AI Systems

  AI Assurance sounds straightforward until an AI system is deployed in the real world. A chatbot may produce a convincing but incorrect answer. An AI agent may follow instructions hidden inside a document. A model upgrade may change previously reliable responses. An AI test-generation tool may create test cases that look correct but miss

AI Assurance in Action: Practical Testing Scenarios for AI Systems Read More »

AI agent engineering

What Is AI Agent Engineering? A Complete Guide to Building Intelligent AI Agents

A chatbot waits for your question. An automation waits for a predefined trigger. An AI agent can take a goal, figure out what needs to happen, use the right tools, make decisions along the way, and take action. That difference is changing how enterprises think about software. Instead of building applications that only respond to

What Is AI Agent Engineering? A Complete Guide to Building Intelligent AI Agents Read More »

PrismML Releases Ternary Bonsai 2 27B: A 5.9 GB Apache 2.0 Model Retaining 98.2% of Qwen3.8 27B Performance

PrismML has released Ternary Bonsai 2 27B, a ternary-weight version of Qwen3.8 27B. The language model occupies 5.93 GB, against 53.80 GB in FP16. PrismML reports that it keeps 98.2% of the parent model’s average across 20 benchmarks. The model accepts text and images and supports a 262K-token context. PrismML demos it driving Cline coding

PrismML Releases Ternary Bonsai 2 27B: A 5.9 GB Apache 2.0 Model Retaining 98.2% of Qwen3.8 27B Performance Read More »

OpenAI Releases a Model Misalignment Disclosure Framework With 3 Review Tracks and 6 Incident Reports From RL Training

OpenAI has released a new framework for tracking, investigating, and disclosing misalignment in its own models. The OpenAI team announced it on X alongside 6 detailed incident reports. The framework sets criteria and deadlines for public disclosure. It applies even when OpenAI has not fully explained or mitigated the behavior. Why OpenAI Built It OpenAI’s

OpenAI Releases a Model Misalignment Disclosure Framework With 3 Review Tracks and 6 Incident Reports From RL Training Read More »

Meet Redis LangCache: A Managed Semantic Cache That Cuts LLM API Costs by Up to 90% and Returns Cache Hits Up to 15x Faster

Production LLM applications rarely receive a question nobody has asked before. Support assistants and RAG pipelines field the same intents thousands of times a day, each phrased differently, and most stacks treat every phrasing as a fresh, fully billed request. Redis LangCache is a fully managed semantic caching service that sits between the application and

Meet Redis LangCache: A Managed Semantic Cache That Cuts LLM API Costs by Up to 90% and Returns Cache Hits Up to 15x Faster Read More »

Edge AI + IoT

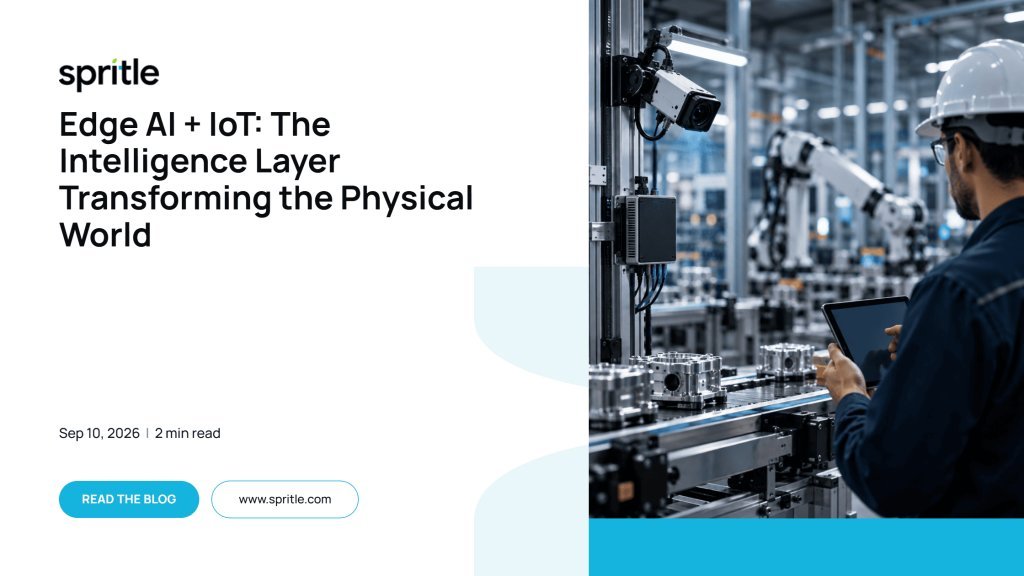
Edge AI + IoT: The Intelligence Layer Transforming the Physical World

From connected devices to intelligent decisions – how businesses can turn real-world data into real-time action.   AI Is Moving Beyond the Cloud Artificial Intelligence has become an important part of how businesses operate. Organizations are using AI to analyze information, automate processes, improve customer experiences, and support better decision-making. But the next evolution of

Edge AI + IoT: The Intelligence Layer Transforming the Physical World Read More »