
Embedding Model

Auto Added by WPeMatico

Cohere Releases Embed 5: How It Compares to Voyage 4 Large, Gemini Embedding 2, and OpenAI

Cohere has released Embed 5, a new embedding model family. It targets enterprise search, RAG, and agentic retrieval. The model family ships in 2 tiers. Embed 5 Pro targets maximum retrieval quality. Embed 5 Fast targets latency and cost on the live query path. Both accept text, images, and fused text plus image inputs. Both
Cohere Releases Embed 5: How It Compares to Voyage 4 Large, Gemini Embedding 2, and OpenAI Read More »

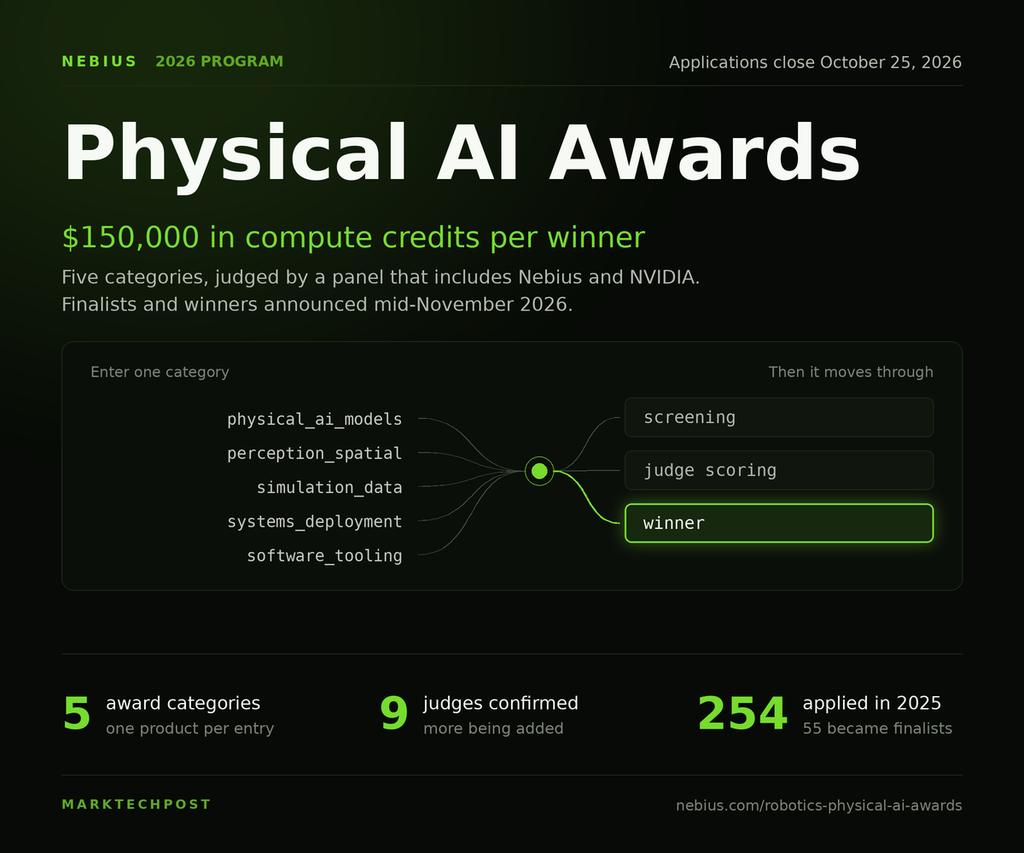
Nebius Opens 2026 Physical AI Awards: Five $150K Compute Credit Prizes

Once a physical AI product is in the field, the compute problem changes shape. Fleet data starts arriving faster than a team can label it, every retraining cycle has to be validated before it ships to hardware, and the sim-to-real loop stops being a research exercise and becomes a release process. That is the stage

Nebius Opens 2026 Physical AI Awards: Five $150K Compute Credit Prizes Read More »

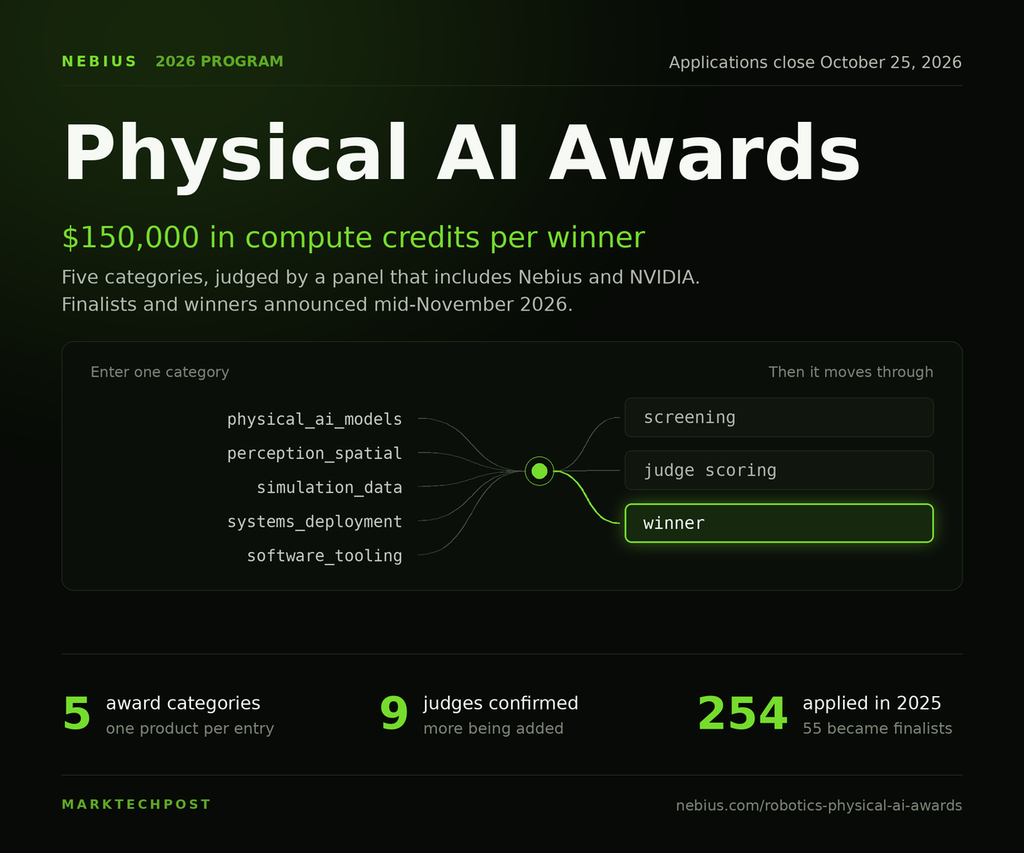
Nebius Opens 2026 Physical AI Awards: Five $150K Compute Prizes, Nine Judges, and an October 25 Deadline

Once a physical AI product is in the field, the compute problem changes shape. Fleet data starts arriving faster than a team can label it, every retraining cycle has to be validated before it ships to hardware, and the sim-to-real loop stops being a research exercise and becomes a release process. That is the stage

Nebius Opens 2026 Physical AI Awards: Five $150K Compute Prizes, Nine Judges, and an October 25 Deadline Read More »

Black Forest Labs Releases FLUX 3 Action: A 7B Open-Weights World Action Model That Tops RoboLab-120

Black Forest Labs (BFL), the lab behind the FLUX image models, has released FLUX 3 Action. It is a 7B open-weights World Action Model (WAM) for robot control. The model reads camera frames, robot state and a text instruction. It then predicts future video frames and the next chunk of actions together. On the RoboLab-120

Black Forest Labs Releases FLUX 3 Action: A 7B Open-Weights World Action Model That Tops RoboLab-120 Read More »

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

Linkup research team releases SPARSEUP, an open-source learned sparse embedding model. The model runs on a 149M-parameter ModernBERT backbone and ships under Apache 2.0. Linkup team reports 56.4 average nDCG@10 on BEIR-13. It calls this the strongest public vocabulary-based sparse encoder it knows of under 150M parameters. Is it deployable? Yes. The weights are on

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model Read More »

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page

Last week, Reducto announced r-1. It is the first model in a new parsing family built on a rewritten architecture, and it replaces the company’s multi stage agentic OCR with one full page pass. Reducto says r-1 is more accurate than its most powerful legacy agentic models, faster, and up to 6x cheaper. Is it

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts Errors 20% at 1 Cent Per Page Read More »

Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot Manipulation Tasks and 50,129 Trajectories

Robot manipulation datasets have grown far slower than the models trained on them, mostly because collection stays closed and centralized. Expert operators gather demonstrations on lab hardware, process them offline, and ship a fixed benchmark that never grows again. A research team from Axis Robotics, UC Berkeley, Georgia Tech, NTU… is proposing a different shape

Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot Manipulation Tasks and 50,129 Trajectories Read More »

Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown

Cohere has released Parse (parse-v5.0), a document parsing model aimed at high-volume enterprise ingestion. It is a 2.3B-parameter vision language model with an 8,192-token context window and a ~4.6GB footprint, built on Cohere Labs’ North-Micro-Vision-Instruct architecture. Parse takes a PDF, PPT or JPEG page as a base64-encoded data URI and returns Markdown containing text in

Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That Turns Enterprise Documents Into Markdown Read More »

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks for Long-Horizon Legal Agent Work

Harvey has released Harvey Tenet, its first post-trained model, as a research preview as of today. Tenet is a Kimi K3 base post-trained with Fireworks through asynchronous reinforcement learning on long-horizon legal work. The training corpus combined synthetic data, publicly available legal data, and human expert data. Harvey states no customer data was used. Against

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks for Long-Horizon Legal Agent Work Read More »

▶

Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million Hours of Human Video

Dyna Robotics has released Dyna-2, a world-action model for robot manipulation. It was pre-trained on more than one million hours of egocentric human video. That is roughly 170 years of continuous waking experience. Robot learning has been bottlenecked by action-labelled data, which teleoperation must deliberately produce. Dyna-2 tests whether ordinary human video can substitute. The

Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million Hours of Human Video Read More »