
Editors Pick

Auto Added by WPeMatico

Meet S1-mini: Superwhisper’s 462 MB Open-Weights Text Normalizer That Turns Raw ASR Transcripts Into Clean Written Text

Superwhisper has released the S1 family of models: S1-Voice, S1-Language, and S1-mini. S1-Voice is a cloud speech-to-text model, and S1-Language is a cloud instruction-following model for cleanup and formatting. The one that is quite interesting outside the app is S1-mini, released with open weights on Hugging Face. S1-mini is a 0.6B text normalizer, not a […]
Meet S1-mini: Superwhisper’s 462 MB Open-Weights Text Normalizer That Turns Raw ASR Transcripts Into Clean Written Text Read More »

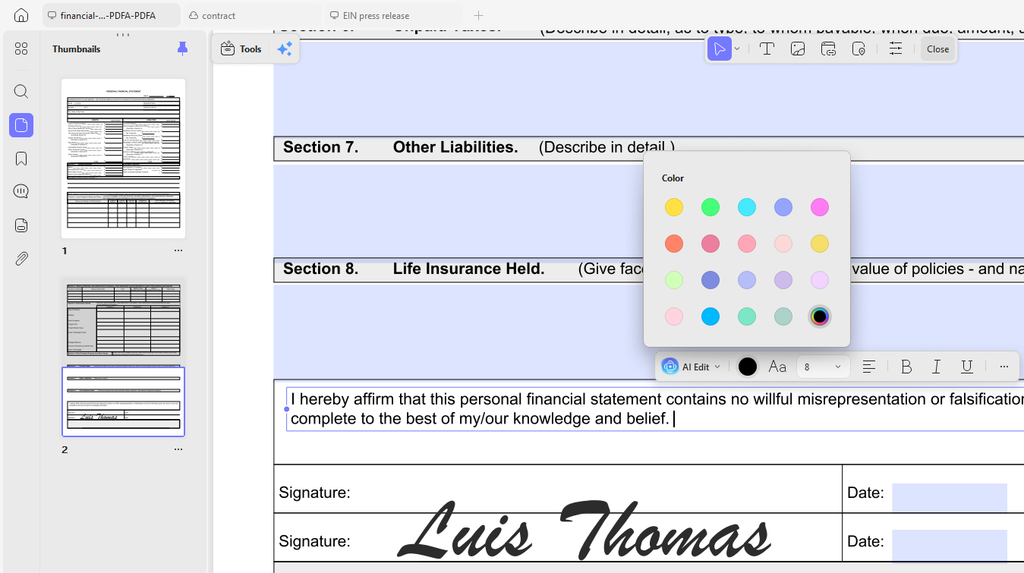
Meet UPDF: A Lightweight Adobe Alternative Built for the Agentic Era

PDFs sit at the end of almost every workflow. Contracts, invoices, research papers, scanned intake forms, manuals, and compliance filings all arrive as PDFs. The format is very good at freezing a layout. It is much worse at letting you change one number inside that layout. That gap has become more visible as language models

Meet UPDF: A Lightweight Adobe Alternative Built for the Agentic Era Read More »

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs

Liquid AI has released DSpark draft model checkpoints for three models in its LFM2.5 family: LFM2.5-1.2B-Instruct, LFM2.5-2.6B, and LFM2.5-8B-A1B. Each drafter adds a speculative decoding path to an existing target model. A roughly 300M-parameter draft proposes a block of nine candidate tokens, and the target model verifies the whole block in a single forward pass.

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs Read More »

Auditing Preference Biases and Fine-Tuning Language Models with Direct Preference Optimization on Anthropic HH-RLHF Using TRL and LoRA

In this tutorial, we design an end-to-end preference-learning workflow using the Anthropic HH-RLHF dataset and Direct Preference Optimization (DPO). We begin by preparing a robust Colab environment, loading and parsing chosen–rejected response pairs, and auditing the dataset for structural and length-based preference biases. We then run lexical shortcut diagnostics to determine whether surface-level linguistic patterns

Auditing Preference Biases and Fine-Tuning Language Models with Direct Preference Optimization on Anthropic HH-RLHF Using TRL and LoRA Read More »

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands

NVIDIA has released TensorRT Model Connect (TRTMC) in public preview, an open-source project that takes a supported Hugging Face or local checkpoint to end-to-end TensorRT inference in two commands. There is no intermediate ONNX export step. The build produces a versioned .bundle artifact that runs through native C++ task APIs, so inference can execute in

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands Read More »

Meet SAM (Sovereign Agent Mesh): A Zero-Config, Zero-Trust P2P Network for AI Agents

google/sam is not Segment Anything. SAM here means Sovereign Agent Mesh, an Apache-2.0 networking project for autonomous AI agents. The problem it targets is concrete. Agents now run across cloud servers, on-prem datacenters, laptops, Raspberry Pis and Android devices. Letting them share tools usually means exposing internal scripts, LLM endpoints or private APIs to the

Meet SAM (Sovereign Agent Mesh): A Zero-Config, Zero-Trust P2P Network for AI Agents Read More »

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas

Cartesia has released Sonic-3.6, the newest version of its real-time text-to-speech model. It arrives roughly three months after Sonic-3.5. The new change is naturalness, and this one is independently checkable. Sonic 3.6 now holds #1 on both Artificial Analysis speech leaderboards — 1,283 Elo on the Provider Voice board and 1,123 on the Controlled Voice

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas Read More »

Nous Research Ships Bot Mode for Hermes Agent, Turning Agent Profiles Into a Roster of Named Bots

Nous Research has shipped Bot Mode for Hermes Agent, its MIT-licensed open source agent. Bot Mode replaces the single-agent session list with a roster of named bots. Each bot is a real Hermes profile, with its own chat, memory, skills, and pinned model. Bots message each other through a persistent Agent Inbox and hand work

Nous Research Ships Bot Mode for Hermes Agent, Turning Agent Profiles Into a Roster of Named Bots Read More »

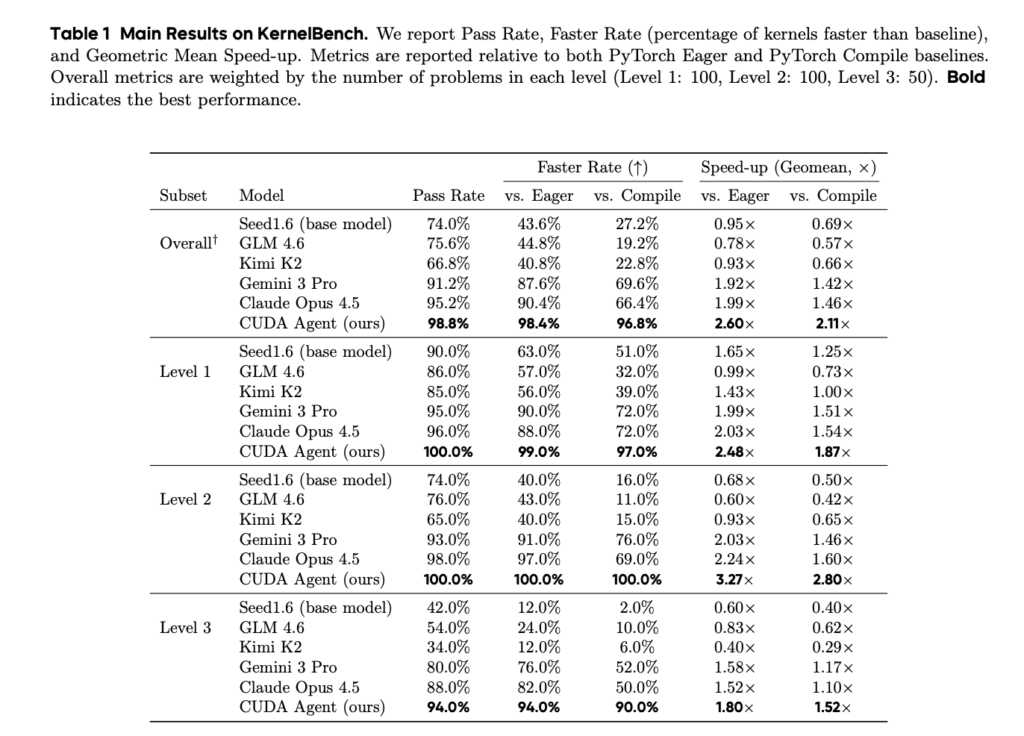
ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic RL System for CUDA Kernel Generation

ByteDance Seed and Tsinghua AIR have released CUDA Agent, an agentic reinforcement learning system that trains a large language model to write GPU kernels that beat a compiler. The gap it targets is narrow but stubborn: frontier models already produce correct CUDA, they just produce slow CUDA. On KernelBench, the base model Seed1.6 passes 74.0%

ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic RL System for CUDA Kernel Generation Read More »

MiniMax Releases MiniMax-Music3: An Open-Weights Music Model Generating Complete Five-Minute Songs From Lyrics and a Structured Caption

MiniMax released MiniMax-Music3, an open-weights text-to-music model. The model takes two separate inputs: lyrics carrying section tags, and a detailed music description. It returns a complete song of up to five minutes in a single generation, as 32 kHz, 16-bit stereo WAV. The architecture pairs a Hybrid-LM, an 8B Global LLM with a 0.6B Local

MiniMax Releases MiniMax-Music3: An Open-Weights Music Model Generating Complete Five-Minute Songs From Lyrics and a Structured Caption Read More »