Audio Language Model

Auto Added by WPeMatico

Inworld AI Releases TTS-1.5 For Realtime, Production Grade Voice Agents

Inworld AI has introduced Inworld TTS-1.5, an upgrade to its TTS-1 family that targets realtime voice agents with strict constraints on latency, quality, and cost. TTS-1.5 is described as the number top ranked text to speech system on Artificial Analysis and is designed to be more expressive and more stable than prior generations while remaining […]

Inworld AI Releases TTS-1.5 For Realtime, Production Grade Voice Agents Read More »
How to Design a Fully Streaming Voice Agent with End-to-End Latency Budgets, Incremental ASR, LLM Streaming, and Real-Time TTS

In this tutorial, we build an end-to-end streaming voice agent that mirrors how modern low-latency conversational systems operate in real time. We simulate the complete pipeline, from chunked audio input and streaming speech recognition to incremental language model reasoning and streamed text-to-speech output, while explicitly tracking latency at every stage. By working with strict latency

How to Design a Fully Streaming Voice Agent with End-to-End Latency Budgets, Incremental ASR, LLM Streaming, and Real-Time TTS Read More »

NVIDIA Releases PersonaPlex-7B-v1: A Real-Time Speech-to-Speech Model Designed for Natural and Full-Duplex Conversations

NVIDIA Researchers released PersonaPlex-7B-v1, a full duplex speech to speech conversational model that targets natural voice interactions with precise persona control. From ASR→LLM→TTS to a single full duplex model Conventional voice assistants usually run a cascade. Automatic Speech Recognition (ASR) converts speech to text, a language model generates a text answer, and Text to Speech

NVIDIA Releases PersonaPlex-7B-v1: A Real-Time Speech-to-Speech Model Designed for Natural and Full-Duplex Conversations Read More »

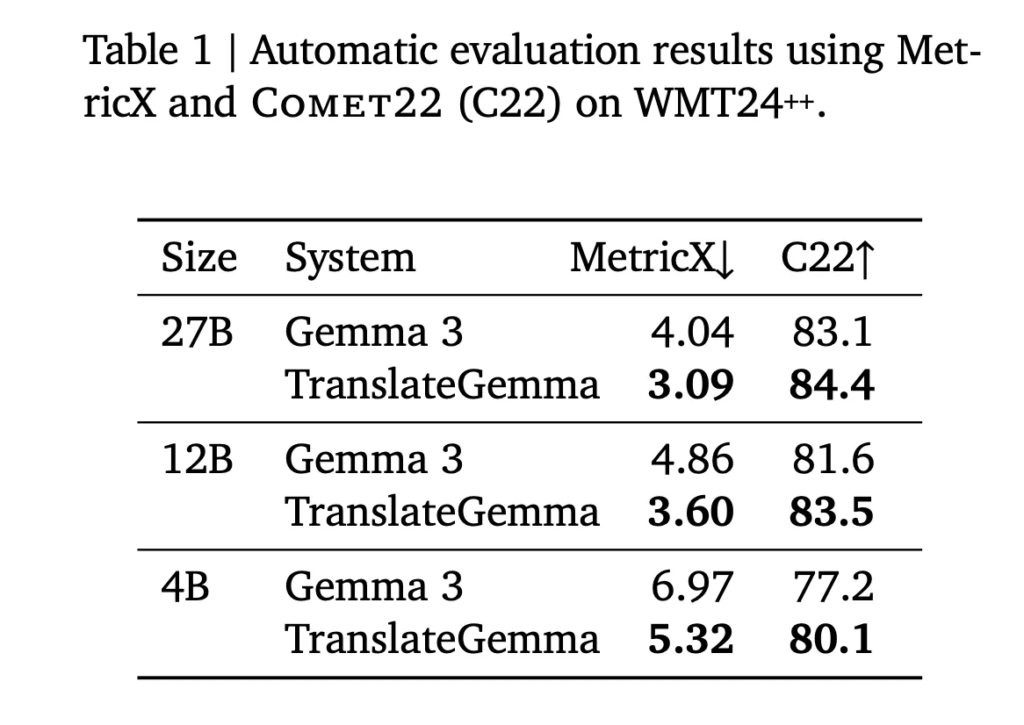
Google AI Releases TranslateGemma: A New Family of Open Translation Models Built on Gemma 3 with Support for 55 Languages

Google AI has released TranslateGemma, a suite of open machine translation models built on Gemma 3 and targeted at 55 languages. The family comes in 4B, 12B and 27B parameter sizes. It is designed to run across devices from mobile and edge hardware to laptops and a single H100 GPU or TPU instance in the

Google AI Releases TranslateGemma: A New Family of Open Translation Models Built on Gemma 3 with Support for 55 Languages Read More »

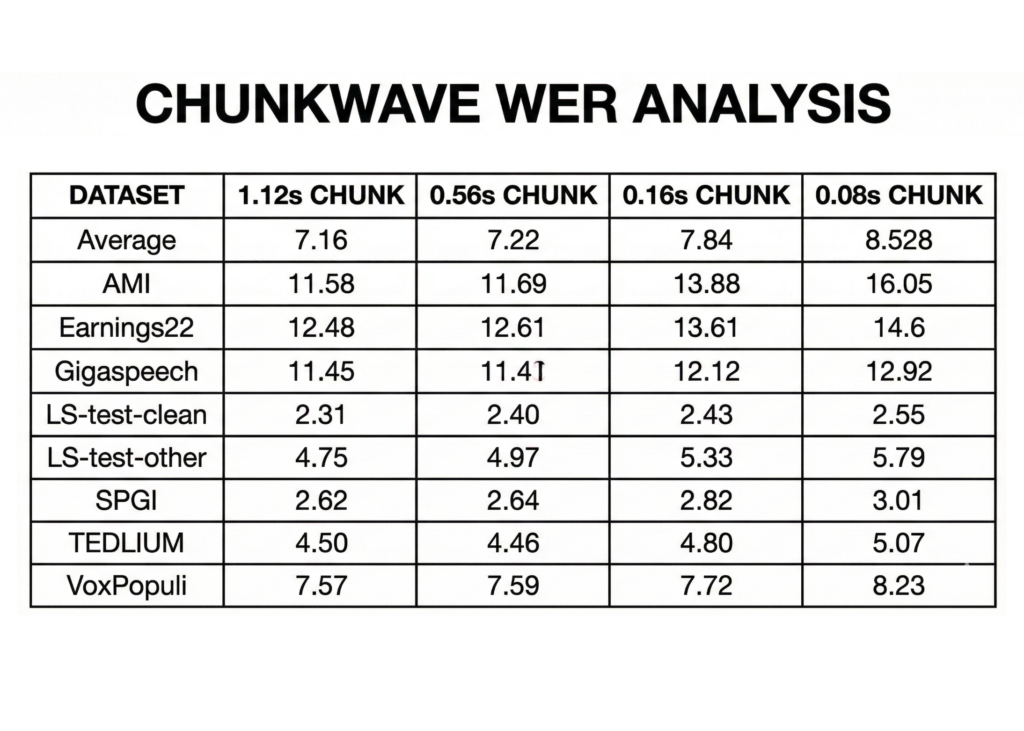
NVIDIA AI Released Nemotron Speech ASR: A New Open Source Transcription Model Designed from the Ground Up for Low-Latency Use Cases like Voice Agents

NVIDIA has just released its new streaming English transcription model (Nemotron Speech ASR) built specifically for low latency voice agents and live captioning. The checkpoint nvidia/nemotron-speech-streaming-en-0.6b on Hugging Face combines a cache aware FastConformer encoder with an RNNT decoder, and is tuned for both streaming and batch workloads on modern NVIDIA GPUs. Model design, architecture

NVIDIA AI Released Nemotron Speech ASR: A New Open Source Transcription Model Designed from the Ground Up for Low-Latency Use Cases like Voice Agents Read More »

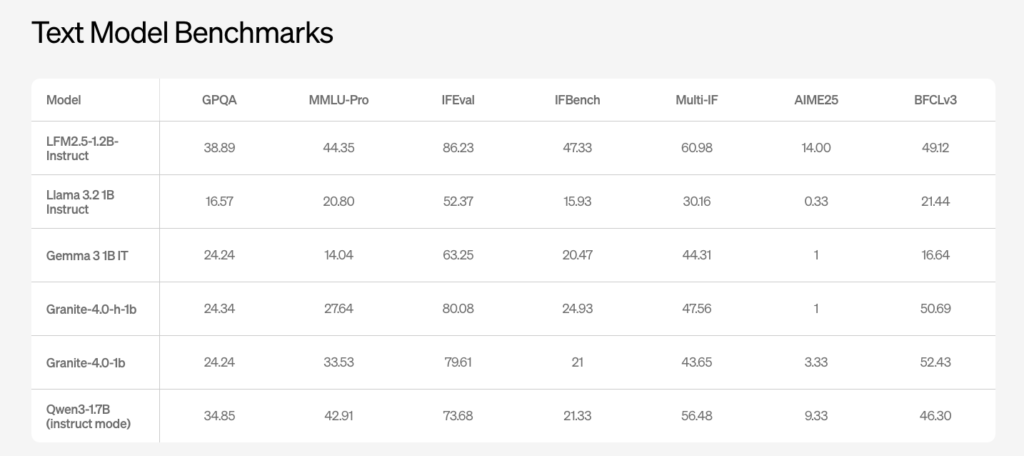
Liquid AI Releases LFM2.5: A Compact AI Model Family For Real On Device Agents

Liquid AI has introduced LFM2.5, a new generation of small foundation models built on the LFM2 architecture and focused at on device and edge deployments. The model family includes LFM2.5-1.2B-Base and LFM2.5-1.2B-Instruct and extends to Japanese, vision language, and audio language variants. It is released as open weights on Hugging Face and exposed through the

Liquid AI Releases LFM2.5: A Compact AI Model Family For Real On Device Agents Read More »

Tencent Researchers Release Tencent HY-MT1.5: A New Translation Models Featuring 1.8B and 7B Models Designed for Seamless on-Device and Cloud Deployment

Tencent Hunyuan researchers have released HY-MT1.5, a multilingual machine translation family that targets both mobile devices and cloud systems with the same training recipe and metrics. HY-MT1.5 consists of 2 translation models, HY-MT1.5-1.8B and HY-MT1.5-7B, supports mutual translation across 33 languages with 5 ethnic and dialect variations, and is available on GitHub and Hugging Face

Tencent Researchers Release Tencent HY-MT1.5: A New Translation Models Featuring 1.8B and 7B Models Designed for Seamless on-Device and Cloud Deployment Read More »

Meta AI Open-Sourced Perception Encoder Audiovisual (PE-AV): The Audiovisual Encoder Powering SAM Audio And Large Scale Multimodal Retrieval

Meta researchers have introduced Perception Encoder Audiovisual, PEAV, as a new family of encoders for joint audio and video understanding. The model learns aligned audio, video, and text representations in a single embedding space using large scale contrastive training on about 100M audio video pairs with text captions. From Perception Encoder to PEAV Perception Encoder,

Meta AI Open-Sourced Perception Encoder Audiovisual (PE-AV): The Audiovisual Encoder Powering SAM Audio And Large Scale Multimodal Retrieval Read More »

Meta AI Releases SAM Audio: A State-of-the-Art Unified Model that Uses Intuitive and Multimodal Prompts for Audio Separation

Meta has released SAM Audio, a prompt driven audio separation model that targets a common editing bottleneck, isolating one sound from a real world mix without building a custom model per sound class. Meta released 3 main sizes, sam-audio-small, sam-audio-base, and sam-audio-large. The model is available to download and to try in the Segment Anything

Meta AI Releases SAM Audio: A State-of-the-Art Unified Model that Uses Intuitive and Multimodal Prompts for Audio Separation Read More »

StepFun AI Releases Step-Audio-R1: A New Audio LLM that Finally Benefits from Test Time Compute Scaling

Why do current audio AI models often perform worse when they generate longer reasoning instead of grounding their decisions in the actual sound. StepFun research team releases Step-Audio-R1, a new audio LLM designed for test time compute scaling, address this failure mode by showing that the accuracy drop with chain of thought is not an

StepFun AI Releases Step-Audio-R1: A New Audio LLM that Finally Benefits from Test Time Compute Scaling Read More »