Applications

Auto Added by WPeMatico

Nous Research Ships Hermes Agent Profile Builder: Identity, Model, Skills, and MCP Servers in One Dashboard Flow

Nous Research has shipped a Profile Builder for Hermes Agent. It lives inside the project’s local web dashboard. Standing up a distinct agent used to mean several CLI steps. The builder now walks you through one guided flow. In that flow you define an agent’s identity. You pick a model and provider. You choose built-in […]
Nous Research Ships Hermes Agent Profile Builder: Identity, Model, Skills, and MCP Servers in One Dashboard Flow Read More »

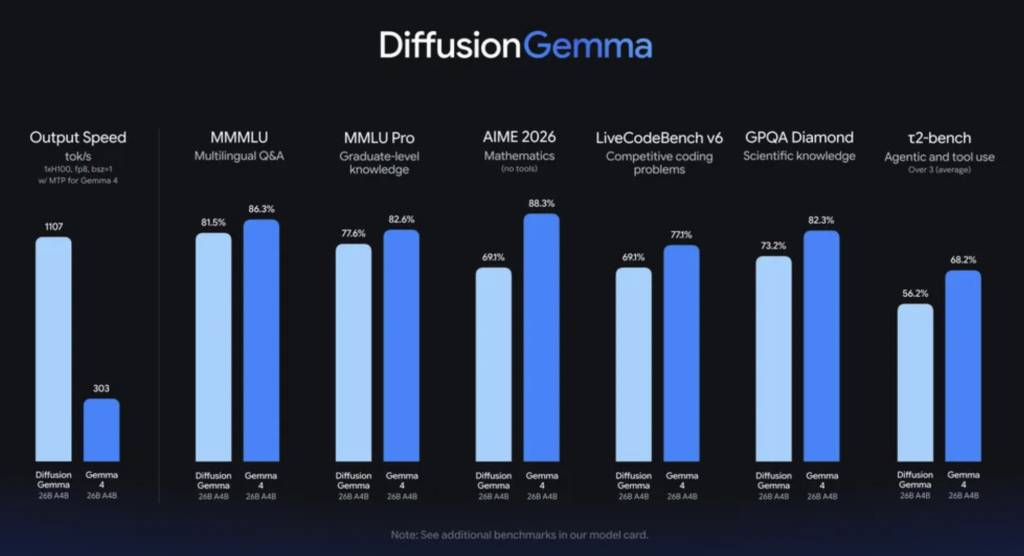
Google AI Releases DiffusionGemma, a 26B MoE Open Model Using Text Diffusion for Up to 4x Faster Generation

Google AI team including the Google DeepMind researchers have just released DiffusionGemma, an experimental open model for text generation. It uses text diffusion instead of standard autoregressive decoding. The model ships under a permissive Apache 2.0 license. Google positions it for devs and researchers exploring speed-critical, interactive local workflows. Examples include in-line editing, rapid iteration,

Google AI Releases DiffusionGemma, a 26B MoE Open Model Using Text Diffusion for Up to 4x Faster Generation Read More »

Top AI Coding Agents and Development Platforms in 2026: Atoms, Devin, Windsurf, Cursor, Warp, and More Compared

Software development has changed. Engineers no longer type most code by hand. They describe intent, and AI agents do the work. Modern tools plan tasks, edit across files, run tests, and open pull requests. Many now ship to production with limited supervision. No single tool fits every need. This guide covers the AI coding agents

Top AI Coding Agents and Development Platforms in 2026: Atoms, Devin, Windsurf, Cursor, Warp, and More Compared Read More »

Anthropic Releases Claude Fable 5 and Claude Mythos 5: Same Underlying Model, Different Safeguards, New Mythos-Class Tier

Anthropic released two models on June 9, 2026: Claude Fable 5 and Claude Mythos 5. Both belong to a tier called “Mythos-class.” This tier sits above the Opus class in capability. Fable 5 is the version claimed to be made safe for general use. Mythos 5 is the same model with some safeguards lifted, kept

Anthropic Releases Claude Fable 5 and Claude Mythos 5: Same Underlying Model, Different Safeguards, New Mythos-Class Tier Read More »

NVIDIA cuTile Python Tutorial: Building Tiled GPU Kernels for Vector Addition, Matrix Addition, and Matrix Multiplication in Colab

In this tutorial, we implement an advanced hands-on workflow for NVIDIA cuTile Python, a tile-based GPU programming interface for writing efficient CUDA-style kernels directly in Python. We start by preparing a Colab-friendly environment, checking the available GPU, driver, CUDA, and cuTile installations before running any kernel code. We then build tiled examples for vector addition,

NVIDIA cuTile Python Tutorial: Building Tiled GPU Kernels for Vector Addition, Matrix Addition, and Matrix Multiplication in Colab Read More »

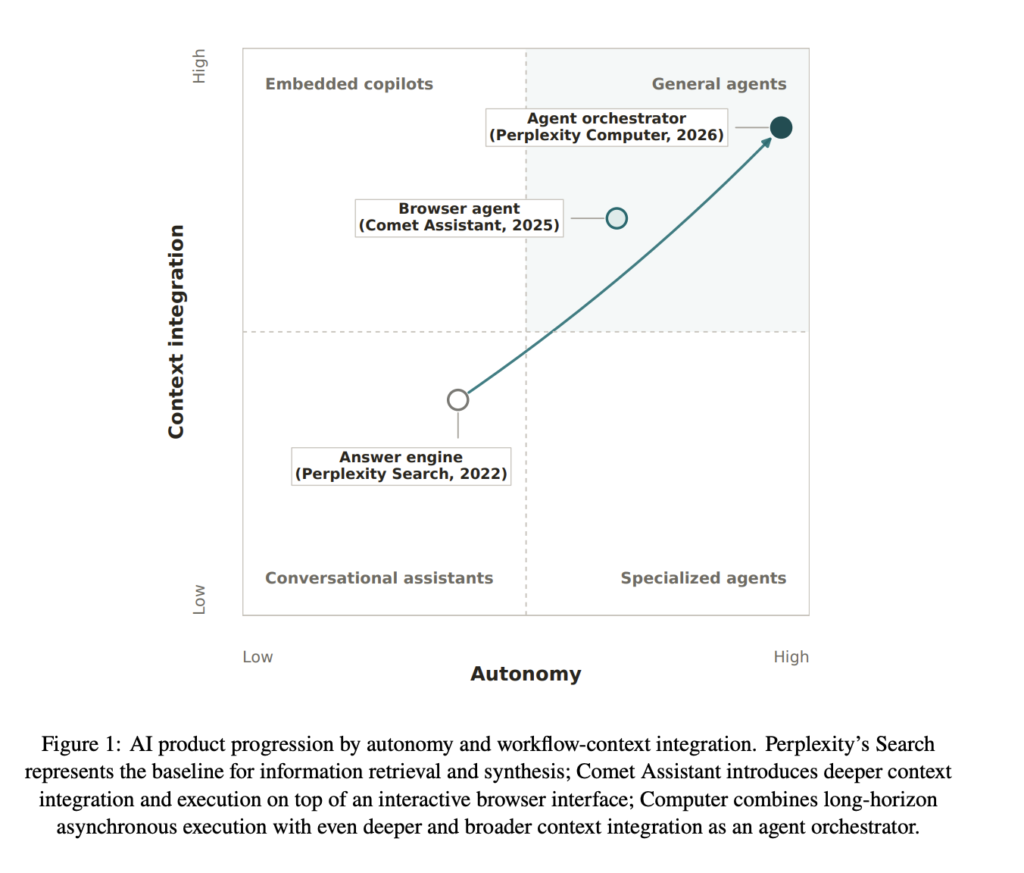
A New Study from Harvard and Perplexity Finds AI Agents Perform 26 Minutes of Autonomous Work per Session vs 33 Seconds for Search

A new working research from Perplexity and Harvard offers field evidence on what AI agents do to knowledge work. It draws on production data from two Perplexity products: Search and Computer. The setup is a natural comparison. Search is a conversational answer engine. Computer is an agent that plans and executes tasks end to end.

A New Study from Harvard and Perplexity Finds AI Agents Perform 26 Minutes of Autonomous Work per Session vs 33 Seconds for Search Read More »

Xiaomi MiMo and TileRT Push a 1-Trillion-Parameter Model Past 1000 Tokens Per Second on Commodity GPUs

Inference speed is becoming a competitive metric for large language models. Xiaomi’s MiMo team just released MiMo-V2.5-Pro-UltraSpeed, built in collaboration with the TileRT systems group. It decodes faster than 1000 tokens per second on a 1-trillion-parameter model. Xiaomi team describes this as a first at trillion-parameter scale. Demos show generation peaks near 1200 tokens per

Xiaomi MiMo and TileRT Push a 1-Trillion-Parameter Model Past 1000 Tokens Per Second on Commodity GPUs Read More »

Building Reflective Prompt Optimization with GEPA: Multi-Component Prompts, Structured Feedback, and Held-Out Validation

In this tutorial, we use GEPA as a reflective prompt-evolution framework to improve the way a language model solves arithmetic word problems. We begin with a weak seed prompt, create a small deterministic benchmark, define a structured evaluator, and pass actionable feedback to GEPA so it can understand why a candidate prompt fails. We also

Building Reflective Prompt Optimization with GEPA: Multi-Component Prompts, Structured Feedback, and Held-Out Validation Read More »

Best 21 Low-Code and No-Code AI Tools in 2026

Low-code and no-code platforms have moved from simple drag-and-drop builders to AI-native development environments. In 2026, most of them ship a built-in assistant that turns a text prompt into a working app, agent, or automation. This list covers 21 tools that AI practitioners use today, grouped by what they do best. Each tool name links

Best 21 Low-Code and No-Code AI Tools in 2026 Read More »

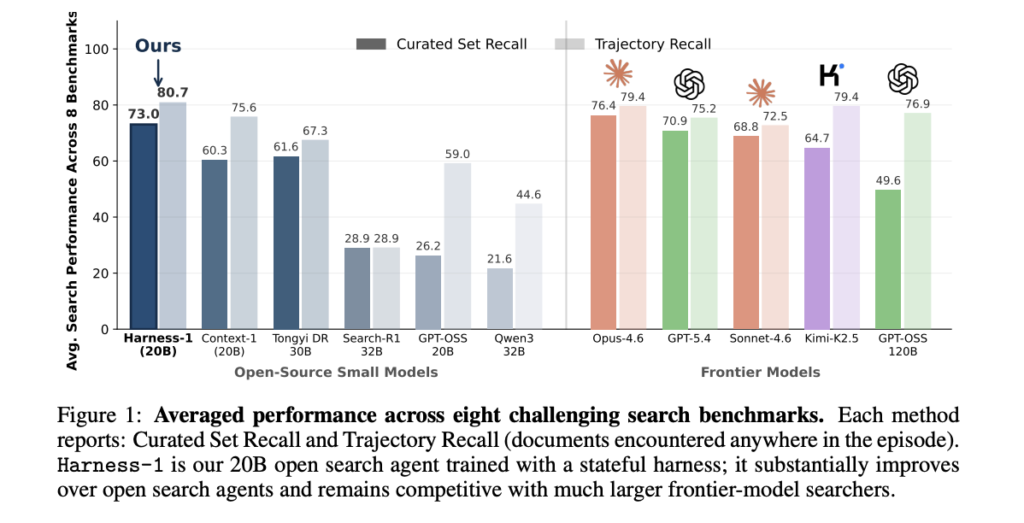
Meet Harness-1: A 20B Retrieval Subagent Trained With Reinforcement Learning Inside a Stateful Search Harness on gpt-oss-20b

Most search agents are trained as policies over a growing transcript. The model decides how to search. It must also remember what it saw, which evidence matters, and which claims it checked. A team of researchers from University of Illinois Urbana-Champaign, UC Berkeley, and Chroma argues this asks too much. Reinforcement learning ends up optimizing

Meet Harness-1: A 20B Retrieval Subagent Trained With Reinforcement Learning Inside a Stateful Search Harness on gpt-oss-20b Read More »