Applications

Auto Added by WPeMatico

Ant Group’s Robbyant Unveils LingBot-VA 2.0: A Causal Video-Action Model Built Natively for Physical AI

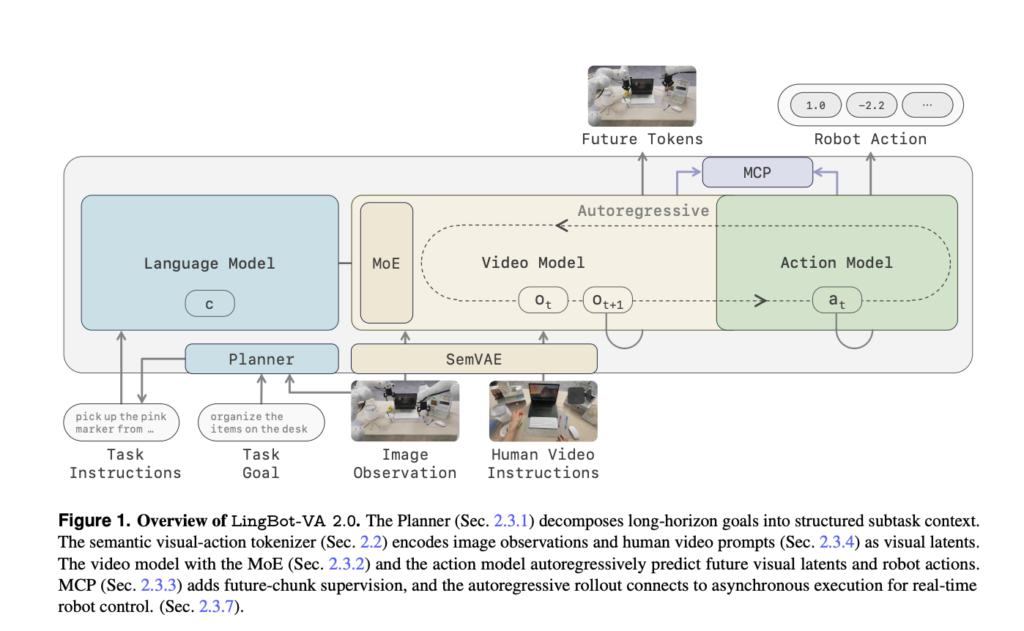
Robbyant, the embodied AI unit inside Ant Group, has released the LingBot-VA 2.0.The first embodied-native foundation model. It describes a video-action foundation model for generalist robot manipulation. The research team pretrains the whole stack for embodiment instead of fine-tuning a video generator. What is LingBot-VA 2.0? Most video-action models reuse two components built for digital […]

Ant Group’s Robbyant Unveils LingBot-VA 2.0: A Causal Video-Action Model Built Natively for Physical AI Read More »

▶

Kyutai Releases MuScriptor: An Open-Weight Decoder-Only Transformer for Multi-Instrument Music Transcription to MIDI

Automatic Music Transcription (AMT) converts an audio recording into symbolic notes, usually MIDI. Single-instrument transcription already works reasonably well. However, transcribing a full multi-instrument mix stays difficult. Kyutai and Mirelo team now release MuScriptor to close that gap. It is an open-weight model trained on real, multi-instrument recordings across many genres. This article explains how

Kyutai Releases MuScriptor: An Open-Weight Decoder-Only Transformer for Multi-Instrument Music Transcription to MIDI Read More »

📊

How to Build a T4-Friendly Autonomous Data Science Agent with DeepAnalyze-8B, Sandboxed Code Execution, and Iterative Analysis

In this tutorial, we build an autonomous data science agent around DeepAnalyze-8B and run it. We begin by preparing a stable runtime, installing the required machine-learning dependencies, and loading the DeepAnalyze tokenizer and model in 4-bit mode to keep the workflow practical on limited GPU memory. We then create a sandboxed execution environment that allows

How to Build a T4-Friendly Autonomous Data Science Agent with DeepAnalyze-8B, Sandboxed Code Execution, and Iterative Analysis Read More »

Google Research Introduces SensorFM: A Wearable Health Foundation Model Pretrained on One Trillion Minutes of Sensor Data

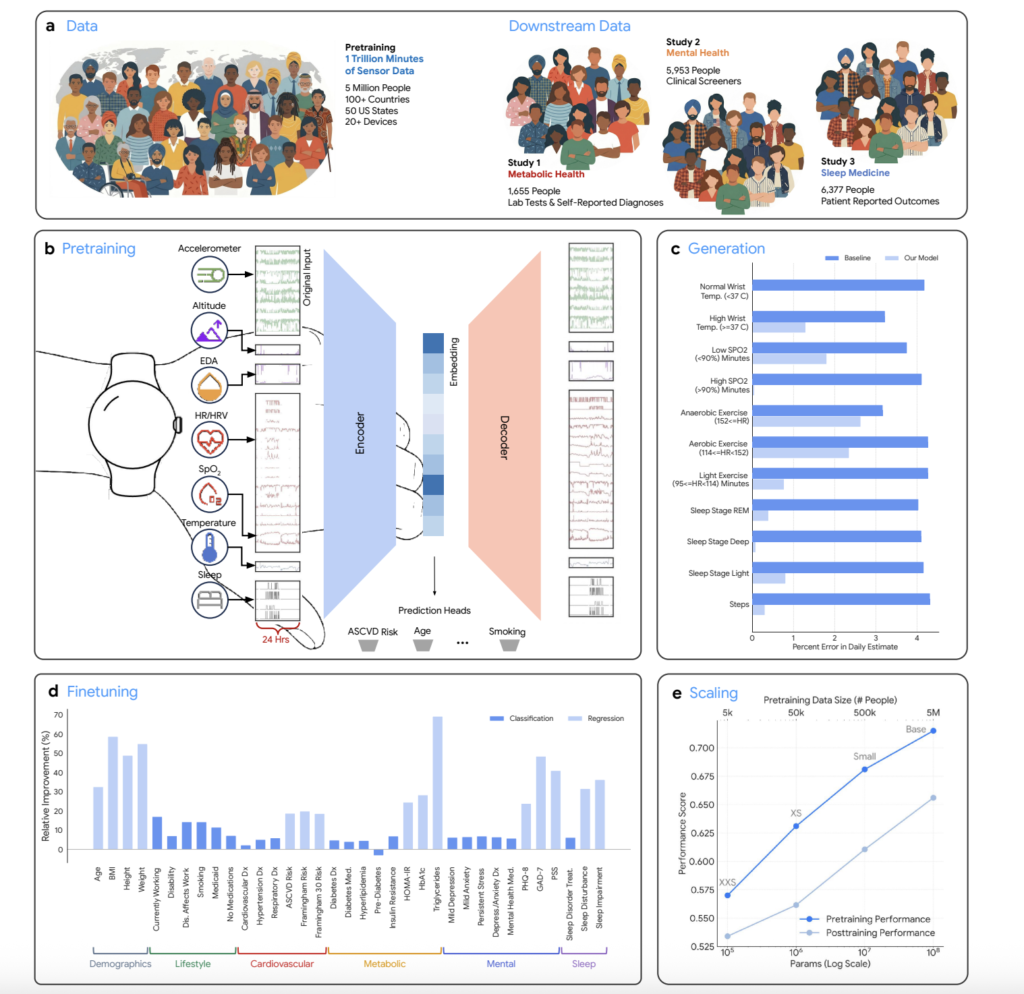
Most wearable health models are built one outcome at a time. That approach breaks down at thirty-five endpoints. Labels are expensive and retrospective annotation is infeasible. Google Research introduced SensorFM, a foundation model for wearable health pre-trained on more than 1 trillion minutes of sensor data from 5 million people. https://arxiv.org/pdf/2605.22759 What is SensorFM? SensorFM

Google Research Introduces SensorFM: A Wearable Health Foundation Model Pretrained on One Trillion Minutes of Sensor Data Read More »

Meet LingBot-World-Infinity: An Open Causal World Model With An Agentic Harness

Robbyant, Ant Group’s embodied-intelligence unit, has released LingBot-World-Infinity (LingBot-World 2.0). It is a causal video generation model that behaves as an interactive world simulator. It is how the team attacks two failure modes: long-horizon drift and interactive latency. What is LingBot-World-Infinity? An interactive world model generates video frame by frame, conditioned on a stream of

Meet LingBot-World-Infinity: An Open Causal World Model With An Agentic Harness Read More »

Meta Superintelligence Labs Releases Muse Spark 1.1: A Multimodal Reasoning Model for Agentic Tasks on Meta Model API

Today, Meta Superintelligence Labs released Muse Spark 1.1. Alongside it, Meta opened a public preview of the Meta Model API. That second part is the structural change. Meta’s models previously reached developers mainly as open weights. Muse Spark 1.1 is closed, hosted, and metered per token. So the question is narrow. Where does it belong

Meta Superintelligence Labs Releases Muse Spark 1.1: A Multimodal Reasoning Model for Agentic Tasks on Meta Model API Read More »

OpenAI Releases GPT-5.6 (Sol, Terra, Luna): A Three-Tier Model Family With Programmatic Tool Calling in the Responses API

OpenAI just moved the GPT-5.6 family to general availability, following a limited preview. The release ships three models rather than one. Sol is the flagship, Terra is the balanced everyday tier, and Luna is the most cost-efficient. To sum up GPT-5.6 ships three tiers — Sol, Terra, Luna — priced from $1/$6 to $5/$30 per

OpenAI Releases GPT-5.6 (Sol, Terra, Luna): A Three-Tier Model Family With Programmatic Tool Calling in the Responses API Read More »

Meet Nemotron Labs 3 Puzzle 75B A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput

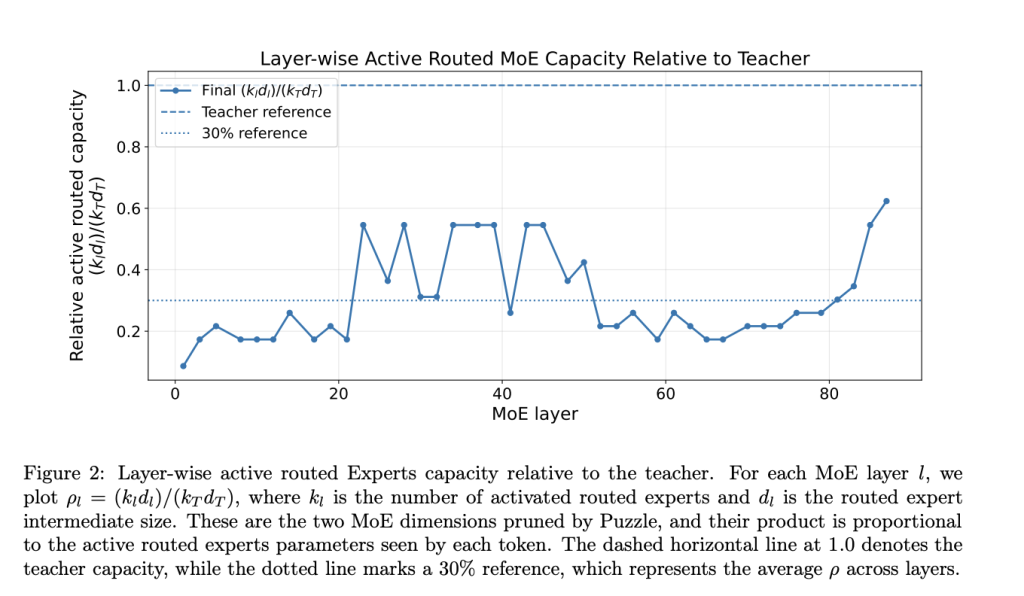
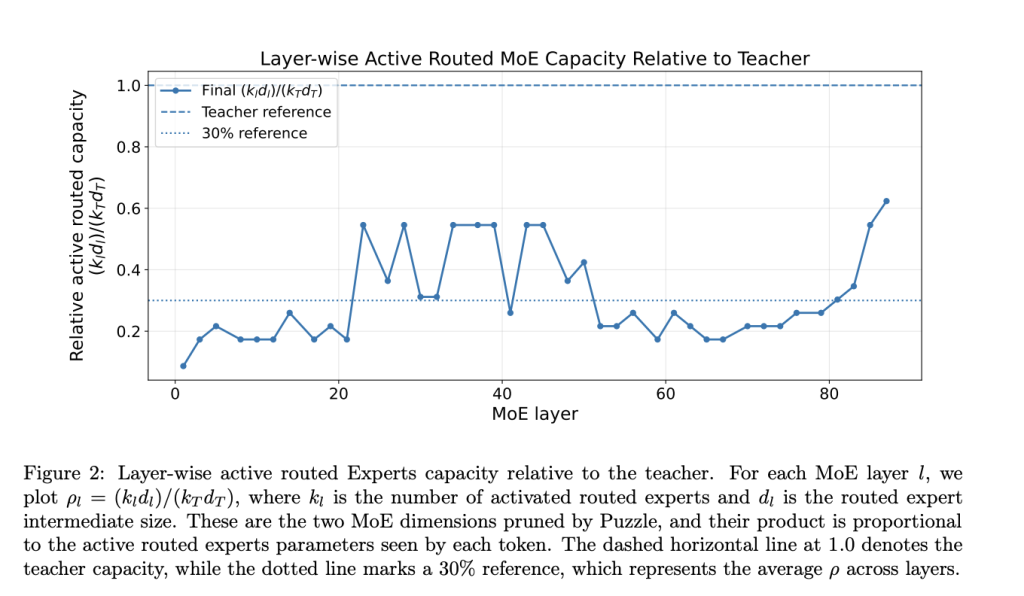
Large hybrid MoE models like Nemotron-3-Super are accurate but expensive to serve. Their active parameters, KV cache, and Mamba state cap how many users a node can hold at a given per-user token rate. NVIDIA AI team has released Nemotron-Labs-3-Puzzle-75B-A9B, a compressed variant of Nemotron-3-Super. The parent model has 120.7B total and 12.8B active parameters.

Meet Nemotron Labs 3 Puzzle 75B A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput Read More »

NVIDIA Releases Nemotron-Labs-3-Puzzle-75B-A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput at Matched User Throughput

Large hybrid MoE models like Nemotron-3-Super are accurate but expensive to serve. Their active parameters, KV cache, and Mamba state cap how many users a node can hold at a given per-user token rate. NVIDIA AI team has released Nemotron-Labs-3-Puzzle-75B-A9B, a compressed variant of Nemotron-3-Super. The parent model has 120.7B total and 12.8B active parameters.

NVIDIA Releases Nemotron-Labs-3-Puzzle-75B-A9B: A Compressed Hybrid MoE LLM Delivering 2.03x Server Throughput at Matched User Throughput Read More »

Datalab Lift vs the Field: How a 9B Schema-First Extractor Compares with NuExtract3, LlamaExtract, Marker, and Docling

Datalab’s Lift is a focused document extraction tool with a specific promise: give it a PDF or image plus a JSON Schema, and it returns schema-shaped JSON directly. Instead of converting a document to Markdown first and then asking another model to extract fields, Lift reads rendered page images and attempts to emit the final

Datalab Lift vs the Field: How a 9B Schema-First Extractor Compares with NuExtract3, LlamaExtract, Marker, and Docling Read More »