Applications

Auto Added by WPeMatico

How to Secure AI Agents, MCP Servers, and LLM Apps in Production

Agents, MCP integrations, and LLM-powered applications are entering codebases faster than most security programs can track them. Mend.io’s new practitioner guide, ‘Securing AI agents, MCP servers & LLM apps: A practical framework’, targets that gap. It is organized around three moves: see what matters, fix what matters faster, protect AI in production and ships seven […]

How to Secure AI Agents, MCP Servers, and LLM Apps in Production Read More »
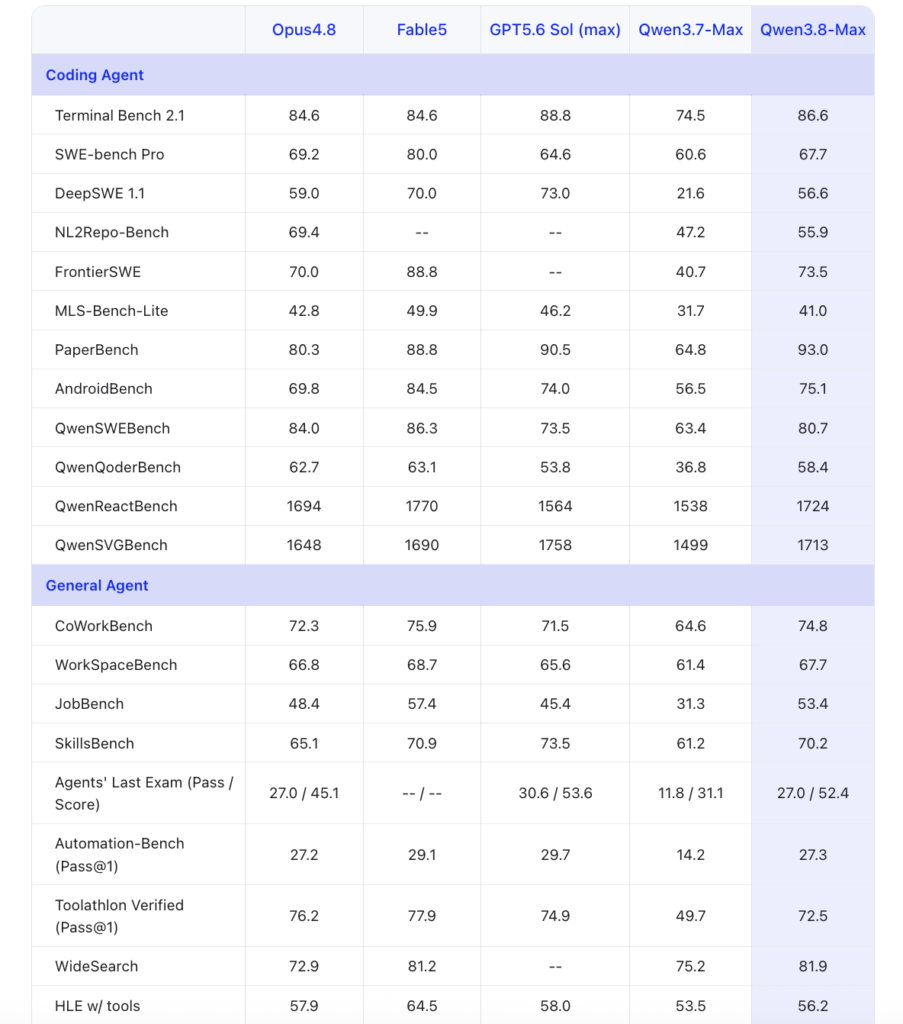
Alibaba Qwen Releases Qwen3.8-Max: A 2.4 Trillion Parameter MoE Model and the Most Capable One in the Qwen Family to Date

Alibaba’s Qwen team has made Qwen3.8-Max broadly available and confirmed that its open weights ship next week. A second checkpoint, Qwen3.8-27B, is also going open-weights. Qwen3.8-Max is a 2.4-trillion-parameter mixture-of-experts model. It accepts text, image and video as input and returns text. Is it deployable Yes, but the deployable surface depends on which artifact you

Alibaba Qwen Releases Qwen3.8-Max: A 2.4 Trillion Parameter MoE Model and the Most Capable One in the Qwen Family to Date Read More »

Onton Releases Ontology 1: A Neurosymbolic Search Model That is 2.7x More Accurate than the World’s Best E-commerce Search Engines

Onton, a San Francisco-based search and discovery company, has released Ontology 1, a neurosymbolic model for complex, conversational, multimodal product search. On a 90-query benchmark scored by three independent LLM judges, Ontology 1 reached a mean precision@10 of 0.630, against 0.543 for Google Shopping and 0.469 for Amazon. It did this while indexing roughly 1%

Onton Releases Ontology 1: A Neurosymbolic Search Model That is 2.7x More Accurate than the World’s Best E-commerce Search Engines Read More »

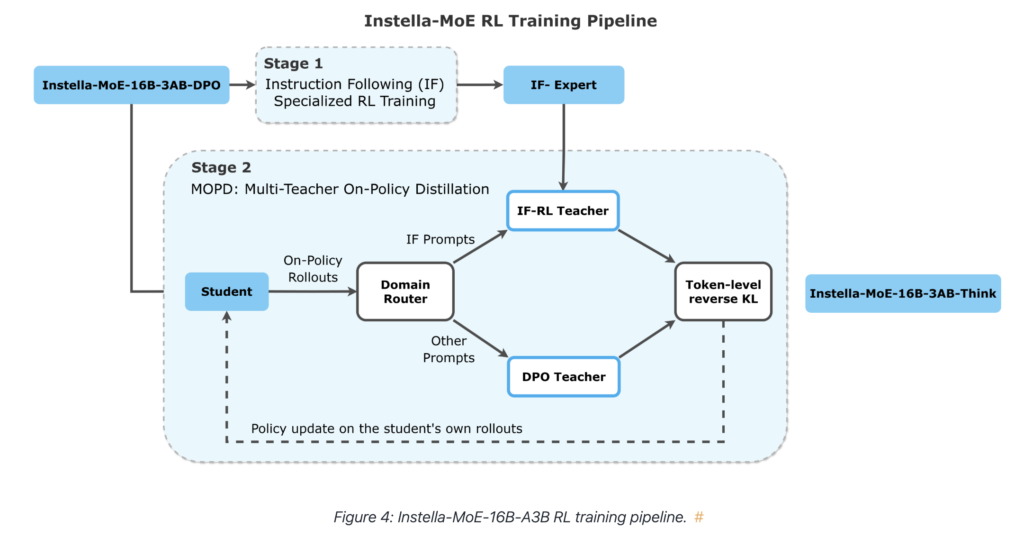
AMD Releases Instella-MoE-16B-A3B: A Fully Open Mixture-of-Experts LLM With 2.8B Active Parameters Trained On Instinct GPUs

AMD released Instella-MoE-16B-A3B, a fully open Mixture-of-Experts language model trained from scratch on Instinct MI300X and MI325X GPUs. The model holds 16B total parameters but activates only 2.8B per token. AMD is publishing weights from every training stage, along with data mixtures, training configs, and inference code. Two systems-level choices carry the release: Gated Multi-head

AMD Releases Instella-MoE-16B-A3B: A Fully Open Mixture-of-Experts LLM With 2.8B Active Parameters Trained On Instinct GPUs Read More »

📝

Supabase Releases Evals: an Open Source Benchmark That Scores Claude Code, Codex and OpenCode on Real Supabase Tasks

Supabase has open sourced Supabase Evals, its benchmark and framework for testing how well AI agents build using Supabase. It runs coding agents including Claude Code, Codex, and OpenCode against real tasks, such as building a schema, debugging a failed Edge Function, or fixing a broken RLS policy, then scores the result. It powers the

Supabase Releases Evals: an Open Source Benchmark That Scores Claude Code, Codex and OpenCode on Real Supabase Tasks Read More »

MiniMax Releases MiniMax H3: An Omni-Modal Video Model That Generates 15-Second 2K Clips With Native Stereo Audio

MiniMax releases MiniMax H3, a general-purpose multimodal generation model. MiniMax H3 is not a text-to-video model with add-ons. MiniMax describes it as a general-purpose multimodal generation model that reads text, images, video, and audio as one unified context and returns video with native stereo sound. The mains specs include: 2K output, 4–15 seconds, integer durations

MiniMax Releases MiniMax H3: An Omni-Modal Video Model That Generates 15-Second 2K Clips With Native Stereo Audio Read More »

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains

DeepSeek published DeepSeek-V4-Flash-0731 on Hugging Face and moved the official V4-Flash API into public beta on July 31, 2026. The model card is explicit that this is the official release superseding the preview, and that the architecture and size are unchanged. The gains come from re-post-training, not a new design. The checkpoint ships with the

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains Read More »

LingBot-Map Tutorial: GPU-Aware Inference and Point Cloud Export

In this tutorial, we implement an end-to-end streaming 3D reconstruction pipeline with LingBot-Map. We begin by configuring the input source, reconstruction settings, checkpoint selection, and output controls, then probe the available GPU and automatically tune frame limits, camera iterations, scale frames, and KV-cache parameters according to the detected VRAM. We install the repository and its

LingBot-Map Tutorial: GPU-Aware Inference and Point Cloud Export Read More »

JetBrains Open-Sources KotlinLLM: Smart Macros That Generate Kotlin Source Code at Runtime and Hot-Reload It Through JDI

JetBrains Research Open-Sources KotlinLLM. KotlinLLM is an IntelliJ IDEA plugin for Kotlin/JVM projects that adds a language feature called Smart macros. A Smart macro is a regular Kotlin function call whose body is generated Kotlin code. The public API is deliberately small. asLlm<F, T>(from, hint) converts an input of type F into a typed value

JetBrains Open-Sources KotlinLLM: Smart Macros That Generate Kotlin Source Code at Runtime and Hot-Reload It Through JDI Read More »

Google DeepMind Ships Three Physical AI Models For Whole Body Control, Dexterity And Multi Robot Collaboration

Google DeepMind has released Gemini Robotics 2, the intelligence layer for its next generation of robots. The release moves the stack past table-top manipulation into whole body control, five finger dexterity and multi robot teamwork. It ships as three separate models with three different access tiers. Most robots today are pre-programmed or tele-operated for narrow,

Google DeepMind Ships Three Physical AI Models For Whole Body Control, Dexterity And Multi Robot Collaboration Read More »