AI Infrastructure

Auto Added by WPeMatico

DeepSeek Releases DSpark, a Speculative Decoding Framework That Accelerates DeepSeek-V4 Per-User Generation 60–85% Over MTP-1

DeepSeek released DSpark, a speculative decoding framework, with open-source checkpoints and training code. It is a serving optimization, not a new model. The checkpoints DeepSeek-V4-Pro-DSpark and DeepSeek-V4-Flash-DSpark reuse the existing V4 weights, with a draft module attached. The DeepSeek research team also open-sourced DeepSpec, an MIT-licensed codebase for training and evaluating speculative decoding drafters. The […]
DeepSeek Releases DSpark, a Speculative Decoding Framework That Accelerates DeepSeek-V4 Per-User Generation 60–85% Over MTP-1 Read More »

Meet container: Apple’s Open-Source Swift Tool for Running Linux Containers as Lightweight VMs on Apple Silicon

Apple research team recently released the container project. It is an open-source command-line tool written in Swift. It creates and runs Linux containers as lightweight virtual machines on a Mac. The project ships under the Apache 2.0 license and targets Apple silicon. Containers are how you ship reproducible environments from a laptop to a datacenter.

Meet container: Apple’s Open-Source Swift Tool for Running Linux Containers as Lightweight VMs on Apple Silicon Read More »

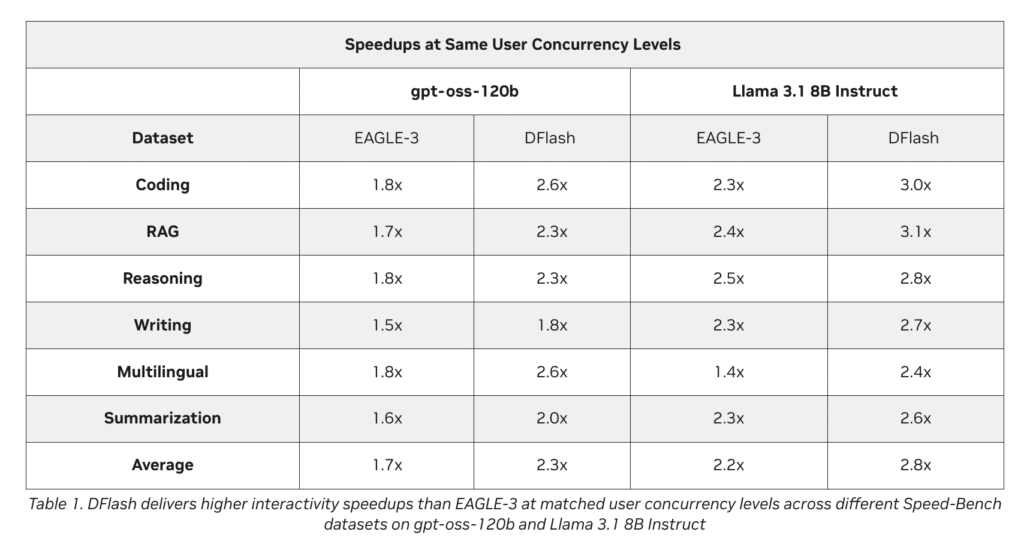
DFlash Speculative Decoding Drafts Whole Token Blocks in Parallel for Up to 15x Higher Throughput on NVIDIA Blackwell

Autoregressive large language models generate text one token at a time. Each token waits for the one before it. This serial loop leaves modern GPUs underused and keeps inference slow. The cost grows worse with long Chain-of-Thought reasoning models. Their lengthy outputs make latency the dominant part of generation. Speculative decoding is the standard fix.

DFlash Speculative Decoding Drafts Whole Token Blocks in Parallel for Up to 15x Higher Throughput on NVIDIA Blackwell Read More »

↔

Prime Intellect Releases prime-rl 0.6.0 to Train Trillion-Parameter MoE Models on Agentic RL Workloads

Prime Intellect has released prime-rl version 0.6.0. The framework targets reinforcement learning on trillion-parameter Mixture-of-Experts (MoE) models. It focuses on heavy agentic workloads, like long-horizon software-engineering tasks. The research team trained GLM-5 on SWE tasks at up to 131k sequence length. Step times stayed under five minutes. The batch size was 256 rollouts. The run

Prime Intellect Releases prime-rl 0.6.0 to Train Trillion-Parameter MoE Models on Agentic RL Workloads Read More »

Sakana AI Launches Sakana Fugu: An Orchestration Model That Routes Tasks Across a Swappable Pool of Frontier LLMs

Today, Sakana AI launched Sakana Fugu. It is a multi-agent orchestration system that behaves like one model. You send a request to a single endpoint. Fugu decides how to handle it internally. It solves a task directly when that is enough. It also assembles and coordinates a team of expert models when needed. The complexity

Sakana AI Launches Sakana Fugu: An Orchestration Model That Routes Tasks Across a Swappable Pool of Frontier LLMs Read More »

MoonMath AI Open-Sources a HIP Attention Kernel for AMD MI300X That Beats AITER v3 on Every Shape and Rounding Mode

MoonMath AI team has released a bf16 forward attention kernel for AMD’s MI300X GPU. It is written in HIP, not hand-written assembly. The code is open-source under the MIT license. The MoonMath.ai team reports it beats AITER v3, AMD’s own optimized kernel, on every tested shape. Bare-metal access came from HotAisle, an AMD cloud provider.

MoonMath AI Open-Sources a HIP Attention Kernel for AMD MI300X That Beats AITER v3 on Every Shape and Rounding Mode Read More »

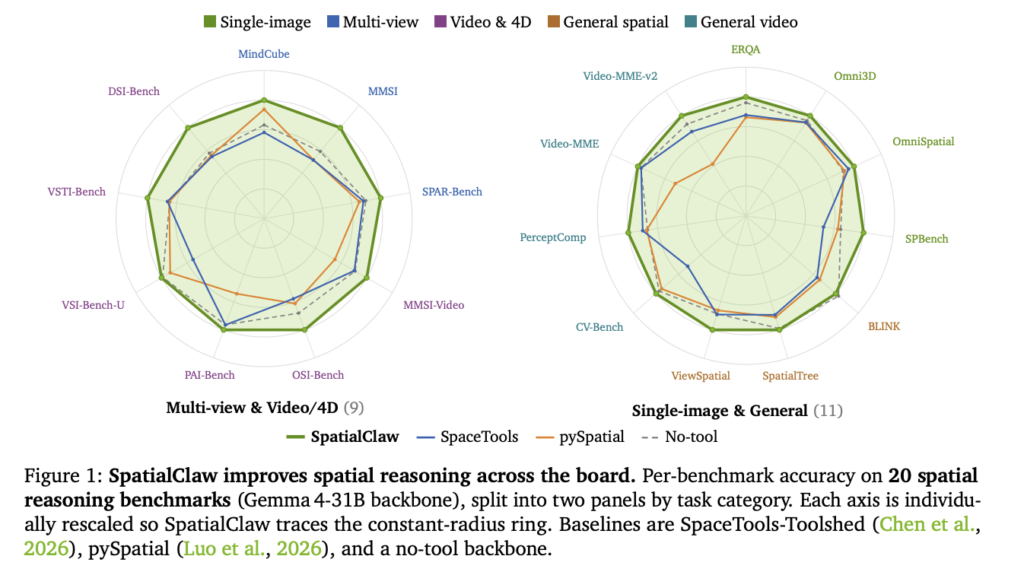
NVIDIA AI Introduce SpatialClaw: A Training-Free Agent That Treats Code as the Action Interface for Spatial Reasoning

NVIDIA Research has released SpatialClaw, a training-free framework for spatial reasoning. It targets a persistent weakness in vision-language models (VLMs). These models still struggle to judge where objects are, how they relate, and how they move in 3D. SpatialClaw does not retrain the model. Instead, it changes the action interface the agent uses to call

NVIDIA AI Introduce SpatialClaw: A Training-Free Agent That Treats Code as the Action Interface for Spatial Reasoning Read More »

Liquid AI Introduces LFM2.5-Embedding-350M and LFM2.5-ColBERT-350M: Dense Bi-Encoder and Late-Interaction Models for Fast Multilingual Search Across 11 Languages

This week, Liquid AI released two new retrieval models. They are LFM2.5-ColBERT-350M and LFM2.5-Embedding-350M. Both hold 350M parameters. Both are the first bidirectional members of the LFM family. They build on LFM2.5-350M-Base, released in March. The pair targets fast multilingual and cross-lingual search across 11 languages. Their footprint is small enough to run almost anywhere.

Liquid AI Introduces LFM2.5-Embedding-350M and LFM2.5-ColBERT-350M: Dense Bi-Encoder and Late-Interaction Models for Fast Multilingual Search Across 11 Languages Read More »

Perplexity Launches Brain, a Self-Improving Memory System That Builds a Context Graph of an Agent’s Work and Learns Overnight

Most AI memory remembers the user. It stores your preferences, your tastes, and your role. Perplexity is taking a different path. Today, Perplexity launched Brain, a self-improving memory system for its agent product, Computer. Brain does not focus on remembering you. It remembers what the agent did. That reframes what memory in AI is for.

Perplexity Launches Brain, a Self-Improving Memory System That Builds a Context Graph of an Agent’s Work and Learns Overnight Read More »

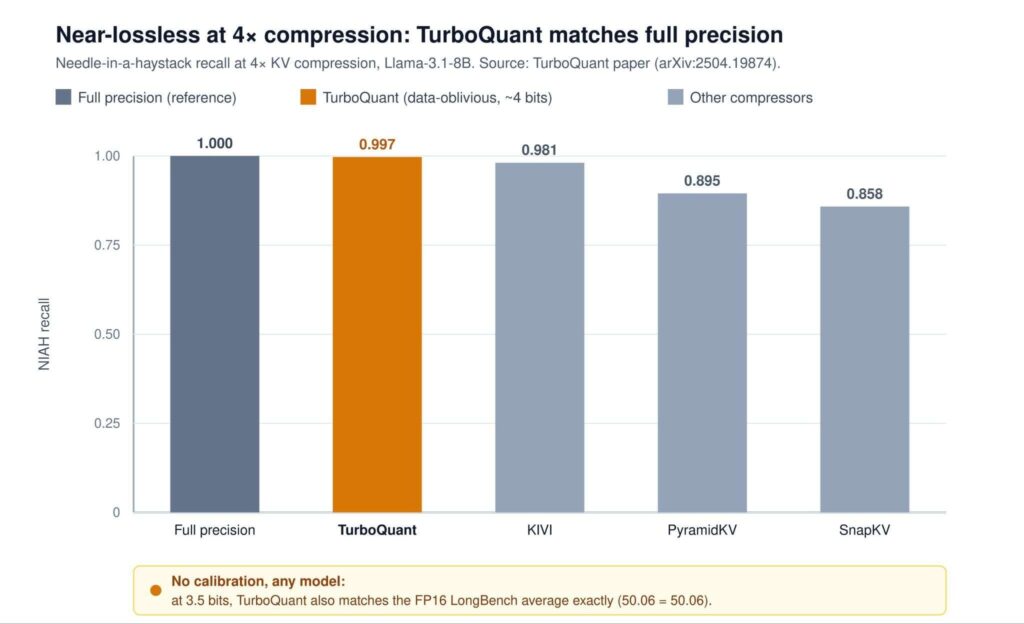
The KV Cache Compression Race: TurboQuant vs OSCAR vs EpiCache

Long-context large language models (LLMs) face a memory bottleneck that has nothing to do with model weights. During decoding, transformers cache the key and value (KV) vectors for every token at every layer so they don’t have to recompute attention. This cache grows linearly with sequence length and batch size, and at long context with

The KV Cache Compression Race: TurboQuant vs OSCAR vs EpiCache Read More »