Machine Learning

Auto Added by WPeMatico

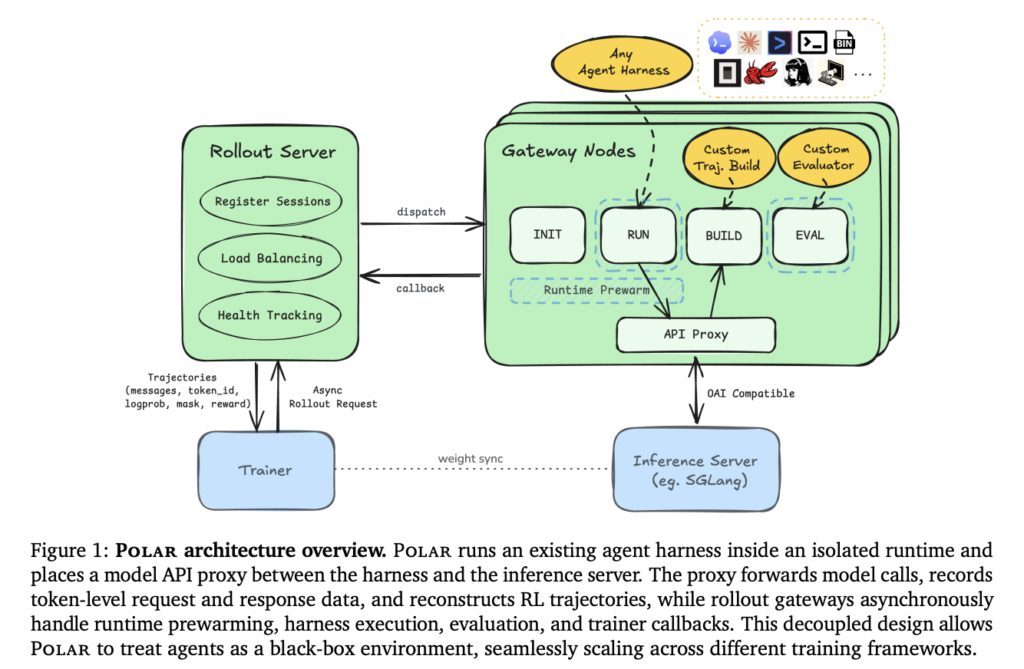
NVIDIA Releases Polar, a Token-Faithful Rollout Framework for GRPO Training Across Codex, Claude Code, and Qwen Code

Reinforcement learning for language agents is growing more complex. Agents now manage multi-turn tool use, long-running contexts, and multi-agent orchestration. The main engineering challenge is connecting existing agent software to training pipelines without breaking how those tools work. NVIDIA’s research team introduced Polar, a rollout framework that lets researchers run reinforcement learning over any agent

NVIDIA Releases Polar, a Token-Faithful Rollout Framework for GRPO Training Across Codex, Claude Code, and Qwen Code Read More »

Banner for AI & Big Data Expo by TechEx events.

Google folds Display Ads into AI-first Demand Gen platform

Google is folding Display Ads into its AI-powered Demand Gen platform, marking the end of a long-standing digital advertising model. The Google Display Network (GDN) has been a staple of the open internet for almost twenty years. Marketers previously relied on its predictable framework to target placements, bid on audiences, and A/B test static creative

Google folds Display Ads into AI-first Demand Gen platform Read More »

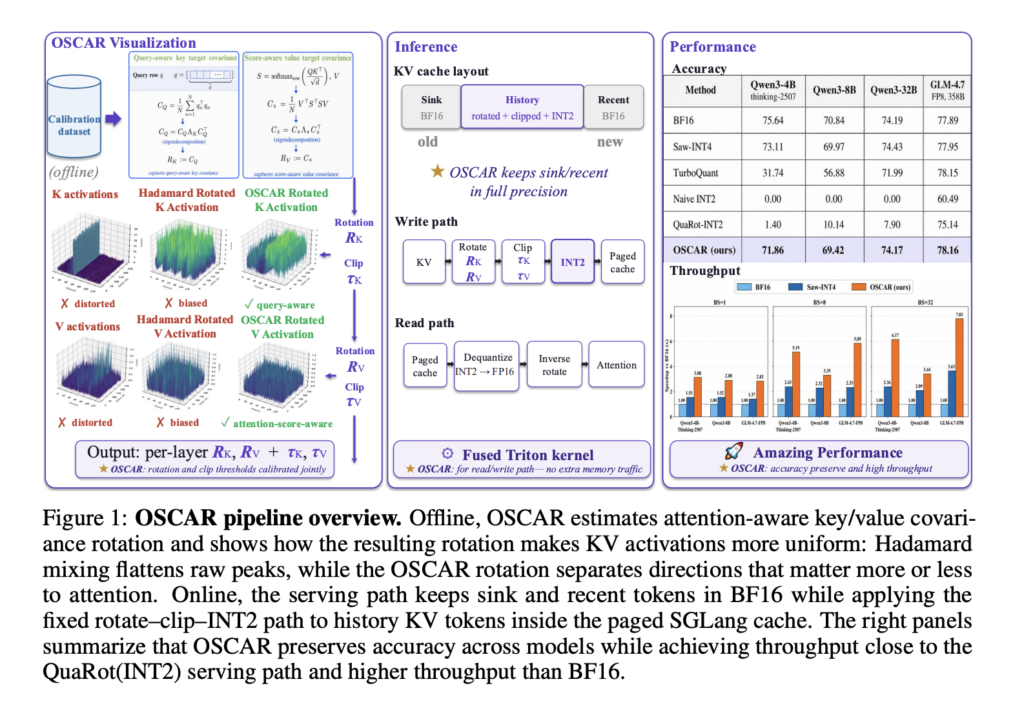
Together AI Open-Sources OSCAR: An Attention-Aware 2-Bit KV Cache Quantization System for Long-Context LLM Serving

Long-context inference makes the KV cache one of the main costs of serving LLMs. During autoregressive decoding, the cache grows with context length, batch size, and model depth. At high batch sizes and long contexts with 100K tokens across dozens of concurrent requests the KV cache consumes a large fraction of GPU memory. Compressing it

Together AI Open-Sources OSCAR: An Attention-Aware 2-Bit KV Cache Quantization System for Long-Context LLM Serving Read More »

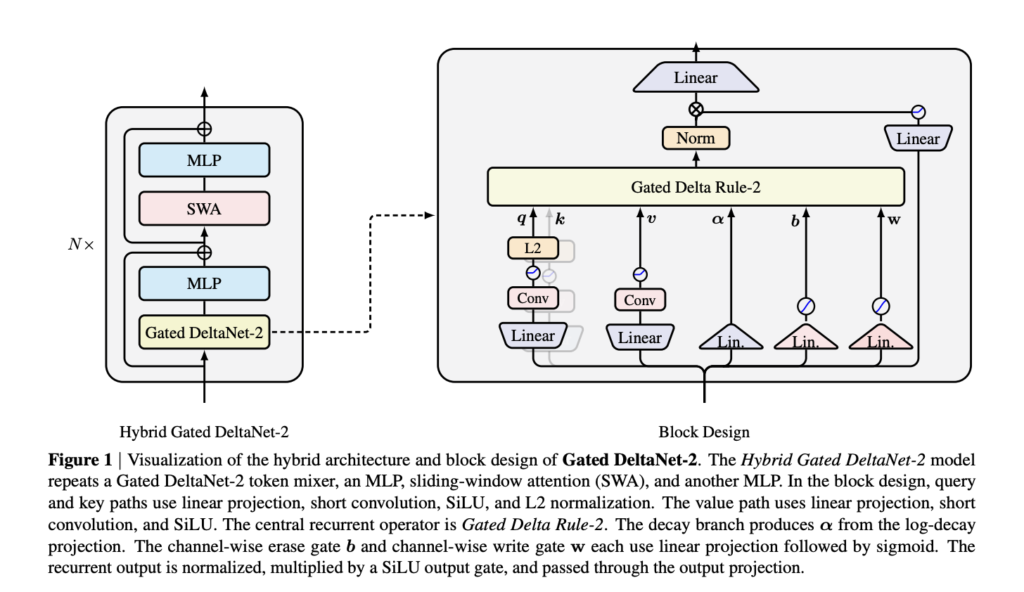
NVIDIA AI Releases Gated DeltaNet-2: A Linear Attention Layer That Decouples Erase and Write in the Delta Rule

Linear attention replaces the unbounded KV cache of softmax attention with a fixed-size recurrent state. This cuts sequence mixing to linear time and decoding to constant memory. The hard part is not what to forget. It is how to edit a compressed memory without scrambling existing associations. NVIDIA has released Gated DeltaNet-2, a linear attention

NVIDIA AI Releases Gated DeltaNet-2: A Linear Attention Layer That Decouples Erase and Write in the Delta Rule Read More »

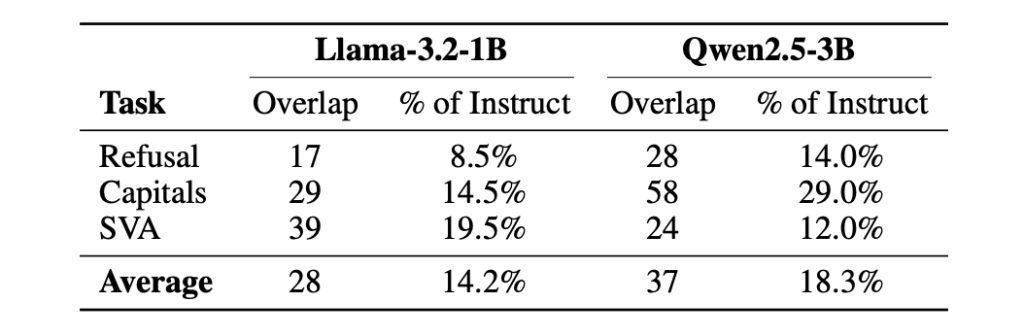
Nous Research Releases Contrastive Neuron Attribution (CNA): Sparse MLP Circuit Steering Without SAE Training or Weight Modification

Instruction-tuned language models refuse harmful requests. But which part of the model is actually responsible — and how does that mechanism get installed during training? A new research from Nous Research team takes a neuron-level look at this question. The Nous research team developed contrastive neuron attribution (CNA), a method that identifies the specific MLP

Nous Research Releases Contrastive Neuron Attribution (CNA): Sparse MLP Circuit Steering Without SAE Training or Weight Modification Read More »

Perplexity Open-Sources Bumblebee: A Read-Only Supply-Chain Scanner for Developer Endpoints

Attackers increasingly target the packages, editor extensions, and AI tool configs on developer machines and not just production systems. Perplexity has open-sourced an internal tool it uses to address this problem. Perplexity released Bumblebee on GitHub. The tool is a read-only inventory collector for macOS and Linux developer endpoints. It is written entirely in Go

Perplexity Open-Sources Bumblebee: A Read-Only Supply-Chain Scanner for Developer Endpoints Read More »

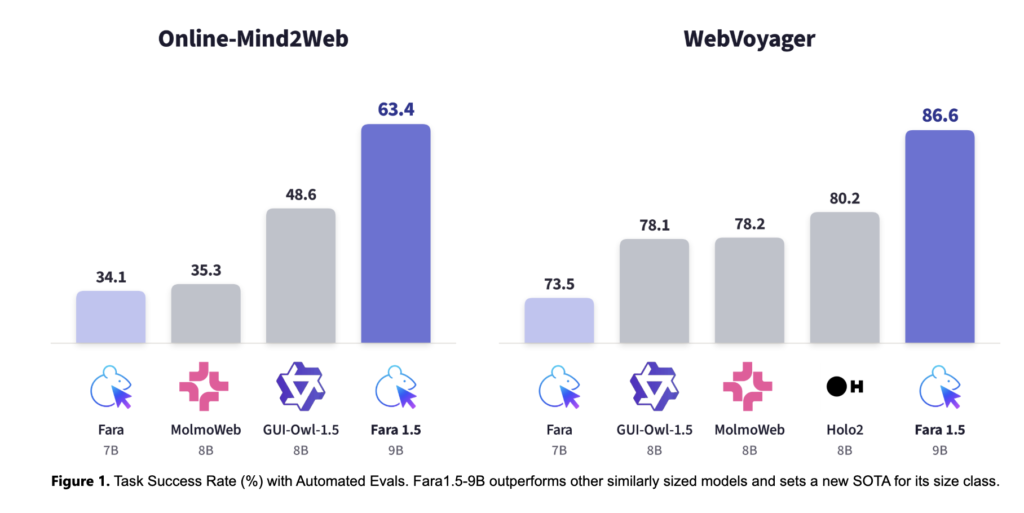
Microsoft Releases Fara1.5: A Family of Browser Computer-Use Agents (4B/9B/27B) That Outperform OpenAI Operator and Gemini 2.5 Computer Use on Online-Mind2Web

Microsoft Research’s AI Frontiers lab released Fara1.5. It is a family of computer-use agent (CUA) models for the browser. The release ships three sizes: Fara1.5-4B, Fara1.5-9B, and Fara1.5-27B. The models are integrated with MagenticLite, Microsoft’s sandboxed browser interface for these agents. Computer-use agents are pixel-to-action models that drive a real browser. They read screenshots and

Microsoft Releases Fara1.5: A Family of Browser Computer-Use Agents (4B/9B/27B) That Outperform OpenAI Operator and Gemini 2.5 Computer Use on Online-Mind2Web Read More »

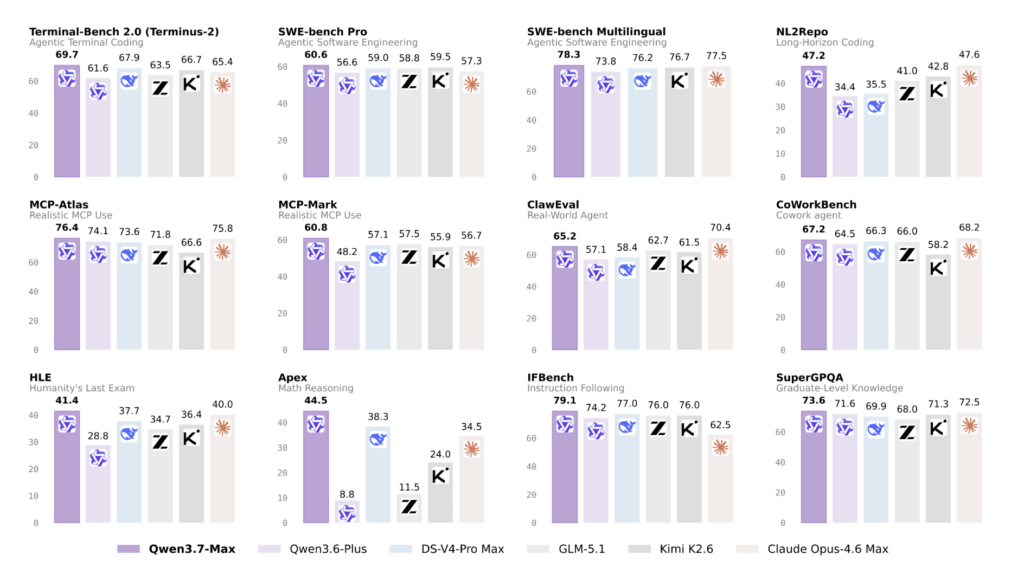
Qwen Introduces Qwen3.7-Max: A Reasoning Agent Model With a 1M-Token Context Window

Most AI models today are not designed for sustained, multi-step autonomous execution. Tasks like running hundreds of iterative code modifications, or chaining tool calls across hours without human intervention, require a different kind of model architecture and training focus. Alibaba’s Qwen team formally announced Qwen3.7-Max at the 2026 Alibaba Cloud Summit on May 20. Although,

Qwen Introduces Qwen3.7-Max: A Reasoning Agent Model With a 1M-Token Context Window Read More »

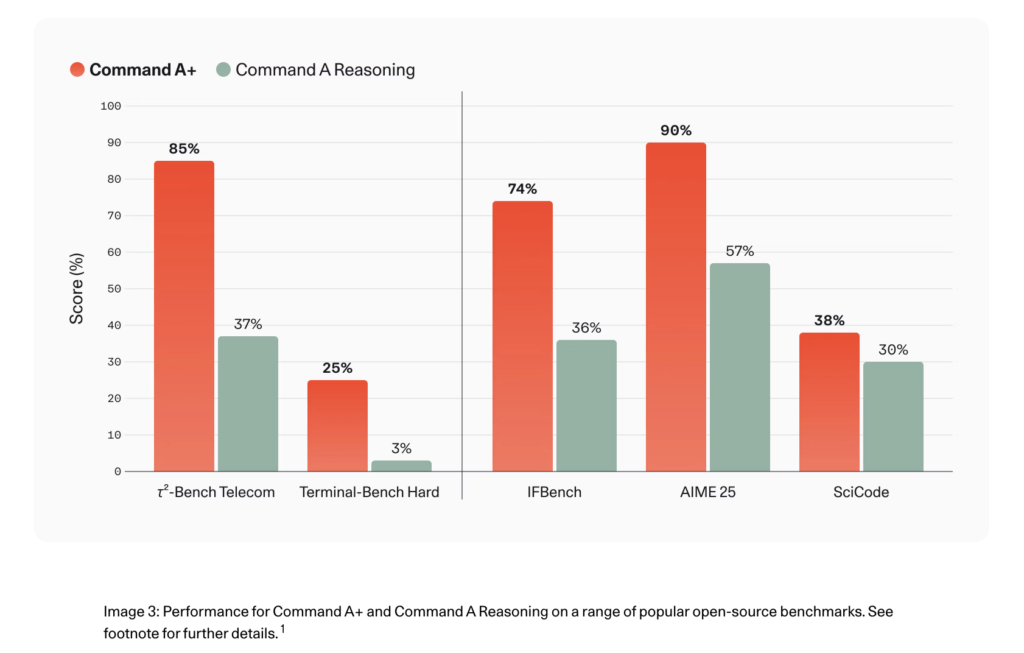
Cohere Releases Command A+: A 218B Sparse MoE Model for Agentic Workflows That Runs on as Few as Two H100 GPUs

Cohere just released Command A+, as an open-source model targeting enterprise agentic workflows. Available under an Apache 2.0 license, Command A+ is a mixture-of-experts (MoE) model built for high-performance agentic tasks with minimal compute overhead. The model is optimized for reasoning, agentic workflows, RAG, multilingual, and multimodal document processing. It unifies capabilities from four prior

Cohere Releases Command A+: A 218B Sparse MoE Model for Agentic Workflows That Runs on as Few as Two H100 GPUs Read More »

Meet Turbovec: A Rust Vector Index with Python Bindings, and Built on Google’s TurboQuant Algorithm

Vector search underpins most retrieval-augmented generation (RAG) pipelines. At scale, it gets expensive. Storing 10 million document embeddings in float32 consumes 31 GB of RAM. For dev teams running local or on-premise inference, that number creates real constraints. A new open-source library called turbovec addresses this directly. It is a vector index written in Rust

Meet Turbovec: A Rust Vector Index with Python Bindings, and Built on Google’s TurboQuant Algorithm Read More »