Machine Learning

Auto Added by WPeMatico

Genesis AI Releases Nyx, Quadrants, and Genesis World 1.0 Physics Platform for Scalable Robotics Foundation Model Evaluation

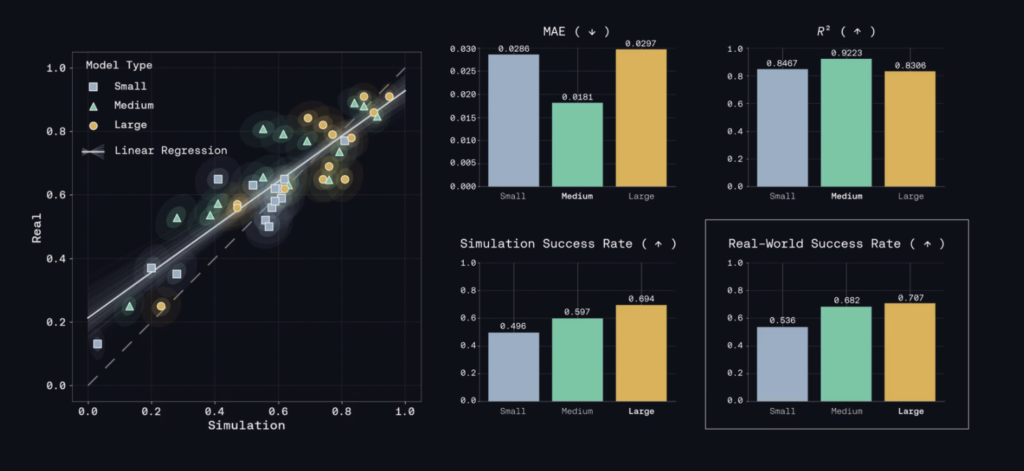
Genesis AI released Genesis World 1.0. The platform consists of four components: the Genesis World physics engine, Nyx (a real-time path-traced renderer), Quadrants (a Python-to-GPU compiler), and a simulation interface. It is designed to accelerate robotics foundation model development through simulation-based evaluation. Robotics model development has two bottlenecks: data and iteration speed. The field has
Genesis AI Releases Nyx, Quadrants, and Genesis World 1.0 Physics Platform for Scalable Robotics Foundation Model Evaluation Read More »

AML Engine Performance

How the Right Infrastructure Unlocks Better AML Engine Performance

Many anti-money laundering (AML) engines underperform or generate excessive false positives because of the scale and complexity of modern financial data. These unsatisfactory results are typically not due to flawed detection logic but rather to insufficient supporting infrastructure. A variety of infrastructure limitations, such as weak data pipelines, limited compute scalability, poorly performing databases, and

How the Right Infrastructure Unlocks Better AML Engine Performance Read More »

NVIDIA Introduces X-Token: Projection-Guided Cross-Tokenizer KD That Outperforms GOLD by +3.82 Average Points on Llama-3.2-1B

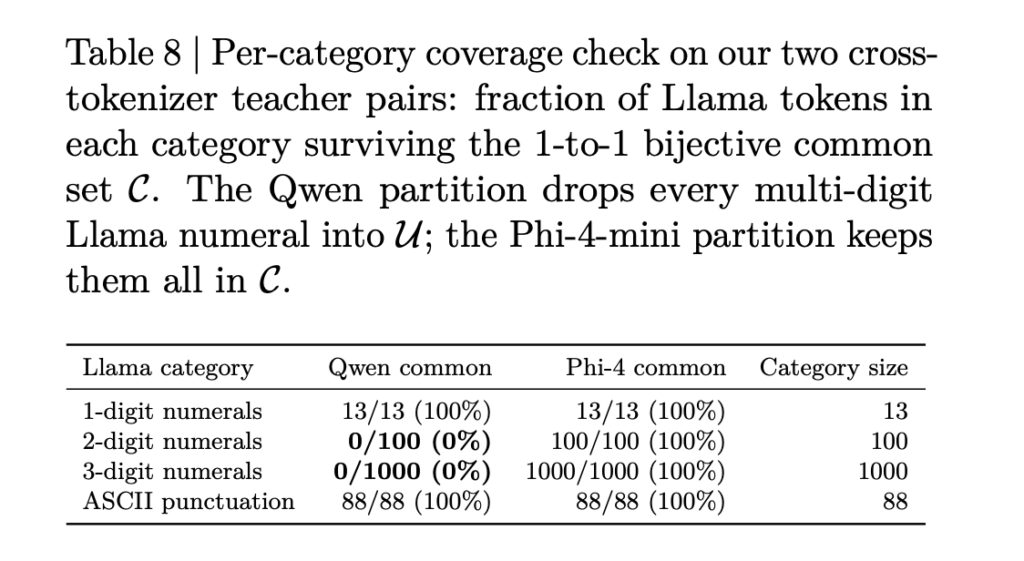
Knowledge distillation (KD) transfers “dark knowledge” from a large teacher model to a smaller student. The student learns from the teacher’s full output probability distribution over tokens, not just correct answers. This is done via per-position Kullback–Leibler (KL) divergence over next-token probability distributions. This formulation requires a shared tokenizer. A practitioner committed to Llama-3.2-1B cannot

NVIDIA Introduces X-Token: Projection-Guided Cross-Tokenizer KD That Outperforms GOLD by +3.82 Average Points on Llama-3.2-1B Read More »

StepFun Releases Step 3.7 Flash: A 198B MoE Vision-Language Model for Coding Agents and Search Workflows

StepFun today released Step 3.7 Flash, a multimodal Mixture-of-Experts model targeting agentic use cases. It adds native vision input and improved tool-use reliability over Step 3.5 Flash. What is Step 3.7 Flash? Step 3.7 Flash is a 198B-parameter sparse Mixture-of-Experts (MoE) vision-language model. It pairs a 196B-parameter language backbone with a 1.8B-parameter vision encoder (ViT)

StepFun Releases Step 3.7 Flash: A 198B MoE Vision-Language Model for Coding Agents and Search Workflows Read More »

⚡

Meet mKernel: A Multi-GPU, Multi-Node Fused Kernel Library for GPU-Driven Communication

GPU communication overhead is a measurable bottleneck in production AI workloads. According to data cited by the mKernel project, communication can consume 43.6% of the forward pass and 32% of end-to-end training time. Across popular Mixture-of-Experts (MoE) models, inter-device communication can account for up to 47% of total execution time. Researchers from UC Berkeley’s UCCL

Meet mKernel: A Multi-GPU, Multi-Node Fused Kernel Library for GPU-Driven Communication Read More »

How to Design an End-to-End Ansible Automation Lab with Playbooks, Inventories, Roles, Vault, Dynamic Inventory, and Custom Modules

In this tutorial, we build a complete Ansible lab that runs end-to-end in Google Colab or any Linux environment. We start by installing ansible-core, setting up a local workspace, creating an Ansible configuration file, and defining both static and dynamic inventories. We then explore key Ansible concepts, including group variables, host variables, variable precedence, ad

How to Design an End-to-End Ansible Automation Lab with Playbooks, Inventories, Roles, Vault, Dynamic Inventory, and Custom Modules Read More »

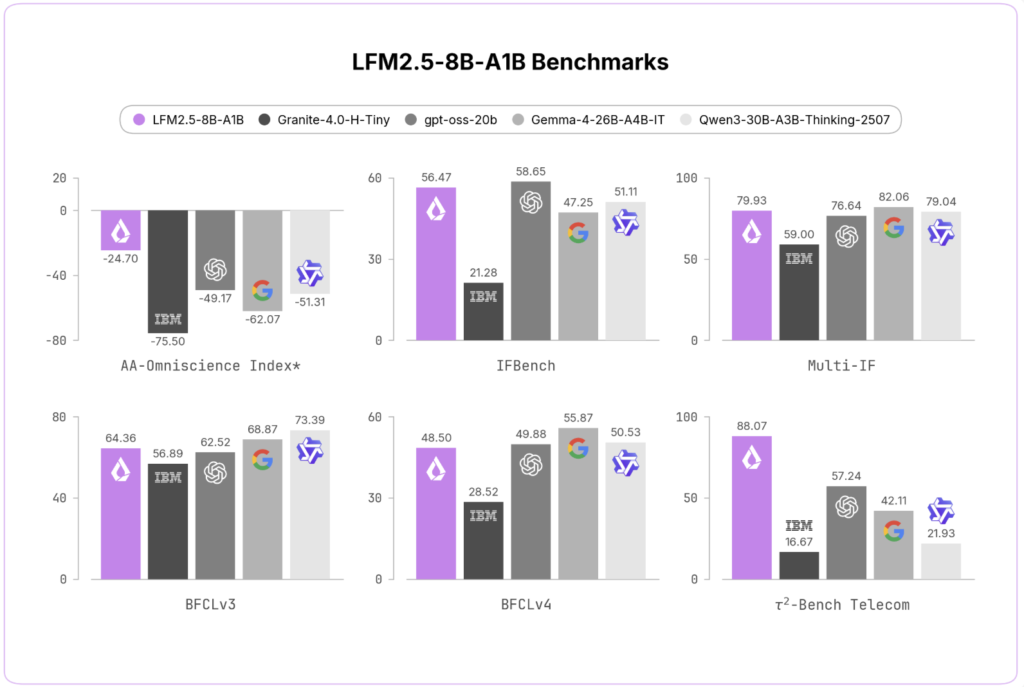
Liquid AI Releases LFM2.5-8B-A1B: An On-Device MoE Model With 8.3B Total and 1.5B Active Parameters

Liquid AI just shipped LFM2.5-8B-A1B. It is an on-device Mixture-of-Experts (MoE) model built for tool calling. The model holds 8.3B total parameters but activates only 1.5B per token. That sparsity is what lets it run on consumer hardware. The release follows LFM2-8B-A1B, which Liquid AI team published earlier. LFM2.5 is a new family of hybrid

Liquid AI Releases LFM2.5-8B-A1B: An On-Device MoE Model With 8.3B Total and 1.5B Active Parameters Read More »

Anthropic Ships Claude Opus 4.8 Alongside Dynamic Workflows and Cheaper Fast Mode, With Workflows Capped at 1,000 Subagents

Anthropic just launched Claude Opus 4.8. Also, there two Claude Code updates shipped with it. Dynamic workflows run many subagents in parallel. Fast mode now supports Opus 4.8 at a lower price. Both are research previews. What Dynamic Workflows Actually Are A dynamic workflow is a JavaScript script that orchestrates subagents at scale. Claude writes

Anthropic Ships Claude Opus 4.8 Alongside Dynamic Workflows and Cheaper Fast Mode, With Workflows Capped at 1,000 Subagents Read More »

Perplexity AI Open-Sources Unigram Tokenizer That Achieves 5x Lower p50 Latency Than Hugging Face tokenizers Crate

Perplexity AI’s research team reimplemented their Unigram tokenizer from scratch in Rust and open-sourced the code in pplx-garden, their inference technology repository. At production input lengths, the new encoder cuts p50 latency by roughly 5x versus the Hugging Face tokenizers crate, ~2x versus SentencePiece (C++), and ~1.5x versus IREE’s tokenizer (C), with zero steady-state heap

Perplexity AI Open-Sources Unigram Tokenizer That Achieves 5x Lower p50 Latency Than Hugging Face tokenizers Crate Read More »

Sakana AI Proposes DiffusionBlocks: a Block-wise Training Framework That Converts Residual Networks into Independently Trainable Denoising Modules

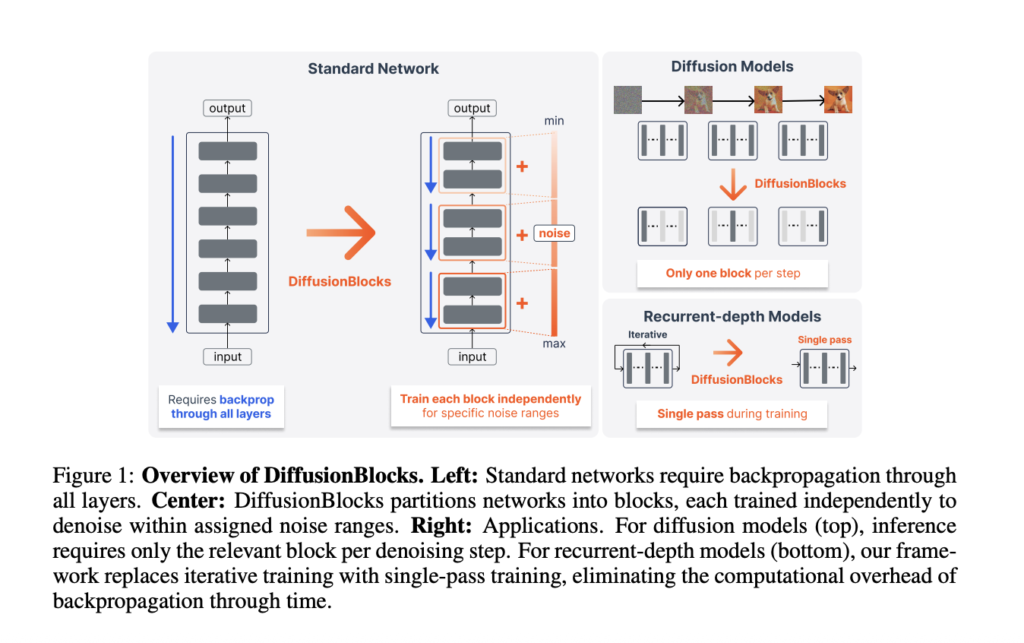
Researchers from Sakana AI and the University of Tokyo propose DiffusionBlocks. It trains transformer-based networks one block at a time. Training memory is reduced by a factor of B, where B is the number of blocks. Performance is maintained across diverse architectures. The Memory Problem in Neural Network Training End-to-end backpropagation requires storing intermediate activations

Sakana AI Proposes DiffusionBlocks: a Block-wise Training Framework That Converts Residual Networks into Independently Trainable Denoising Modules Read More »