Machine Learning

Auto Added by WPeMatico

This game-playing AI is the new champ at Stratego

A new AI system that excels at challenging games with hidden information could someday help human decision-makers select ideal strategies to outfox opponents in complicated situations like military maneuvers.Using advances in machine-learning, researchers from MIT, Carnegie Mellon University, New York University, and Stanford University developed an AI that defeated top-ranked human players of the board

This game-playing AI is the new champ at Stratego Read More »
Perplexity Introduces Photon: A Rust-Based Retrieval Engine That Cuts p99 Latency From 800 ms to 65 ms

Perplexity has released Photon, an in-house retrieval and ranking engine written in Rust. It replaces an open-source engine Perplexity had forked for its AI-native search stack. Photon now handles retrieval and ranking for all production traffic. It also powers a new Fast Search mode in the Perplexity Search API. Perplexity reports single-call latency of 160

Perplexity Introduces Photon: A Rust-Based Retrieval Engine That Cuts p99 Latency From 800 ms to 65 ms Read More »

NVIDIA Researchers Introduce Physis-Lang: Self-Evolving Physical Language That Lifts Cosmos 3 Past Veo 3.1 on Physics Benchmarks

Video world models can render convincing clips that still break physics. Butter spreads like paint. Balls pass through walls. A team from NVIDIA, MIT and the University of Oxford argues the fix can come from language itself, not from extra visual, latent or numerical signals. Their framework, Physis-Lang, treats physical language as a shared, optimizable

NVIDIA Researchers Introduce Physis-Lang: Self-Evolving Physical Language That Lifts Cosmos 3 Past Veo 3.1 on Physics Benchmarks Read More »

Liquid AI Releases d1: A Decision Model That Returns Calibrated Probabilities With Zero Output Tokens

Liquid AI has released d1, a decision model built for structured choices instead of text generation. You give it context and a set of typed questions. It returns calibrated probabilities across a fixed set of outcomes in a single call, with zero generated tokens. The target is the work many teams still send to general

Liquid AI Releases d1: A Decision Model That Returns Calibrated Probabilities With Zero Output Tokens Read More »

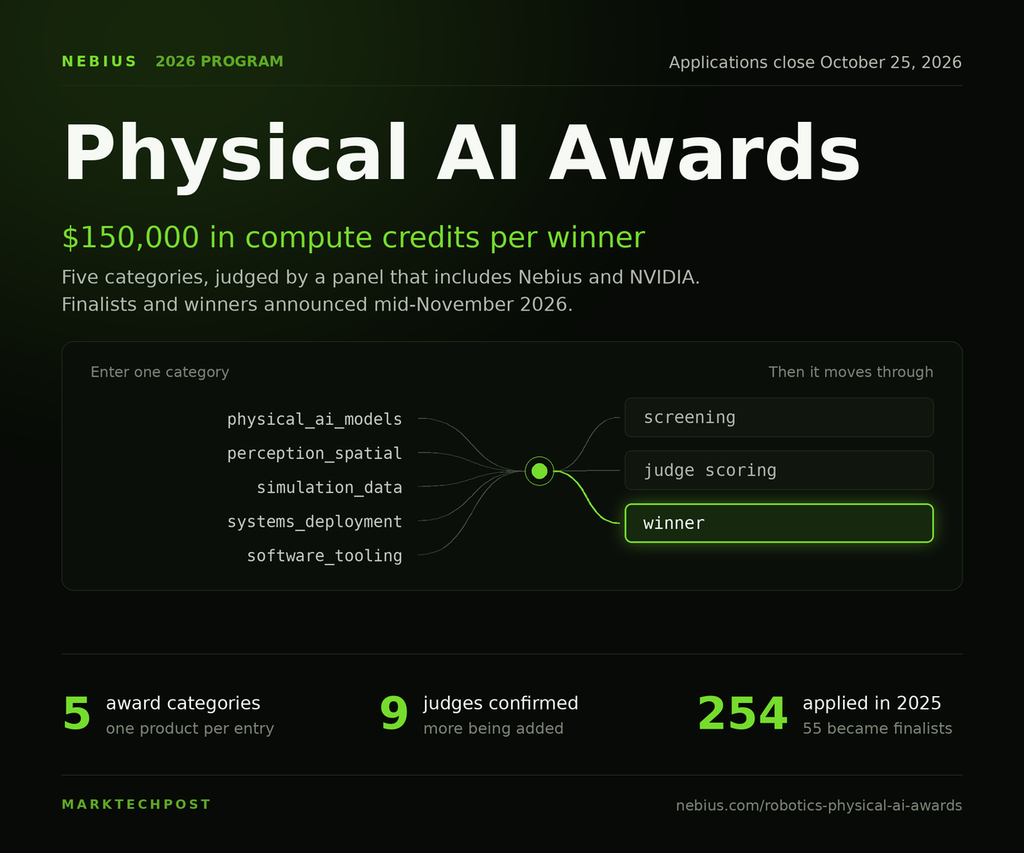
Nebius Opens 2026 Physical AI Awards: Five $150K Compute Credit Prizes

Once a physical AI product is in the field, the compute problem changes shape. Fleet data starts arriving faster than a team can label it, every retraining cycle has to be validated before it ships to hardware, and the sim-to-real loop stops being a research exercise and becomes a release process. That is the stage

Nebius Opens 2026 Physical AI Awards: Five $150K Compute Credit Prizes Read More »

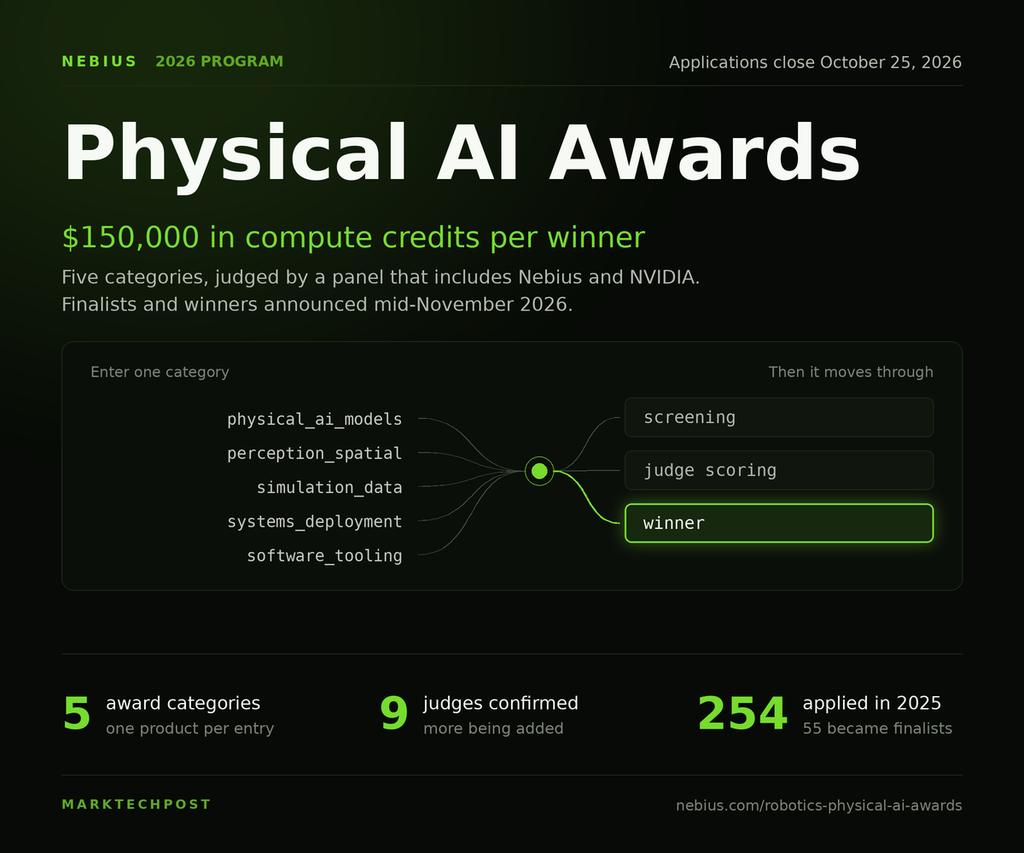
Nebius Opens 2026 Physical AI Awards: Five $150K Compute Prizes, Nine Judges, and an October 25 Deadline

Once a physical AI product is in the field, the compute problem changes shape. Fleet data starts arriving faster than a team can label it, every retraining cycle has to be validated before it ships to hardware, and the sim-to-real loop stops being a research exercise and becomes a release process. That is the stage

Nebius Opens 2026 Physical AI Awards: Five $150K Compute Prizes, Nine Judges, and an October 25 Deadline Read More »

Google Research Open-Sources RRSI: AI Agents That Improve Their Own Harness Without Overfitting

Google Cloud AI Research, with UNC-Chapel Hill, Stanford and Washington University in St. Louis, has released RRSI (Regularized Recursive Self-Improvement). It lets an LLM agent rewrite its own harness: prompts, tools, memory, control flow and sub-agents. Model weights never change. RRSI constrains the improvement loop itself, so gains hold on benchmarks the agent never optimized

Google Research Open-Sources RRSI: AI Agents That Improve Their Own Harness Without Overfitting Read More »

The effects of an “algorithmic monoculture” depend on the details

AI tools are increasingly replacing human judgements in some settings. For instance, resume screening algorithms are often used in hiring, where they may improve efficiency and consistency in decision-making.But some scholars have raised concerns that the adoption of automated systems could eventually result in one algorithm being used to make all decisions in a particular

The effects of an “algorithmic monoculture” depend on the details Read More »

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens

Fireworks AI has released Ember-1, a specialized model from Fireworks Research built by post-training Moonshot AI’s open-weight Kimi K3. Ember-1 learns to produce shorter reasoning traces while keeping task accuracy. This is different from lowering the reasoning effort setting at inference time. According to the Fireworks release post, Ember-1 delivers Kimi K3’s quality with about

Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens Read More »

A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation

In this tutorial, we work with MSEB, the Massive Sound Embedding Benchmark from Google Research, and approach it from the perspective of what a leaderboard number actually means: the evaluator surface. We install the package and map its three layers, then write two deliberately different encoders against the framework’s own abstract base class: one that

A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation Read More »