
Machine Learning

Auto Added by WPeMatico

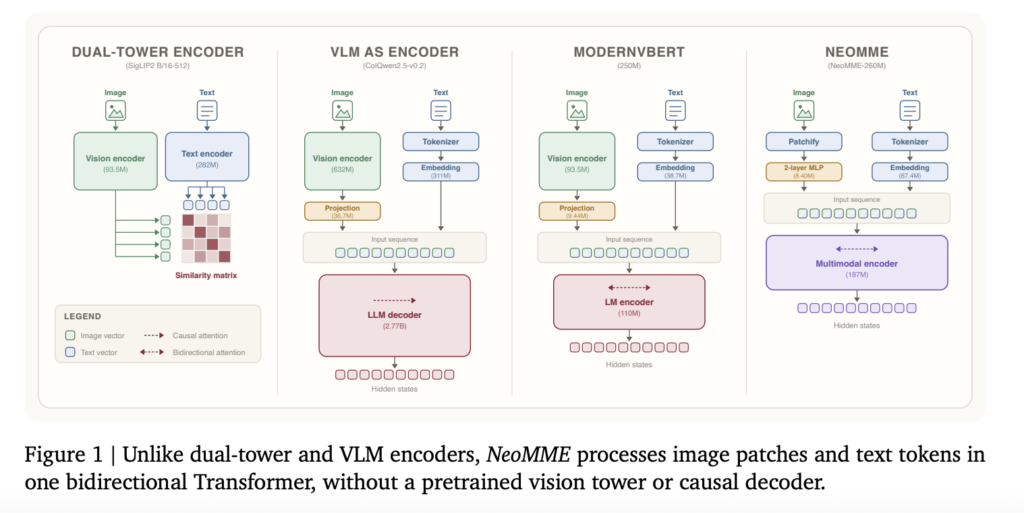
H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder

Most visual document retrievers in production today are hand-me-downs. ColPali and the models that followed it take a generative vision-language model and repurpose it as an encoder. The result still carries a separately pretrained vision tower and a causal decoder that never generates a token. That is parameter and compute overhead for a task that

H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder Read More »

Meta FAIR Introduces AI Research Preference Models (RPMs): Ranking ML Experiments Before Spending GPU Hours

AI research agents can already propose, implement and score their own machine learning experiments. Idea generation is cheap; verification is not. Training one candidate can consume hours to days of GPU time, so an agent proposes far more candidates than it can afford to run. Which ones get run is the real lever on research

Meta FAIR Introduces AI Research Preference Models (RPMs): Ranking ML Experiments Before Spending GPU Hours Read More »

UC Berkeley Researchers Release CUA-Lite, an Open Platform Unifying Sandboxes, Data, Evaluation and RL for Computer-Use Agents

A team of researchers from UC Berkeley have released CUA-Lite, an open platform for computer-use agents (CUAs). The argument behind it is infrastructural rather than model-centric: training and benchmarking a CUA requires four pieces: agents, environments, traces, and a framework to evaluate and train them and all four are currently fragmented across separate repositories with

UC Berkeley Researchers Release CUA-Lite, an Open Platform Unifying Sandboxes, Data, Evaluation and RL for Computer-Use Agents Read More »

Google Launches Agentic Video Understanding for Gemini Flash Models, Cutting Video Tokens by Up to 88%

Video has been the most expensive modality to reason over. A Gemini model handed a 90-minute lecture has, until now, ingested the whole thing at a fixed one frame per second, whether the question was ‘summarize this’ or ‘what time does the speaker switch to the pricing slide?’ That single-pass design forces a bad trade:

Google Launches Agentic Video Understanding for Gemini Flash Models, Cutting Video Tokens by Up to 88% Read More »

NVIDIA Releases Personal AI Router (PAIR): An Open Source Virtual Inference Router that Distributes Local AI Requests Across RTX, DGX Spark, and Mac Nodes

Multi-agent workflows have changed the shape of local inference. A lead agent decomposes a task and spawns subagents. What looked like one user request becomes dozens of independent model calls. Pointed at a single local engine, those calls compete for the same execution slots. The queue grows while a workstation, laptop, or DGX Spark on

NVIDIA Releases Personal AI Router (PAIR): An Open Source Virtual Inference Router that Distributes Local AI Requests Across RTX, DGX Spark, and Mac Nodes Read More »

Google DeepMind’s WeatherNext 3 Trains on Weather Station Observations to Deliver 5 km Global Forecasts, Refreshed Every Hour

AI weather models have spent three years closing the gap with physics-based forecasting, but two problems stayed open: resolution too coarse for local terrain, and initialization tied to numerical weather prediction (NWP) analysis that arrives about six hours late. WeatherNext 3, released by Google DeepMind and Google Research, attacks both. It takes a live global

Google DeepMind’s WeatherNext 3 Trains on Weather Station Observations to Deliver 5 km Global Forecasts, Refreshed Every Hour Read More »

OpenAI Releases GPT-6 Astra: A 1.05M-Context Computer-Use Model Gated Behind a ‘Critical’ Cyber Threshold

Today, OpenAI released GPT-6 Astra. The company calls it its most intelligent and aligned model, and positions it primarily as a computer-use system rather than a chat model. The pitch is that Astra operates software the way a person does, across browsers, spreadsheets, desktop applications and terminals, and finishes multi-step jobs instead of describing how

OpenAI Releases GPT-6 Astra: A 1.05M-Context Computer-Use Model Gated Behind a ‘Critical’ Cyber Threshold Read More »

Meta AI Released Muse Spark 1.3: An Agentic Coding Model That Uses ~20% Fewer Tool Calls and ~25% Fewer Tokens Than Muse Spark 1.2

This week, Meta Superintelligence Labs released Muse Spark 1.3. It is the fourth Muse Spark release in five months, and the target is long-horizon agentic and coding work rather than single-turn generation. The framing in Meta’s post is usability: sustaining a long thread, collaborating with the user, and knowing when it is stuck. Is it

Meta AI Released Muse Spark 1.3: An Agentic Coding Model That Uses ~20% Fewer Tool Calls and ~25% Fewer Tokens Than Muse Spark 1.2 Read More »

Perplexity Open Sources Lily: A Rust + Metal Inference Engine for Qwen3.6-35B-A3B on Apple Silicon

Perplexity has open sourced Lily, the local inference engine behind Hybrid Compute in Perplexity Computer. It is a single-process runtime: a Rust layer loads the checkpoint and drives the generation loop, an OpenAI-compatible chat-completions API streams tokens, and hand-written Metal kernels execute the model. Neither PyTorch nor MLX sits in the execution path. Lily is

Perplexity Open Sources Lily: A Rust + Metal Inference Engine for Qwen3.6-35B-A3B on Apple Silicon Read More »

Qwen Developers Open-Sources zg (zvec-grep): A Local-First Search Layer Unifying ripgrep, BM25, and Vector Search

Coding agents spend a large share of their tool budget on search. When the target is a known symbol, ripgrep answers it exactly. When the target is a behavior described in plain language, keyword matching often misses, and the agent falls back to guessing terms, reading whole files, and assembling context by hand. Each of

Qwen Developers Open-Sources zg (zvec-grep): A Local-First Search Layer Unifying ripgrep, BM25, and Vector Search Read More »