
Language Model

Auto Added by WPeMatico

▶

Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million Hours of Human Video

Dyna Robotics has released Dyna-2, a world-action model for robot manipulation. It was pre-trained on more than one million hours of egocentric human video. That is roughly 170 years of continuous waking experience. Robot learning has been bottlenecked by action-labelled data, which teleoperation must deliberately produce. Dyna-2 tests whether ordinary human video can substitute. The […]
Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million Hours of Human Video Read More »

SpaceXAI Releases Grok 4.6: A 500K-Context Frontier Model Tuned for Long-Running Agents, Coding, and Knowledge Work

SpaceXAI just released Grok 4.6. The release is a post-training upgrade over Grok 4.5 rather than a larger base model. SpaceXAI held the foundation constant and spent the improvement on a longer supplemental training run, regenerated supervised fine-tuning trajectories, and reinforcement learning in agentic environments. Agents that stay on a task across many steps without

SpaceXAI Releases Grok 4.6: A 500K-Context Frontier Model Tuned for Long-Running Agents, Coding, and Knowledge Work Read More »

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with 3B Active Parameters, and NeMo Switchyard Model Router

NVIDIA introduced open technologies for building always-on AI agents from systems of specialized models. Two artifacts shipped together. Nemotron 3.5 Lightning is a lightweight, customizable open model built for high-volume agentic tasks, and NeMo Switchyard is an open source routing library that directs each step of an agent workflow to the most capable and efficient

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with 3B Active Parameters, and NeMo Switchyard Model Router Read More »

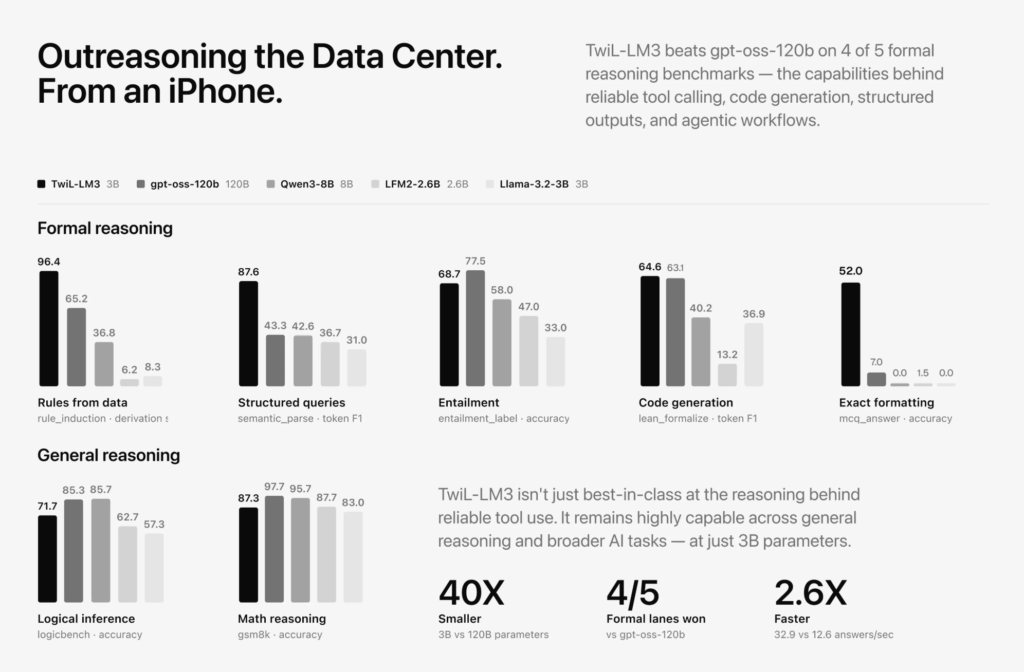
webAI Releases TwIL-LM: A 1.7B and 3B Formal-Logic Model Family for Autoformalization on Local Hardware

webAI has released TwIL-LM, a two-model family of formal-logic reasoners at 1.7B and 3B parameters. The 3B member, TwIL-LM3, is a merged fine-tune of SmolLM3-3B; the 1.7B member is a PEFT LoRA adapter for SmolLM2-1.7B-Instruct. Both target autoformalization: translating English into first-order logic and checking whether a conclusion follows from its premises. Both run locally,

webAI Releases TwIL-LM: A 1.7B and 3B Formal-Logic Model Family for Autoformalization on Local Hardware Read More »

Implementing a MiniMax-H3 Multimodal Video and Audio Generation Pipeline with ComfyUI APIs

In this tutorial, we implement an end-to-end MiniMax-H3 video generation workflow using ComfyUI as a headless inference backend. We configure the environment around GPU memory, disk capacity, model precision, resolution, duration, sampling strategy, and multiple generation modes, while dynamically selecting an appropriate weight profile based on the available hardware. We install and launch ComfyUI programmatically,

Implementing a MiniMax-H3 Multimodal Video and Audio Generation Pipeline with ComfyUI APIs Read More »

Meta AI Releases Muse Glimmer: A 30B Open-Weights Agentic Model That Runs on One Consumer GPU

Meta has released Muse Glimmer, a 30-billion-parameter multimodal model distilled from Muse Spark. It is tuned for always-on local agent workflows, and ships under Apache 2.0. A 30B model normally needs over 55 GB of memory at full precision. Meta compresses it to roughly 4-bit, then adds block-level speculative decoding so it answers fast enough

Meta AI Releases Muse Glimmer: A 30B Open-Weights Agentic Model That Runs on One Consumer GPU Read More »

ByteDance Seed Introduces SeedRealtime: a Native Audio-Visual Full-Duplex LLM That Watches, Listens and Speaks in One Model

ByteDance’s Seed team has introduced SeedRealtime, a native audio-visual full-duplex LLM. The model fuses audio, video and text in a single unified architecture. It interacts in real time over continuous multimodal streams, rather than one turn at a time. Seed positions it as a step toward omni-modal interaction, and claims three breakthroughs: joint audio-visual understanding,

ByteDance Seed Introduces SeedRealtime: a Native Audio-Visual Full-Duplex LLM That Watches, Listens and Speaks in One Model Read More »

NVIDIA Releases NemotronLabs VoiceChat 11B: An Open Full-Duplex Speech-to-Speech Model with ~450 ms Turn-Taking and Live Tool Calling

NVIDIA has released NemotronLabs VoiceChat 11B, an open 11B end-to-end speech-to-speech model for real-time, full-duplex conversation. Instead of chaining ASR, an LLM, and TTS, it performs streaming speech understanding and speech generation in one unified network. That removes the multi-model orchestration and API handoffs a cascaded stack requires, and cuts end-to-end latency: measured smooth turn-taking

NVIDIA Releases NemotronLabs VoiceChat 11B: An Open Full-Duplex Speech-to-Speech Model with ~450 ms Turn-Taking and Live Tool Calling Read More »

Top LLM Observability and Evaluation Platforms in 2026: Langfuse, LangSmith, Braintrust, Arize, and More Compared

LLM applications fail in ways traditional software does not. The same prompt can produce different outputs. A retrieval step can return the wrong document while every HTTP status reads 200. An agent can loop through fourteen tool calls, burn thousands of tokens, and deliver a confidently wrong answer. Standard application performance monitoring (APM) alone does

Top LLM Observability and Evaluation Platforms in 2026: Langfuse, LangSmith, Braintrust, Arize, and More Compared Read More »

Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size

Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that treats content moderation as a single yes/no question rather than a fixed taxonomy of harm categories. Most guardrail models bake their category list into the weights, so re-targeting one to a new deployment context means retraining — and the same content

Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size Read More »